NVIDIA Sports Intelligence Playbooks - AVLM
This repository provides a starter kit for sports-intelligence built on NVIDIA AI stack: playbooks, training recipes, and launch scripts using Multimodal Language Models.
Public recipes cover generic fine-tuning; these playbooks are a sports-focused multimodal baseline with video/audio data, eval, and distributed train/infer workflows wired in. The training and inference scripts themselves are still generic enough to reuse for other multimodal applications beyond sports.
Model compatibility: Current recipes and configurations have been tested with the reference model documented in the training guide. The NeMo AutoModel stack supports additional models, and support for additional multimodal models is planned after testing confirms they meet our quality bar for sports intelligence.
What you get
- End-to-end path: annotation → QA/MCQ data prep → SFT/LoRA → inference → evaluation
- Video+audio recipes with resolution and frame-sampling knobs suited to sports clips
- Measurable eval: per-class MCQ plus LLM-judge for open-ended answers
- Reproducible Slurm/generic launches, checkpoint conversion/parity, and inference→eval pipelines
- Side-by-side AutoModel vs Megatron-Bridge (SFT and LoRA)
- Practical notes from debugging and optimizing multimodal training for sports
Docs: Sports Intelligence documentation
 See the full-length video demo on our tennis checkpoint HuggingFace repo.
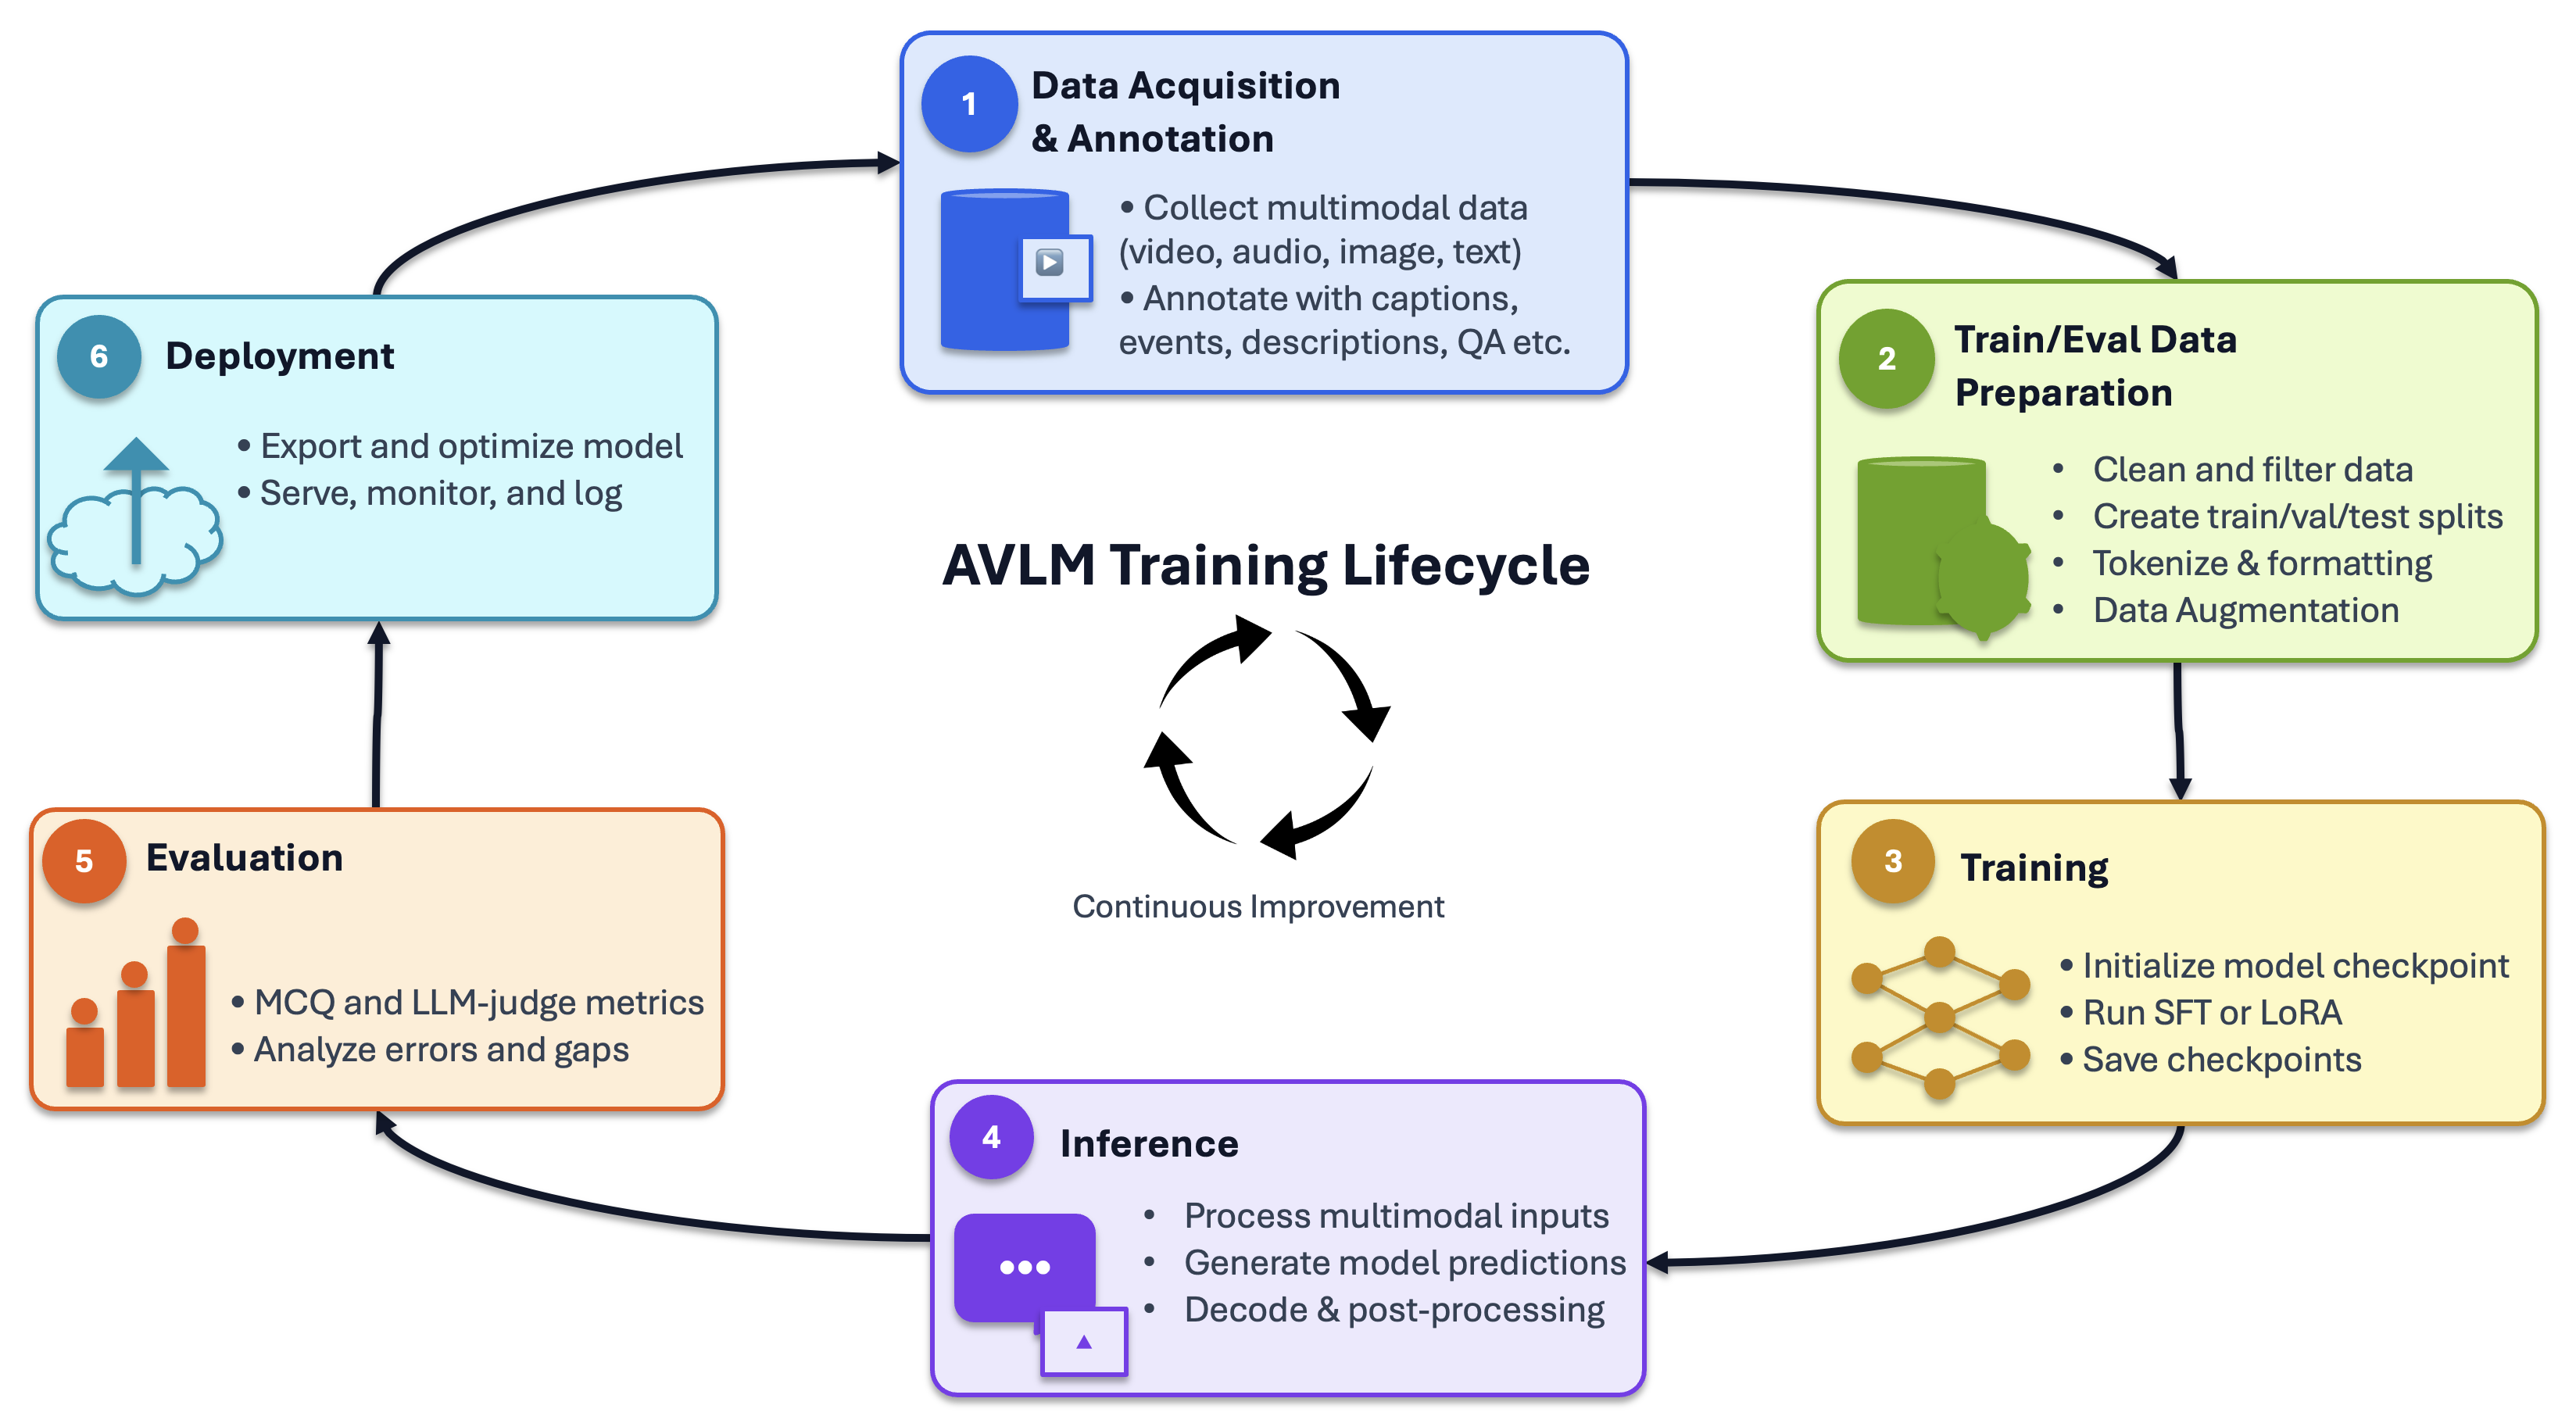
The playbooks cover one full AVLM round—from collecting and annotating multimodal sports data, through train/eval preparation, SFT/LoRA training, inference, and evaluation, with deployment as the next step. The repository layout below maps each stage to concrete scripts and guides; the two training stacks are interchangeable options for the training and inference steps.
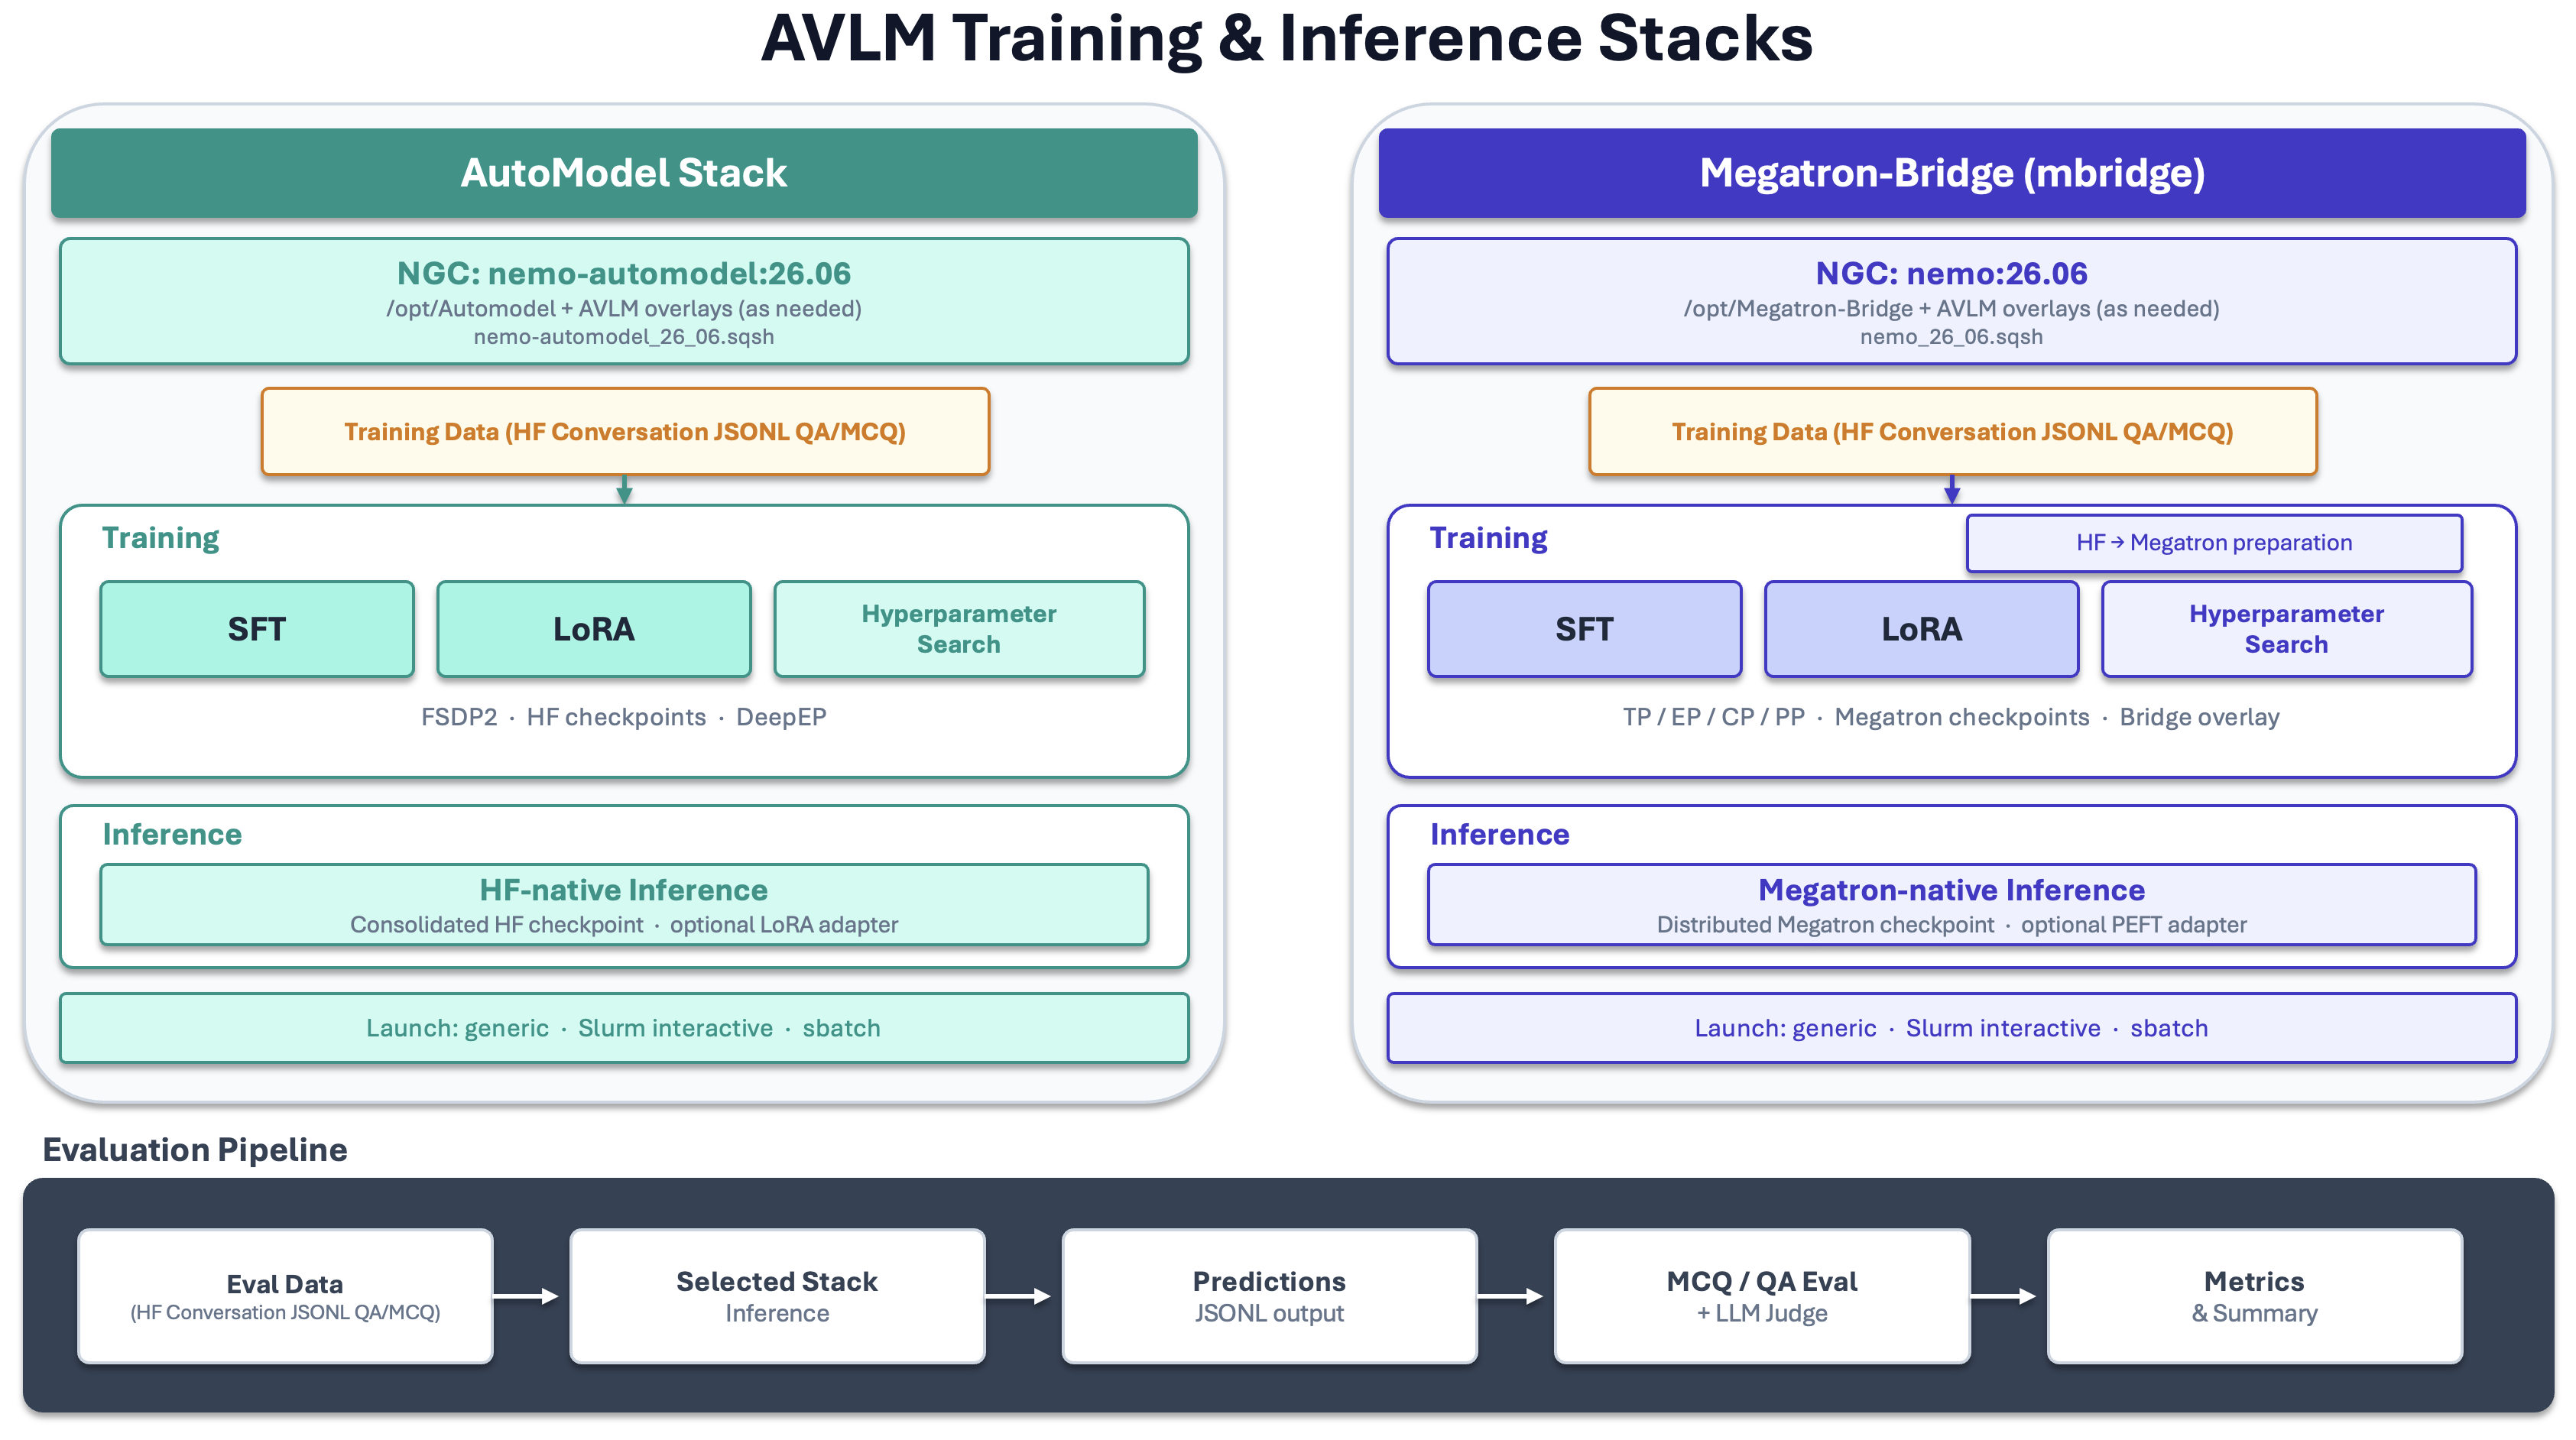
Two training stacks:
- NeMo AutoModel — full SFT and LoRA; generic (local) and Slurm launchers; container
nemo-automodel:26.06.00. - Megatron-Bridge — full SFT and LoRA; generic (local) and Slurm launchers; container
nemo:26.06.00.
AutoModel trains on Hugging Face checkpoints and is the easier on-ramp for most users. Megatron-Bridge uses Megatron-format checkpoints and richer parallelism (after HF→Megatron conversion), which is better when you need that scale and control.
Repository layout
| Area | Component | Path |
|---|---|---|
| Data prep | QA / MCQ generation | avlm/data_prep_example/tennis/ |
| Training | AutoModel SFT | avlm/training/automodel/sft/ (generic/ + slurm/) |
| AutoModel LoRA | avlm/training/automodel/lora/ (generic/ + slurm/) | |
| Megatron-Bridge SFT | avlm/training/megatron-bridge/sft/ (generic/ + slurm/) | |
| Megatron-Bridge LoRA | avlm/training/megatron-bridge/lora/ (generic/ + slurm/) | |
| HF ↔ Megatron conversion | avlm/training/megatron-bridge/hf_megatron_conversion/ | |
| Hyperparameter search | avlm/training/hyperparam_search/ | |
| Inference | AutoModel | avlm/inference/automodel/ (configs/ + slurm/) |
| Megatron-Bridge | avlm/inference/megatron-bridge/ (configs/ + slurm/) | |
| Evaluation | MCQ eval | avlm/evals/mcq/ |
| LLM-judge eval | avlm/evals/qa_llm_judge/ | |
| Dependencies | DeepEP | wheels/deepep/ (pre-Hopper / A100; post-Hopper ships in nemo-automodel) |
Getting started
Full walkthrough: training setup.
Clone this repo, cd to the root, and run launchers from there. Choose one stack under avlm/training/ — AutoModel (HF checkpoints) or Megatron-Bridge (Megatron checkpoints + Bridge recipes).
Containers
| Stack | NGC container |
|---|---|
| AutoModel | nemo-automodel:26.06.00 |
| Megatron-Bridge | nemo:26.06.00 |
Pull and run with Docker (e.g. for local GPUs / generic/ training):
# NeMo AutoModel
docker pull nvcr.io/nvidia/nemo-automodel:26.06.00
docker run --gpus all -it --rm \
  -v "$PWD":/workspace -w /workspace \
  nvcr.io/nvidia/nemo-automodel:26.06.00 bash

# NeMo Framework (Megatron-Bridge)
docker pull nvcr.io/nvidia/nemo:26.06.00
docker run --gpus all -it --rm \
  -v "$PWD":/workspace -w /workspace \
  nvcr.io/nvidia/nemo:26.06.00 bash
On Slurm clusters that use enroot, convert each NGC image once to a .sqsh squashfs file for job launches (no Docker daemon on compute nodes). Then set CONTAINER_IMAGE in launch_local.yaml to that .sqsh path:
# NeMo AutoModel
enroot import -o nemo-automodel_26_06.sqsh \
  docker://nvcr.io/nvidia/nemo-automodel:26.06.00

# NeMo Framework (Megatron-Bridge)
enroot import -o nemo_26_06_00.sqsh \
  docker://nvcr.io/nvidia/nemo:26.06.00
SFT and LoRA dirs share the same shape: configs/ (recipe YAML), generic/ (train when GPUs are already up), slurm/ (interactive + sbatch). Copy launch.yaml → launch_local.yaml, then set CONTAINER_IMAGE, CACHE_DIR, and cluster fields. Framework code defaults to the container install (/opt/Automodel or /opt/Megatron-Bridge); optional git bootstrap is only for pinning a different upstream commit (see the stack guides).
Suggested first path
- Edit the recipe YAML (train/val JSONL paths and video root).
- Smoke on 1 node × 8 GPUs via
generic/or Slurm interactive before multinodesbatch. - AutoModel / DeepEP: post-Hopper images already include DeepEP; on pre-Hopper (e.g. A100) the matching wheel under
wheels/deepep/is installed automatically when the recipe usesdispatcher: deepep.
Video and audio decoding
Codec binaries are not included in this release. Training, inference, and data-prep workflows may install decode dependencies via pip when they are missing from the NeMo container, including:
- decord — video frame decoding
- imageio-ffmpeg — prebuilt FFmpeg when system FFmpeg is not available
- librosa — audio decoding (with audioread fallbacks)
See THIRD_PARTY_NOTICES for full package lists, install behavior, and data-prep requirements. FFmpeg (system install or via imageio-ffmpeg) may include LGPL- and/or GPL-licensed components; review those terms before redistribution.
License
All NVIDIA-authored code and published documentation in this repository is licensed under the Apache License, Version 2.0 (Apache-2.0). See LICENSE for the full license text. The GitHub Pages site is served from prebuilt HTML under docs/.
Third-party components used by the playbooks (Python dependencies, decode libraries, optional wheels, and NGC container baseline) are listed in THIRD_PARTY_NOTICES.
Contributions
This project is currently not accepting contributions.