


News · Quick start · Models · Options
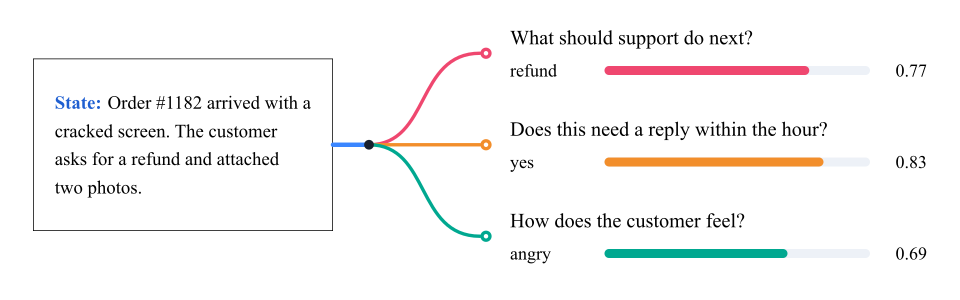
Flide is fast inference infrastructure for Jev-style decision models. With exact state forking it is up to 9.5 times faster than vLLM and SGLang, and every answer is the one the model gives the question alone. It serves the Jev /v1/systemone API.
🔥 News
- 🔥 2026-11-09 We added Ainvest-Decision, Darwin-27B-RSI-Decision and KnowLine-31B-Gen1.5 in Flide 0.1.10, and the KnowLine family now reads images.
- 🔥 2026-11-09 We added pplx-decider-v1.1-27b and JEV-35B in Flide 0.1.9, and
/v1/systemonenow takes several requests in one body. - 🔥 2026-11-08 We added two decision model families in Flide 0.1.8, including AutoTrust and Clef, and also drex-max-v1.
Earlier news
- 🔥 2026-11-02 We released our paper Flide: Accelerating Decision Inference with Exact State Forking on arXiv.
- 🔥 2026-10-29 We added three decision model families in Flide 0.1.7, including SynACK Decide, Wald and Xor, and Gemma 4 mixture-of-experts models such as KnowLine-26B-A4B.
- 🔥 2026-10-29 We added two decision model families in Flide 0.1.6, including Drex and KnowLine, and
flide verifychecks exact forking on your own model and requests. - 🔥 2026-10-28 We added six decision model families in Flide 0.1.5, including Jeffan, JevAny, Kev, Lychee, pplx-decider and StartLux, and images for Lumma and mammoth.
- 🔥 2026-10-26 We added five decision model families in Flide 0.1.4, including cerno, JADE, Linne, mammoth and Sieve, and also Quyet-1.0-Large.
- 🔥 2026-10-26 We added eight decision model families in Flide 0.1.3, including AJev, Bespoke-Nimble, Darwin, jiwo, Lumma, mogan, Quyet and Senova, and LoRA adapters now serve as they are.
- 🔥 2026-10-25 We added two decision model families in Flide 0.1.2, including Intern-Decision and torchcast, and a question now takes up to 256 options.
- 🔥 2026-10-24 We released Flide 0.1.0 on PyPI, serving Qwen3.5 and Gemma 4 chat models and the OneJev and Open-Jev decision models. Welcome to have a try.
Quick start
See the docs for every model, images, the API and all options.
uv venv -p 3.12 && source .venv/bin/activate
uv pip install flide torchvision
flide serve --model OmniJev/OneJev1.6-0.8B
Any model in the model table starts the same way, for example Perplexity's decision model.
flide serve --model perplexity-ai/pplx-decider-flash-v1.2Every one of them answers this request.
curl http://localhost:8000/v1/systemone -H "Content-Type: application/json" -d '{
  "state": "Order #1182 arrived with a cracked screen. The customer asks for a refund and attached two photos.",
  "questions": {
    "action": {"type": "choice", "instructions": "What should support do next?",
               "criteria": {"refund": "refund the order", "replace": "send a replacement", "escalate": "ask a human"}},
    "urgent": {"type": "noul", "instructions": "Does this need a reply within the hour?"}
  }
}'
Models
The last three columns say how much faster Flide answers one request than the engine its release ships, as the median latency over the requests of each workload on one H200, where DI is the Decision Index. The chat models run against the faster of vLLM and SGLang, and OneJev against qev, the engine it used before Flide. KnowLine 35B runs with --quantize fp8, as its release serves it in FP8. A value marked ~ is the average over the sizes tested.
| Model | Inputs | DI | MultiRC | QuALITY |
|---|---|---|---|---|
| Ainvest-Decision | text | 1.4× | 1.3× | 1.3× |
| AJev | text | 3.7× | 9.3× | 2.6× |
| AutoTrust | text, images | ~3.2× | ~7.6× | ~1.6× |
| Bespoke-Nimble | text | 2.6× | 2.1× | 1.6× |
| cerno | text | ~4.1× | ~8.6× | 1.1× |
| Clef | text, images | 1.3× | 1.0× | 1.0× |
| Darwin | text | ~1.4× | ~4.2× | ~1.2× |
| Drex | text, images | ~2.8× | ~6.2× | ~1.5× |
| Gemma 4 | text, images | ~1.3× | ~1.7× | ~1.0× |
| Intern-Decision | text, images | 4.4× | 1.1× | 1.5× |
| JADE | text | 2.0× | 9.2× | 1.7× |
| Jeffan | text | 3.1× | 2.6× | 1.9× |
| JevAny | text, images | 1.5× | 5.8× | 1.2× |
| jiwo | text | ~1.9× | ~5.9× | 1.8× |
| Kev | text | ~7.9× | ~1.5× | ~1.7× |
| KnowLine | text, images | ~1.4× | ~4.3× | ~1.5× |
| Linne | text | 2.3× | 8.6× | 1.2× |
| Lumma | text, images | 1.7× | 7.1× | 1.2× |
| Lychee | text | 1.4× | 1.5× | 1.4× |
| mammoth | text, images | ~4.3× | ~2.8× | ~1.8× |
| mogan | text | 1.6× | 8.5× | 1.8× |
| OneJev | text, images, video | ~6.8× | 7.3× | 4.7× |
| Open-Jev | text | 4.2× | 5.0× | ~1.5× |
| pplx-decider | text, images | ~2.2× | ~1.4× | ~1.3× |
| Quyet | text | ~3.9× | ~7.1× | ~1.6× |
| Qwen3.5 | text, images | ~2.1× | ~4.8× | ~1.3× |
| Senova | text | 3.1× | 28.1× | 1.2× |
| Sieve | text | 3.0× | 14.3× | 2.6× |
| StartLux | text | 2.6× | 1.1× | 1.2× |
| SynACK Decide | text | 3.3× | 11.9× | 3.0× |
| torchcast | text, images | 1.6× | 8.4× | 1.4× |
| Wald | text | 1.6× | 12.7× | 1.5× |
| Xor | text, images, video | 2.5× | 6.2× | 2.8× |
Options
| Option | What it does |
|---|---|
--session-cache-gb 40 | keeps the states of earlier requests, so an agent's next step reads only what is new |
--batch-invariant | the same bits for a request whatever it is batched with, at some cost in speed |
--quantize fp8 | Qwen3.5 in FP8 on Ada, Hopper and Blackwell GPUs |
--frontends 2 | HTTP, rendering and tokenizing in two processes of their own, for many clients |
License
Apache-2.0. flide/kernels/gdn.py holds a kernel derived from two kernels of
flash-linear-attention (MIT); THIRD_PARTY_NOTICES lists it with
the other code Flide builds on.
Citation
If you use Flide in your research, please cite our paper.
@article{li2026flide,
  title   = {Flide: Accelerating Decision Inference with Exact State Forking},
  author  = {Li, Bobo and Song, Jiajia and Fei, Hao and Hsu, Wynne and Lee, Mong Li},
  journal = {arXiv preprint arXiv:2610.42148},
  year    = {2026}
}