MiniCPM-V & MiniCPM-o · See, hear, and interact on your local devices.
MiniCPM-V 4.7 🤗 35B-A3B 🤗 1B 🤖 MiniCPM-o 4.5 🤗 🤖
Overview · Get started · Resources | 中文 · English
News
- [2026.10.28] 🔥🔥🔥 We open-source the MiniCPM-OCR suite, pairing two models for fast, accurate parsing and result verification: MiniCPM-OCR 1.0 (based on MiniCPM-V 4.6, SOTA on Real5-OmniDocBench and OCRBench v2) and MiniCPM-OCR Jev for result correctness checks.
- 2026-10-15 · We release DSpark speculative decoding heads in BF16 and GGUF for both MiniCPM-V 4.7 variants: 1B (DSpark-BF16, DSpark-GGUF) and 35B-A3B (DSpark-BF16, DSpark-GGUF).
- 2026-10-12 · MiniCPM-V 4.7 released — the first open-source MoE model to run smoothly on-device without compromising performance, setting a new multimodal performance–efficiency Pareto frontier. See what's new.
MiniCPM-V 4.7
MiniCPM-V 4.7 is the latest model in the MiniCPM-V series, available in 35B-A3B and 1B variants. The 35B-A3B variant is the series' first MoE model. Its main features include:
- 🚀 A new performance–efficiency Pareto frontier. The 35B-A3B and 1B variants each advance the performance–efficiency Pareto frontier for multimodal large language models. In Instruct mode, 35B-A3B achieves a higher overall score in less inference time than Qwen3.6 35B-A3B; the 1B variant further improves on MiniCPM-V 4.6's core capabilities and substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency.
- 📱 The first open-source MoE to run smoothly on-device without compromising performance. Powered by the latest Lookahead Expert Scheduling (LES) inference acceleration technique, MiniCPM-V 4.7 35B-A3B becomes the first open-source MoE model to run smoothly on-device without compromising performance, achieving a decoding speed of 13+ tokens/s with just 3 GB of memory on iPhone 17 Pro Max. We also support DSpark speculative decoding, with dedicated heads available for 1B (DSpark-BF16, DSpark-GGUF) and 35B-A3B (DSpark-BF16, DSpark-GGUF).
- 🛠️ Broad platform support and easy customization. MiniCPM-V 4.7 supports iOS, Android, and HarmonyOS, and supports chip platforms from Intel, AMD, Arm, Rockchip, and Houmo, covering a diverse range of mobile devices and local computing scenarios. We also open-source Self-Replay Fine-Tuning (SRFT), helping developers extend model capabilities at low cost while reducing forgetting of existing capabilities.
Significantly Advancing the Performance–Efficiency Pareto Frontier
Overall Performance (35B-A3B, Instruct)
Vision-Language
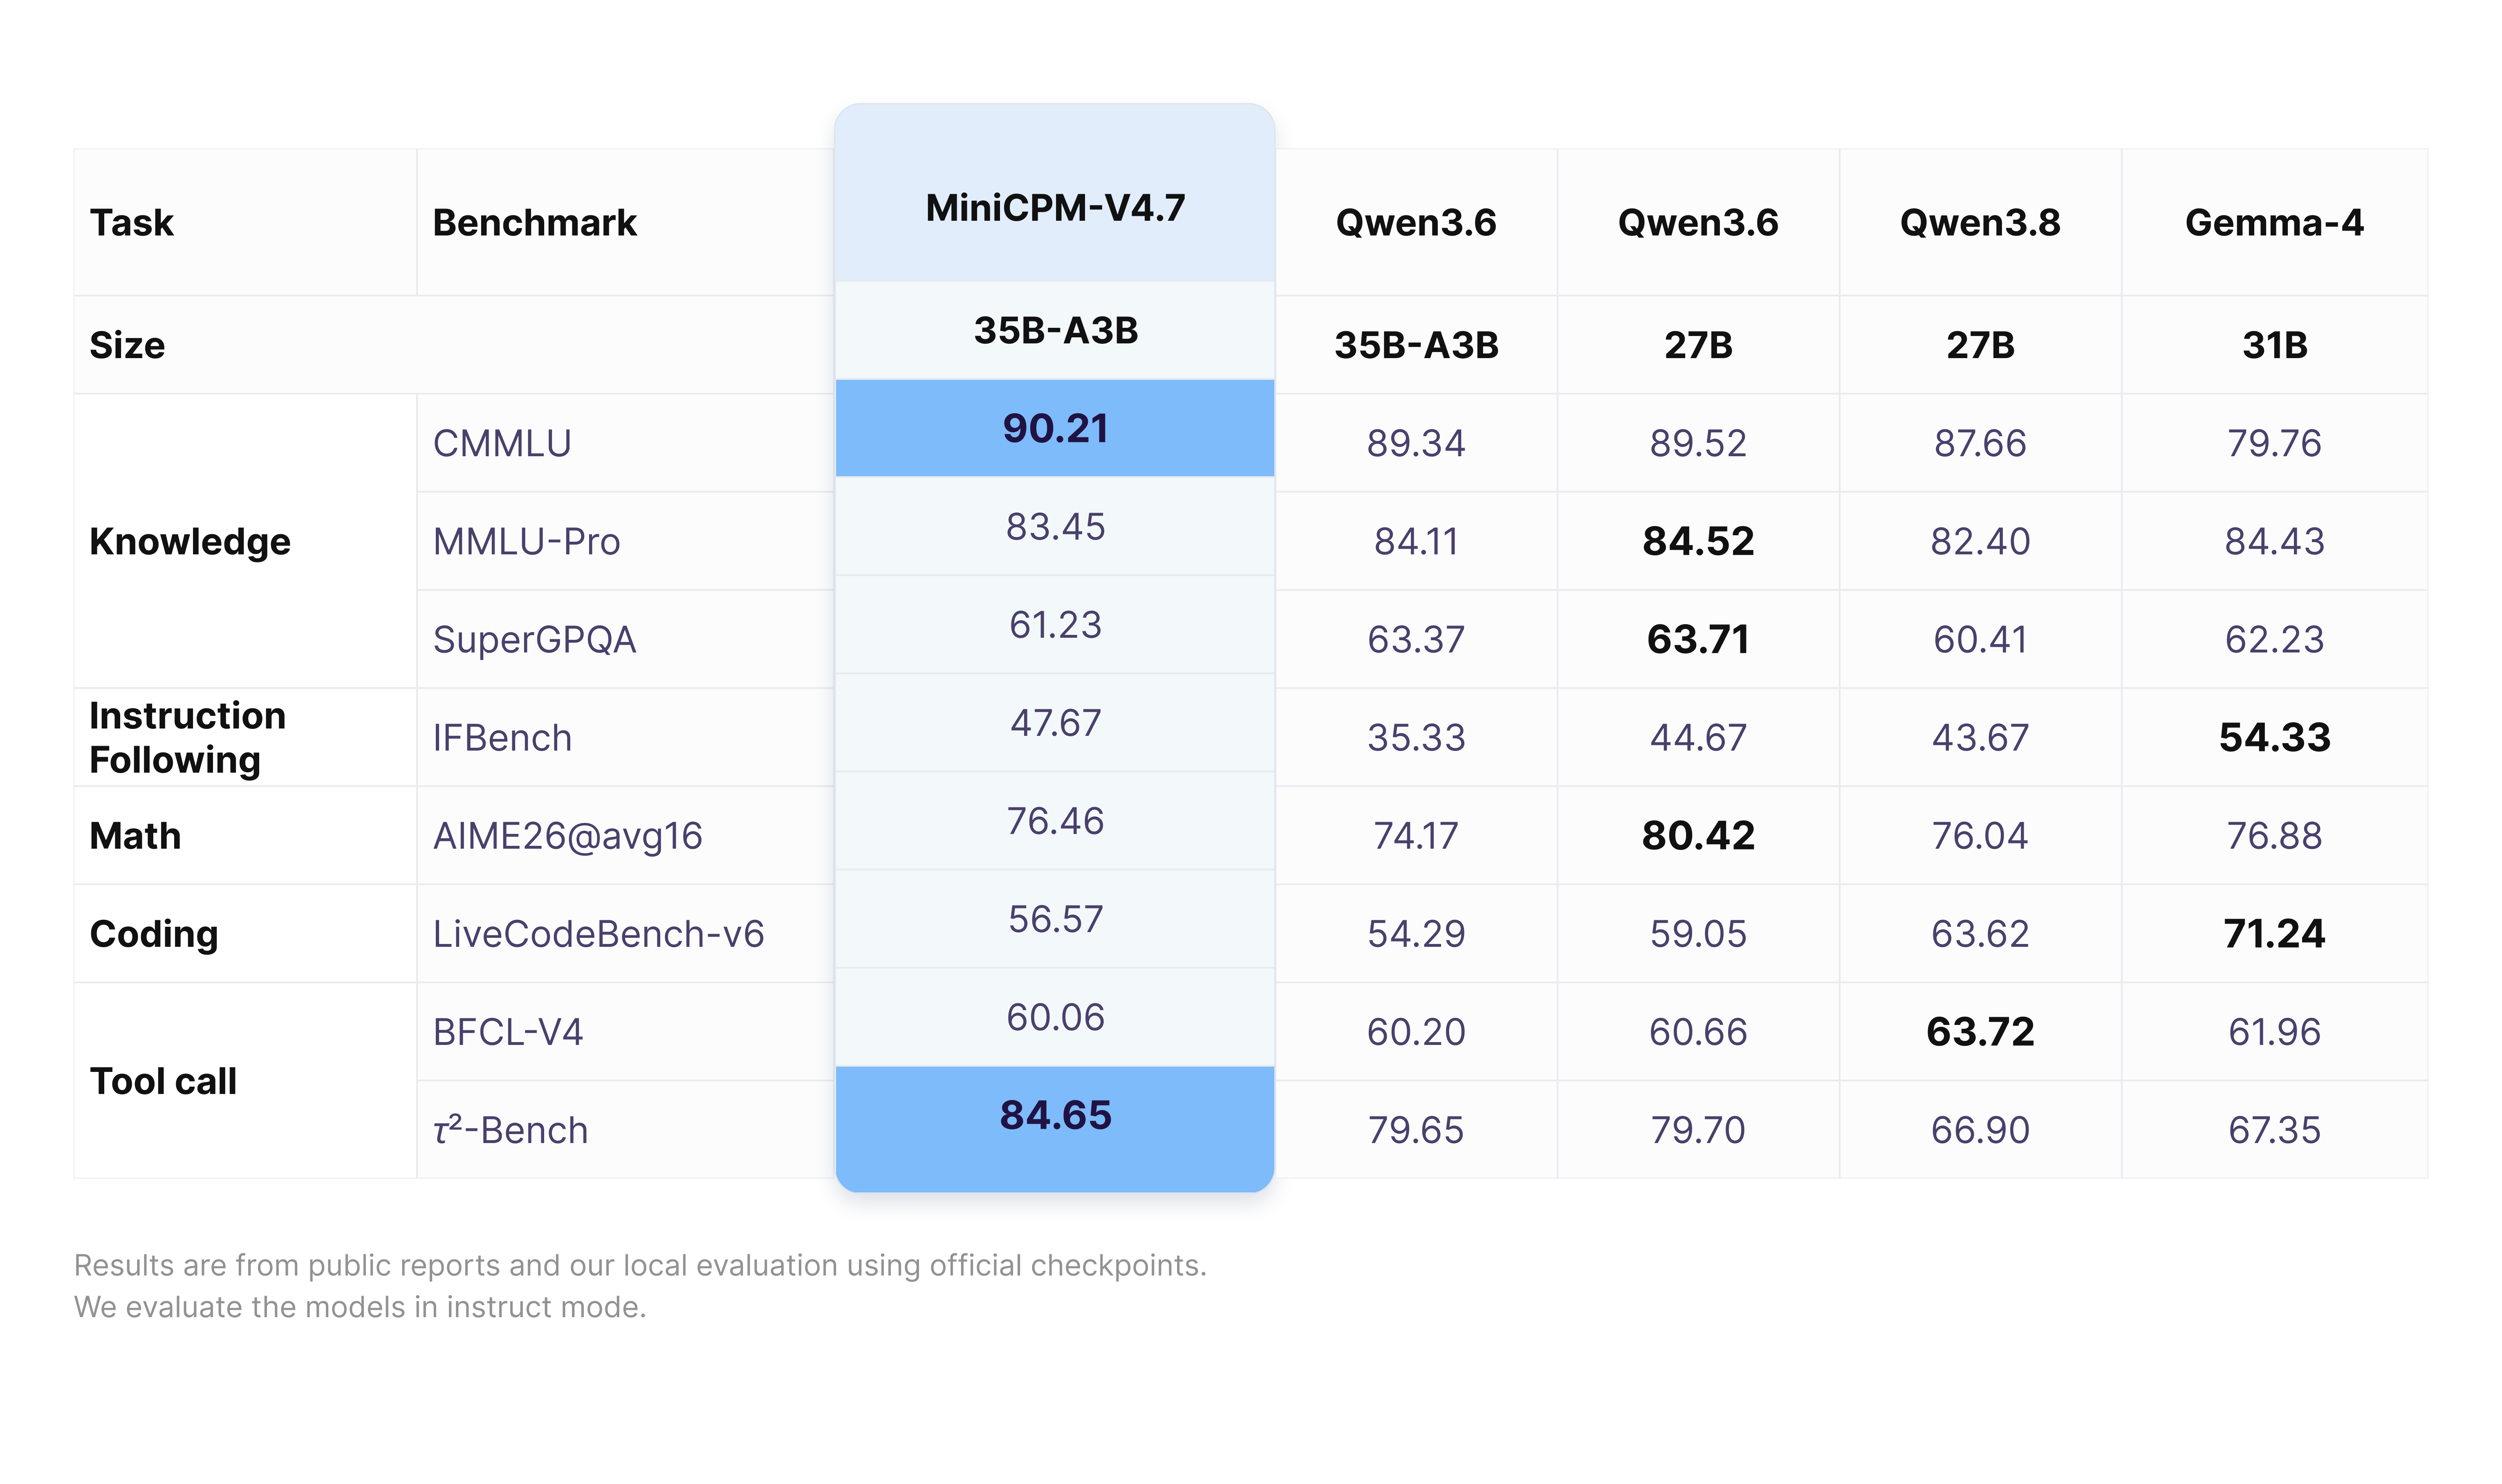
Language
Overall Performance (1B, Instruct)
Smooth On-Device MoE Inference without Compromising Performance
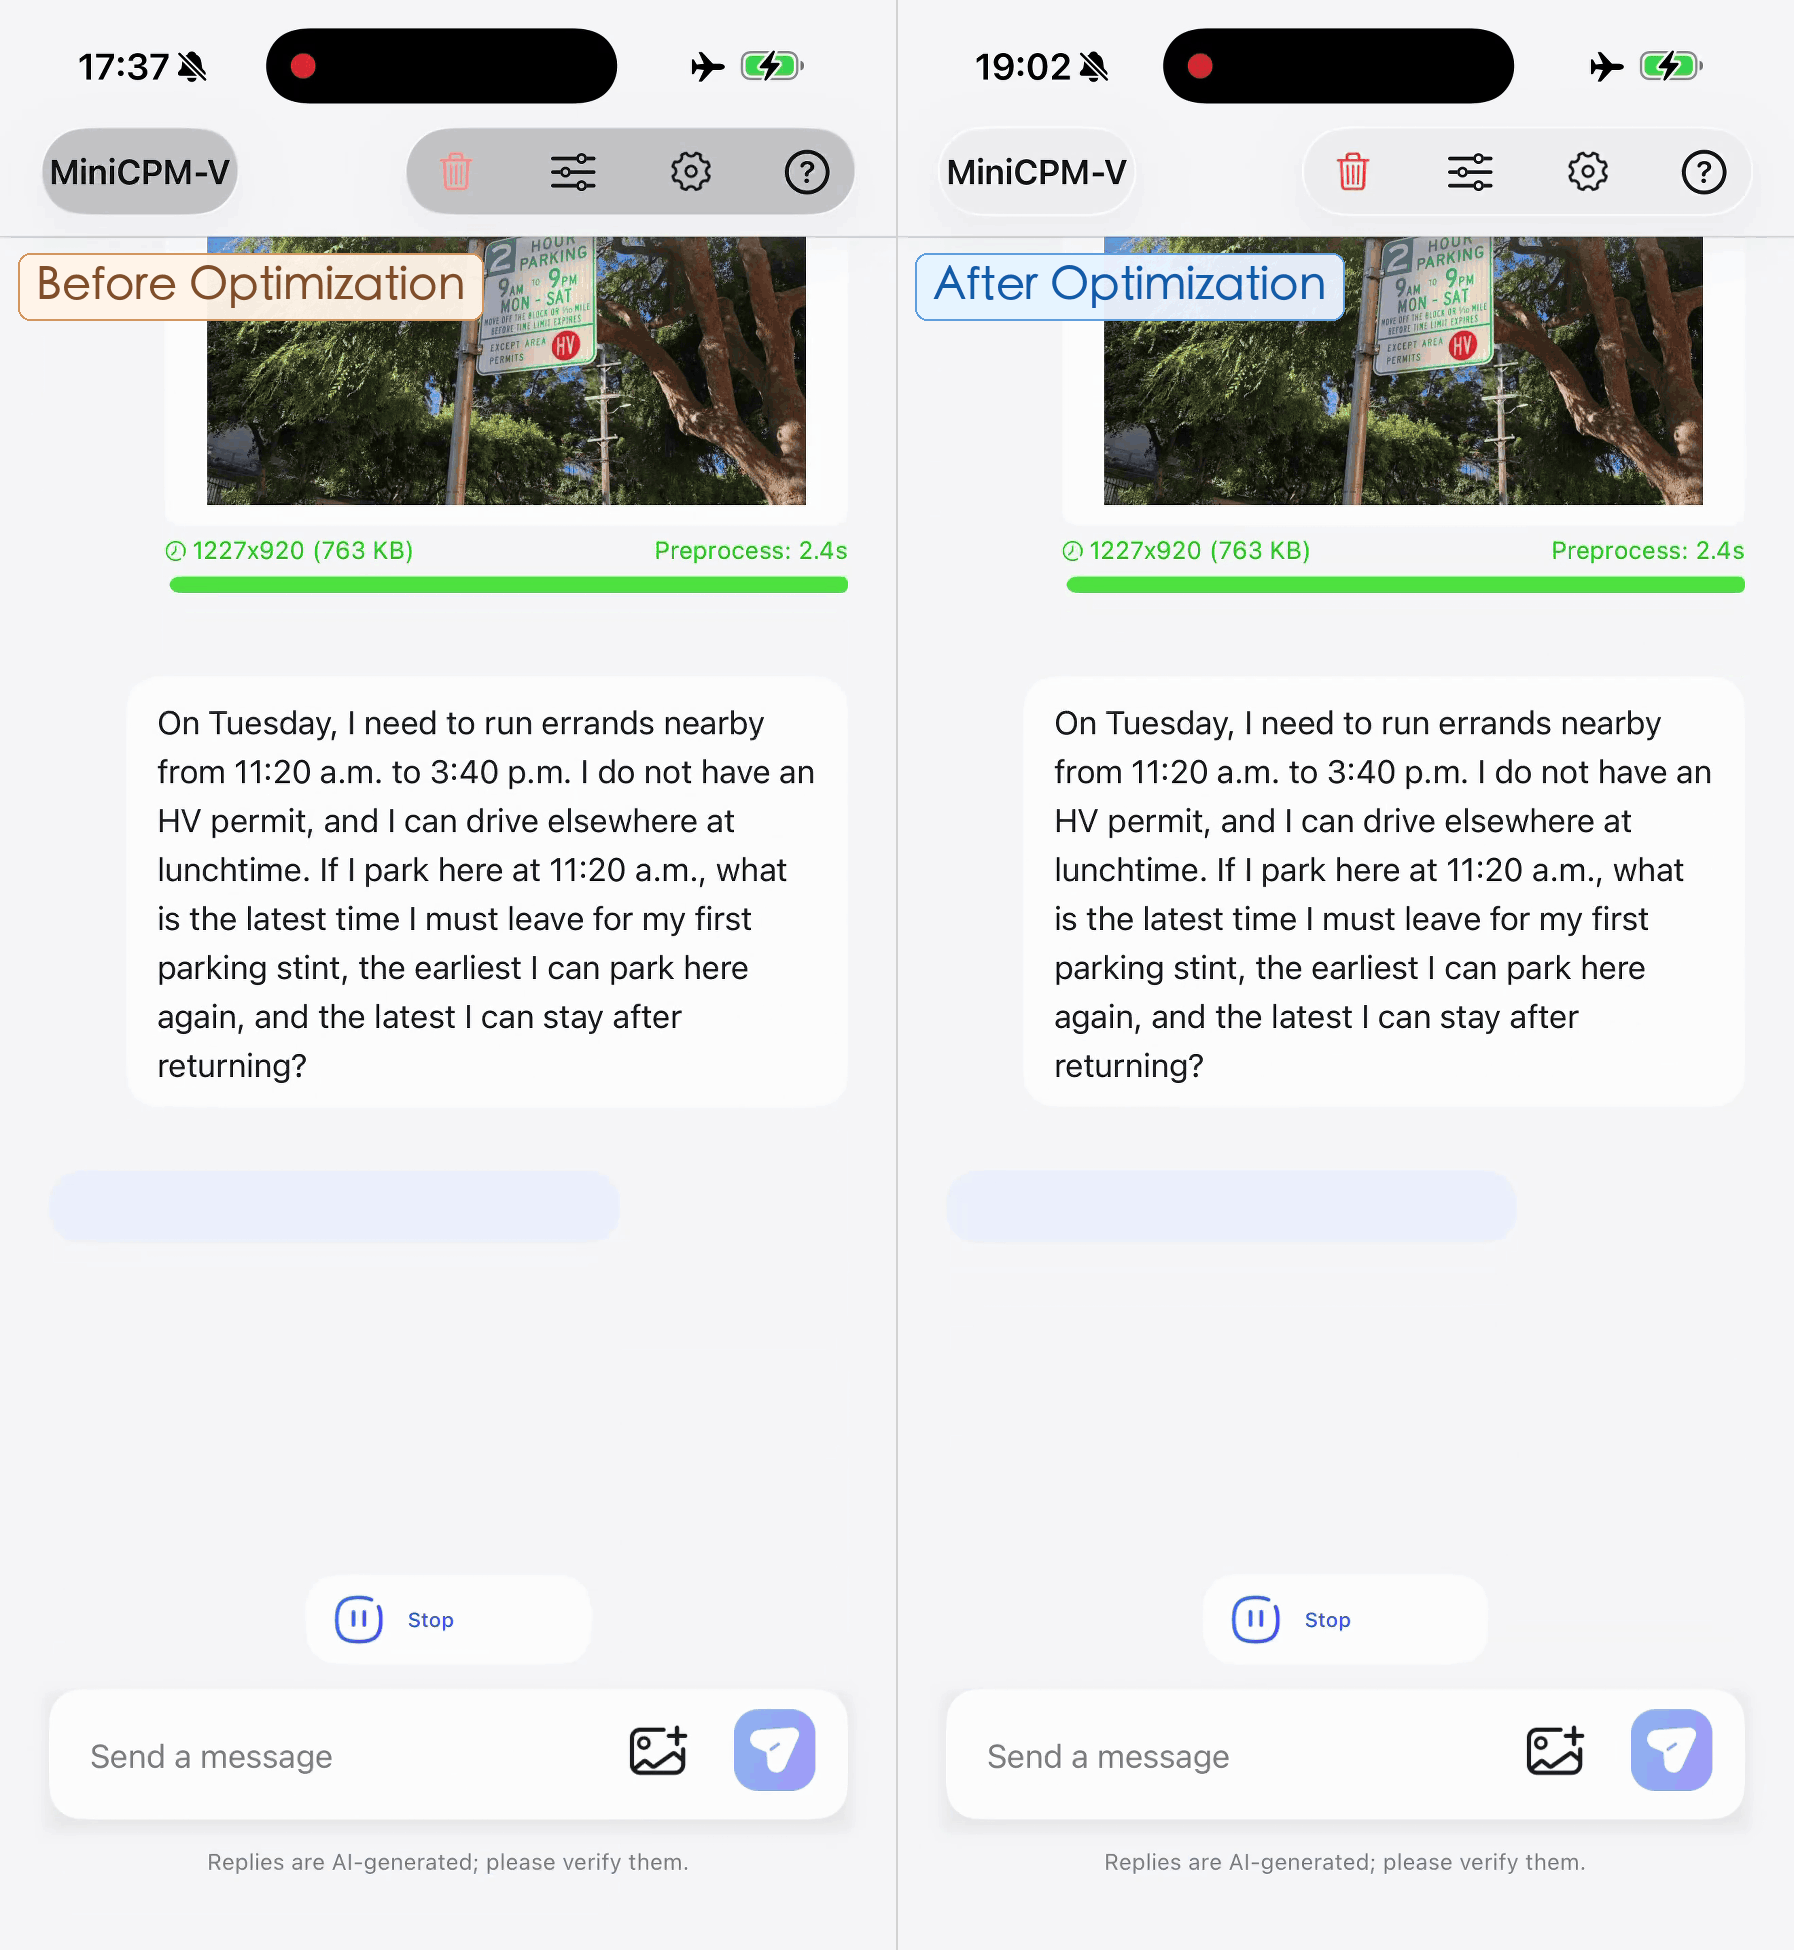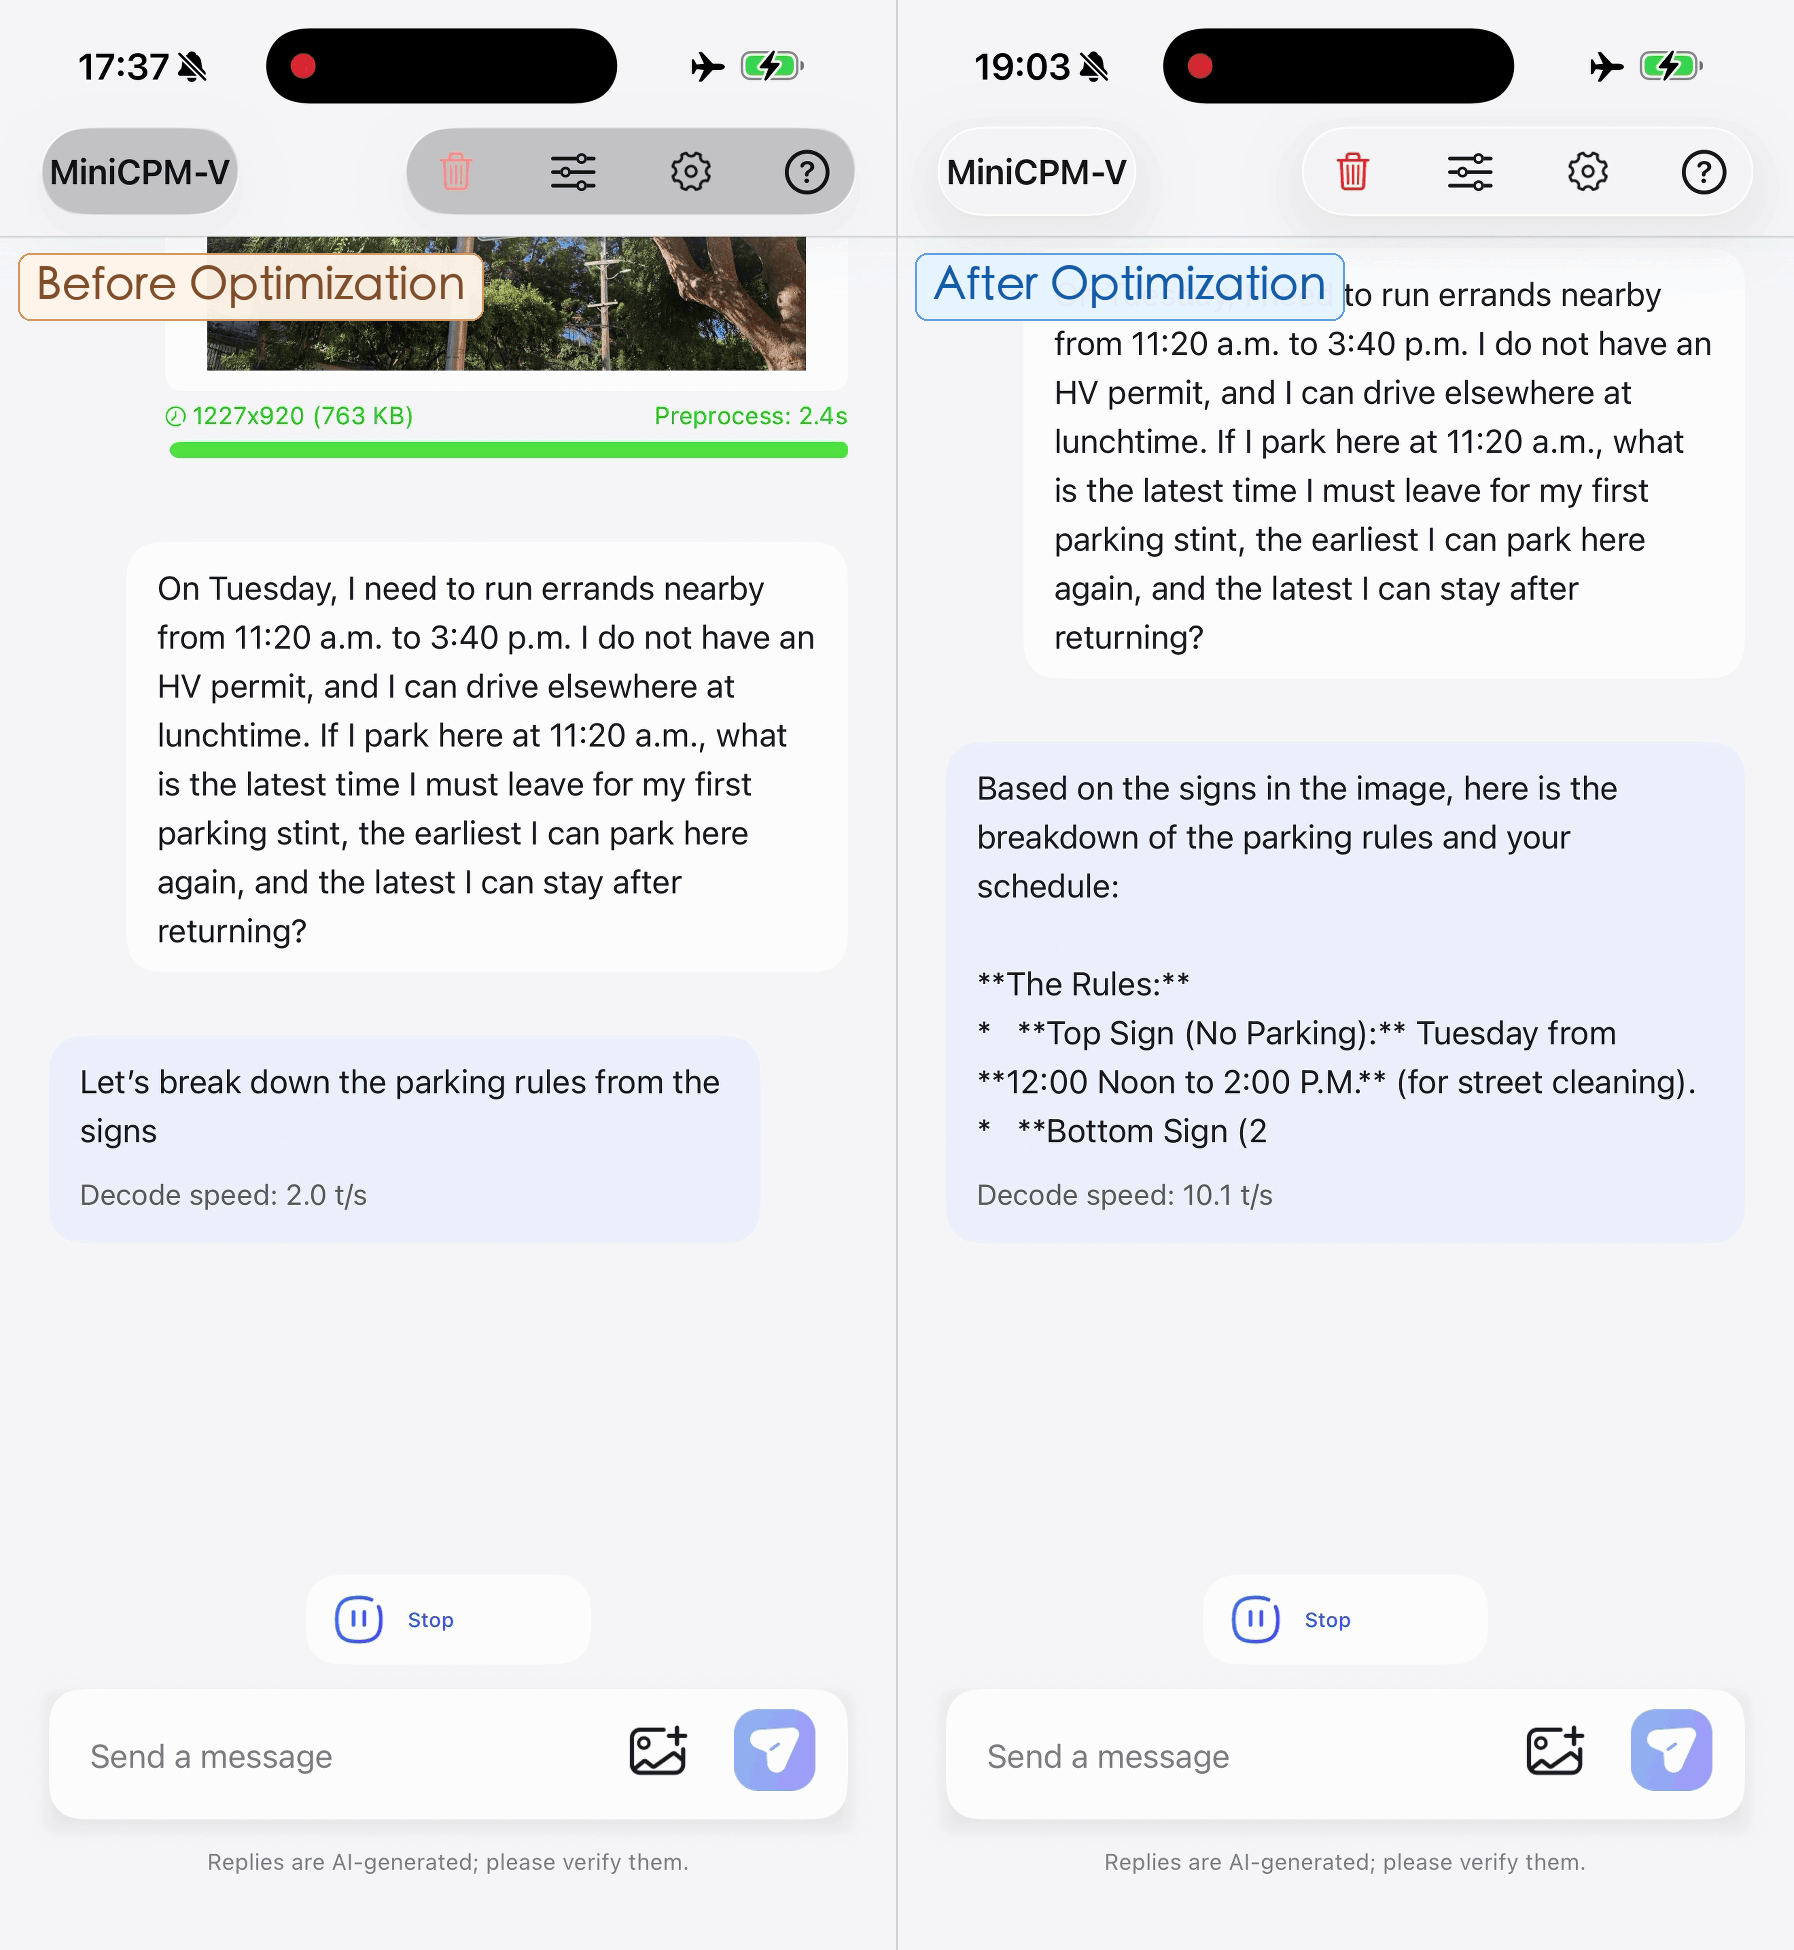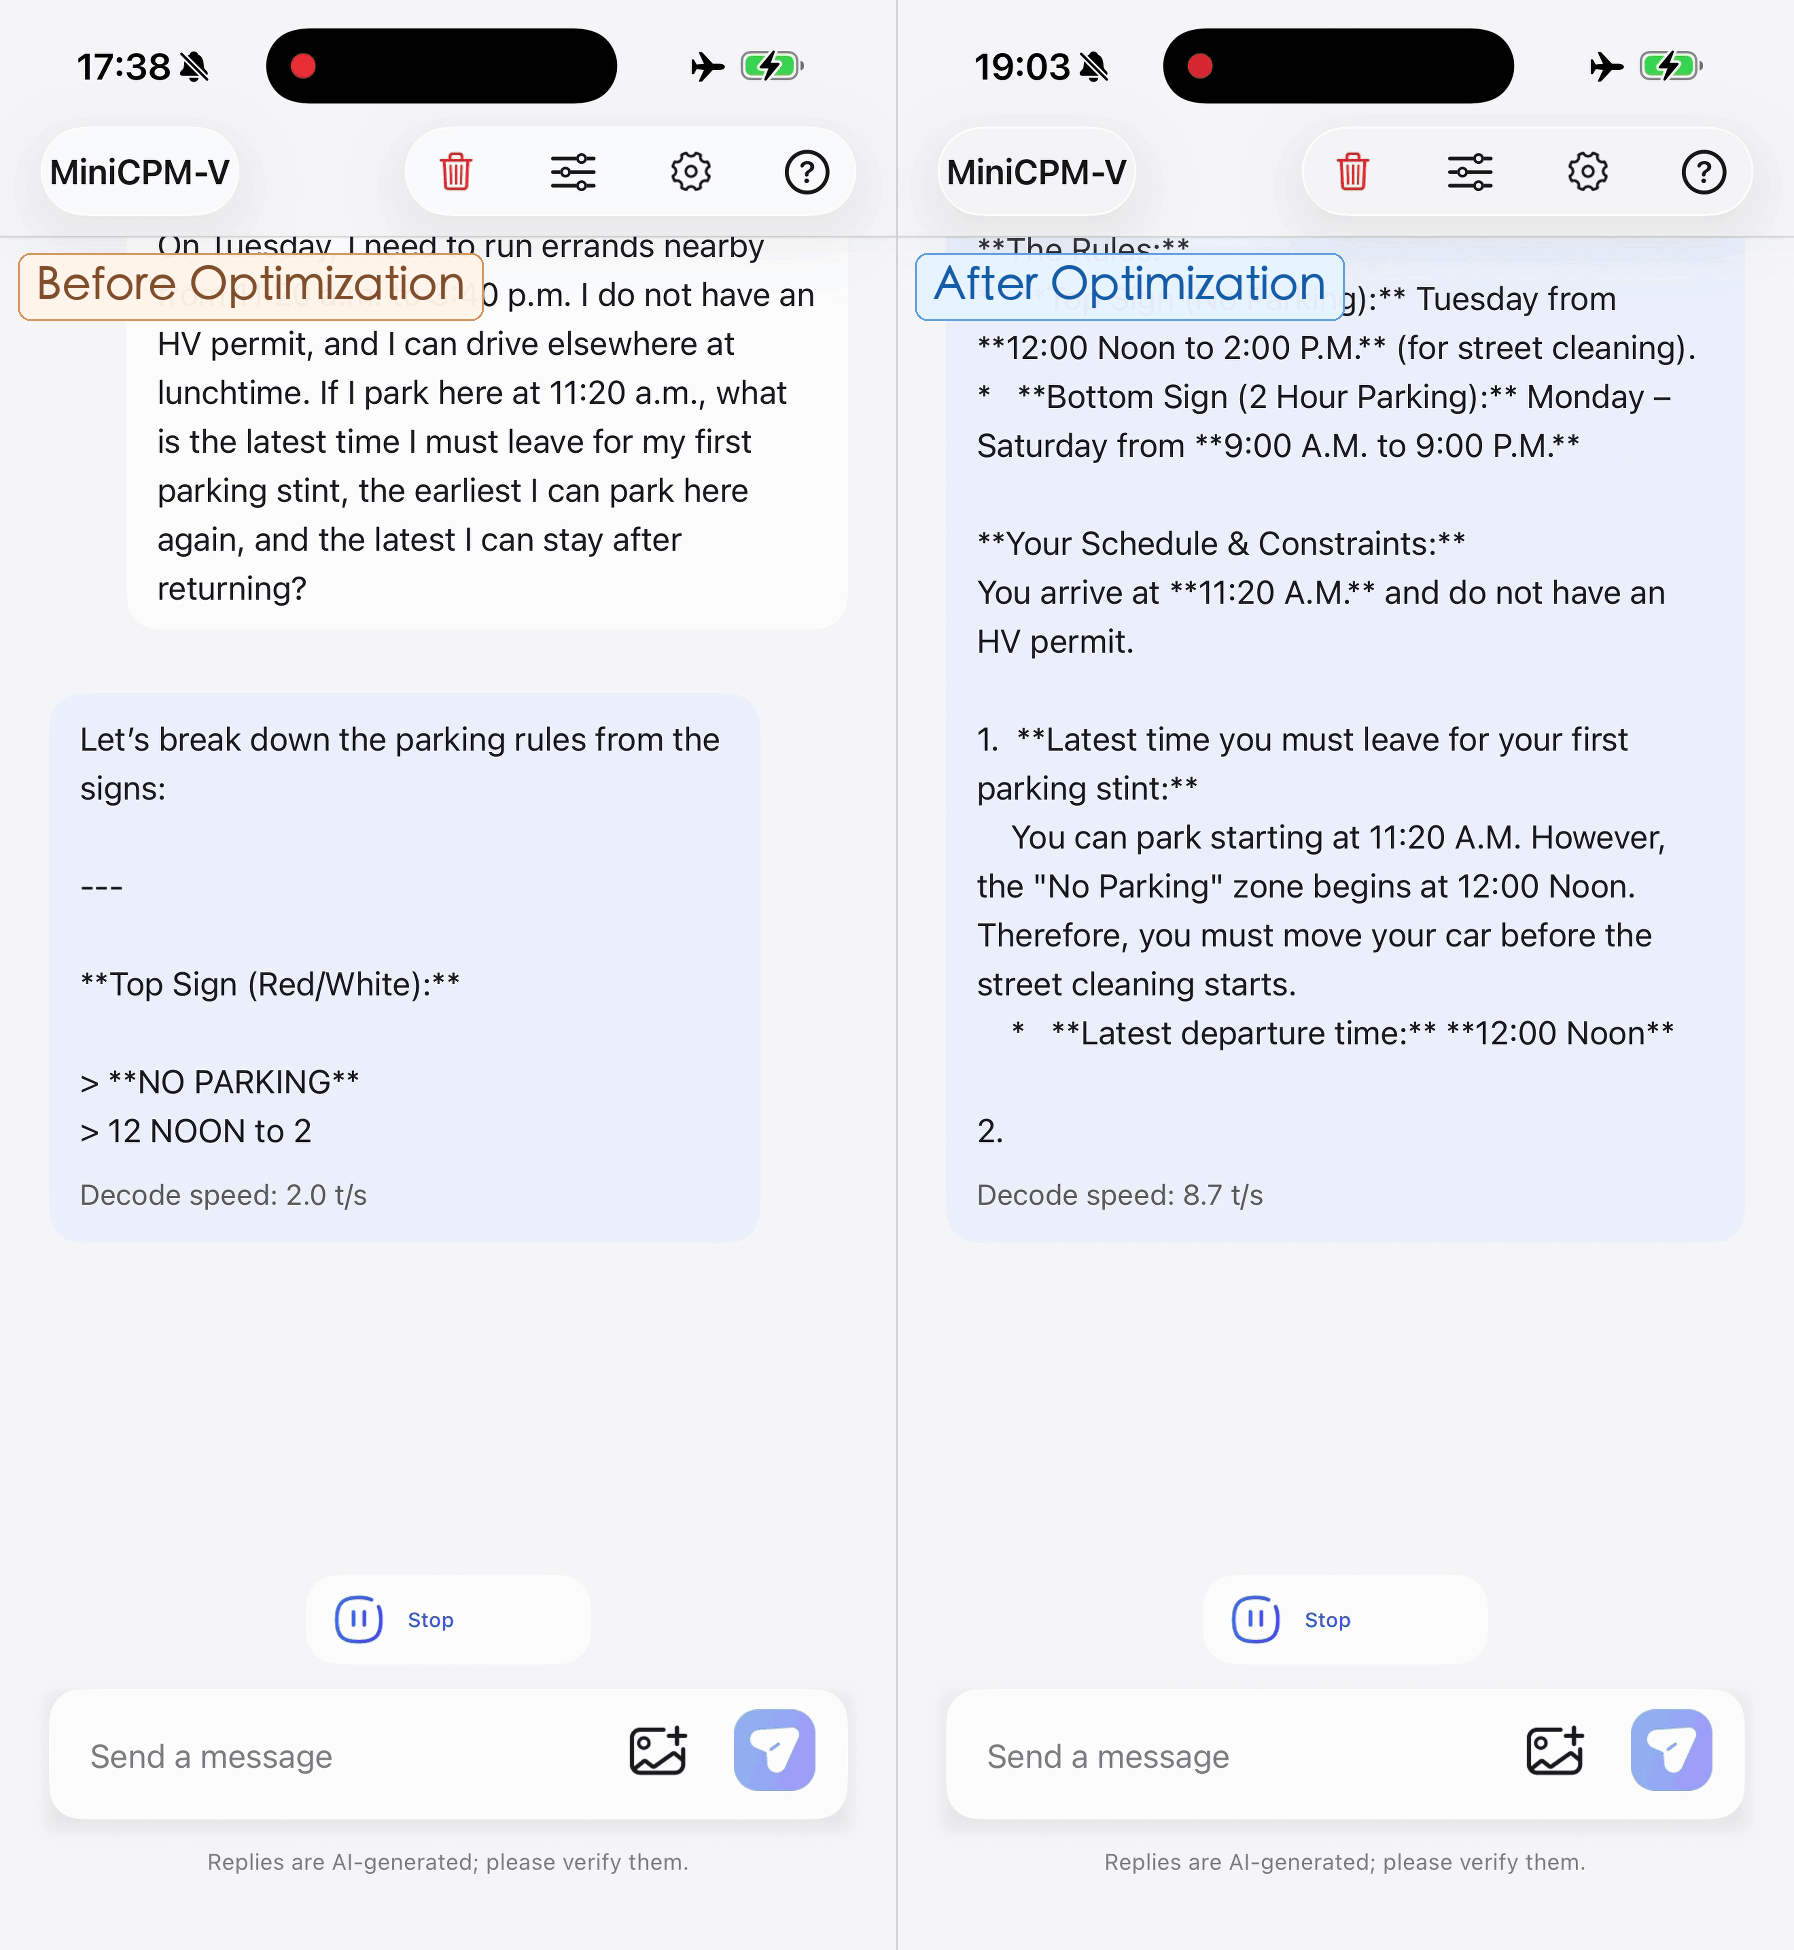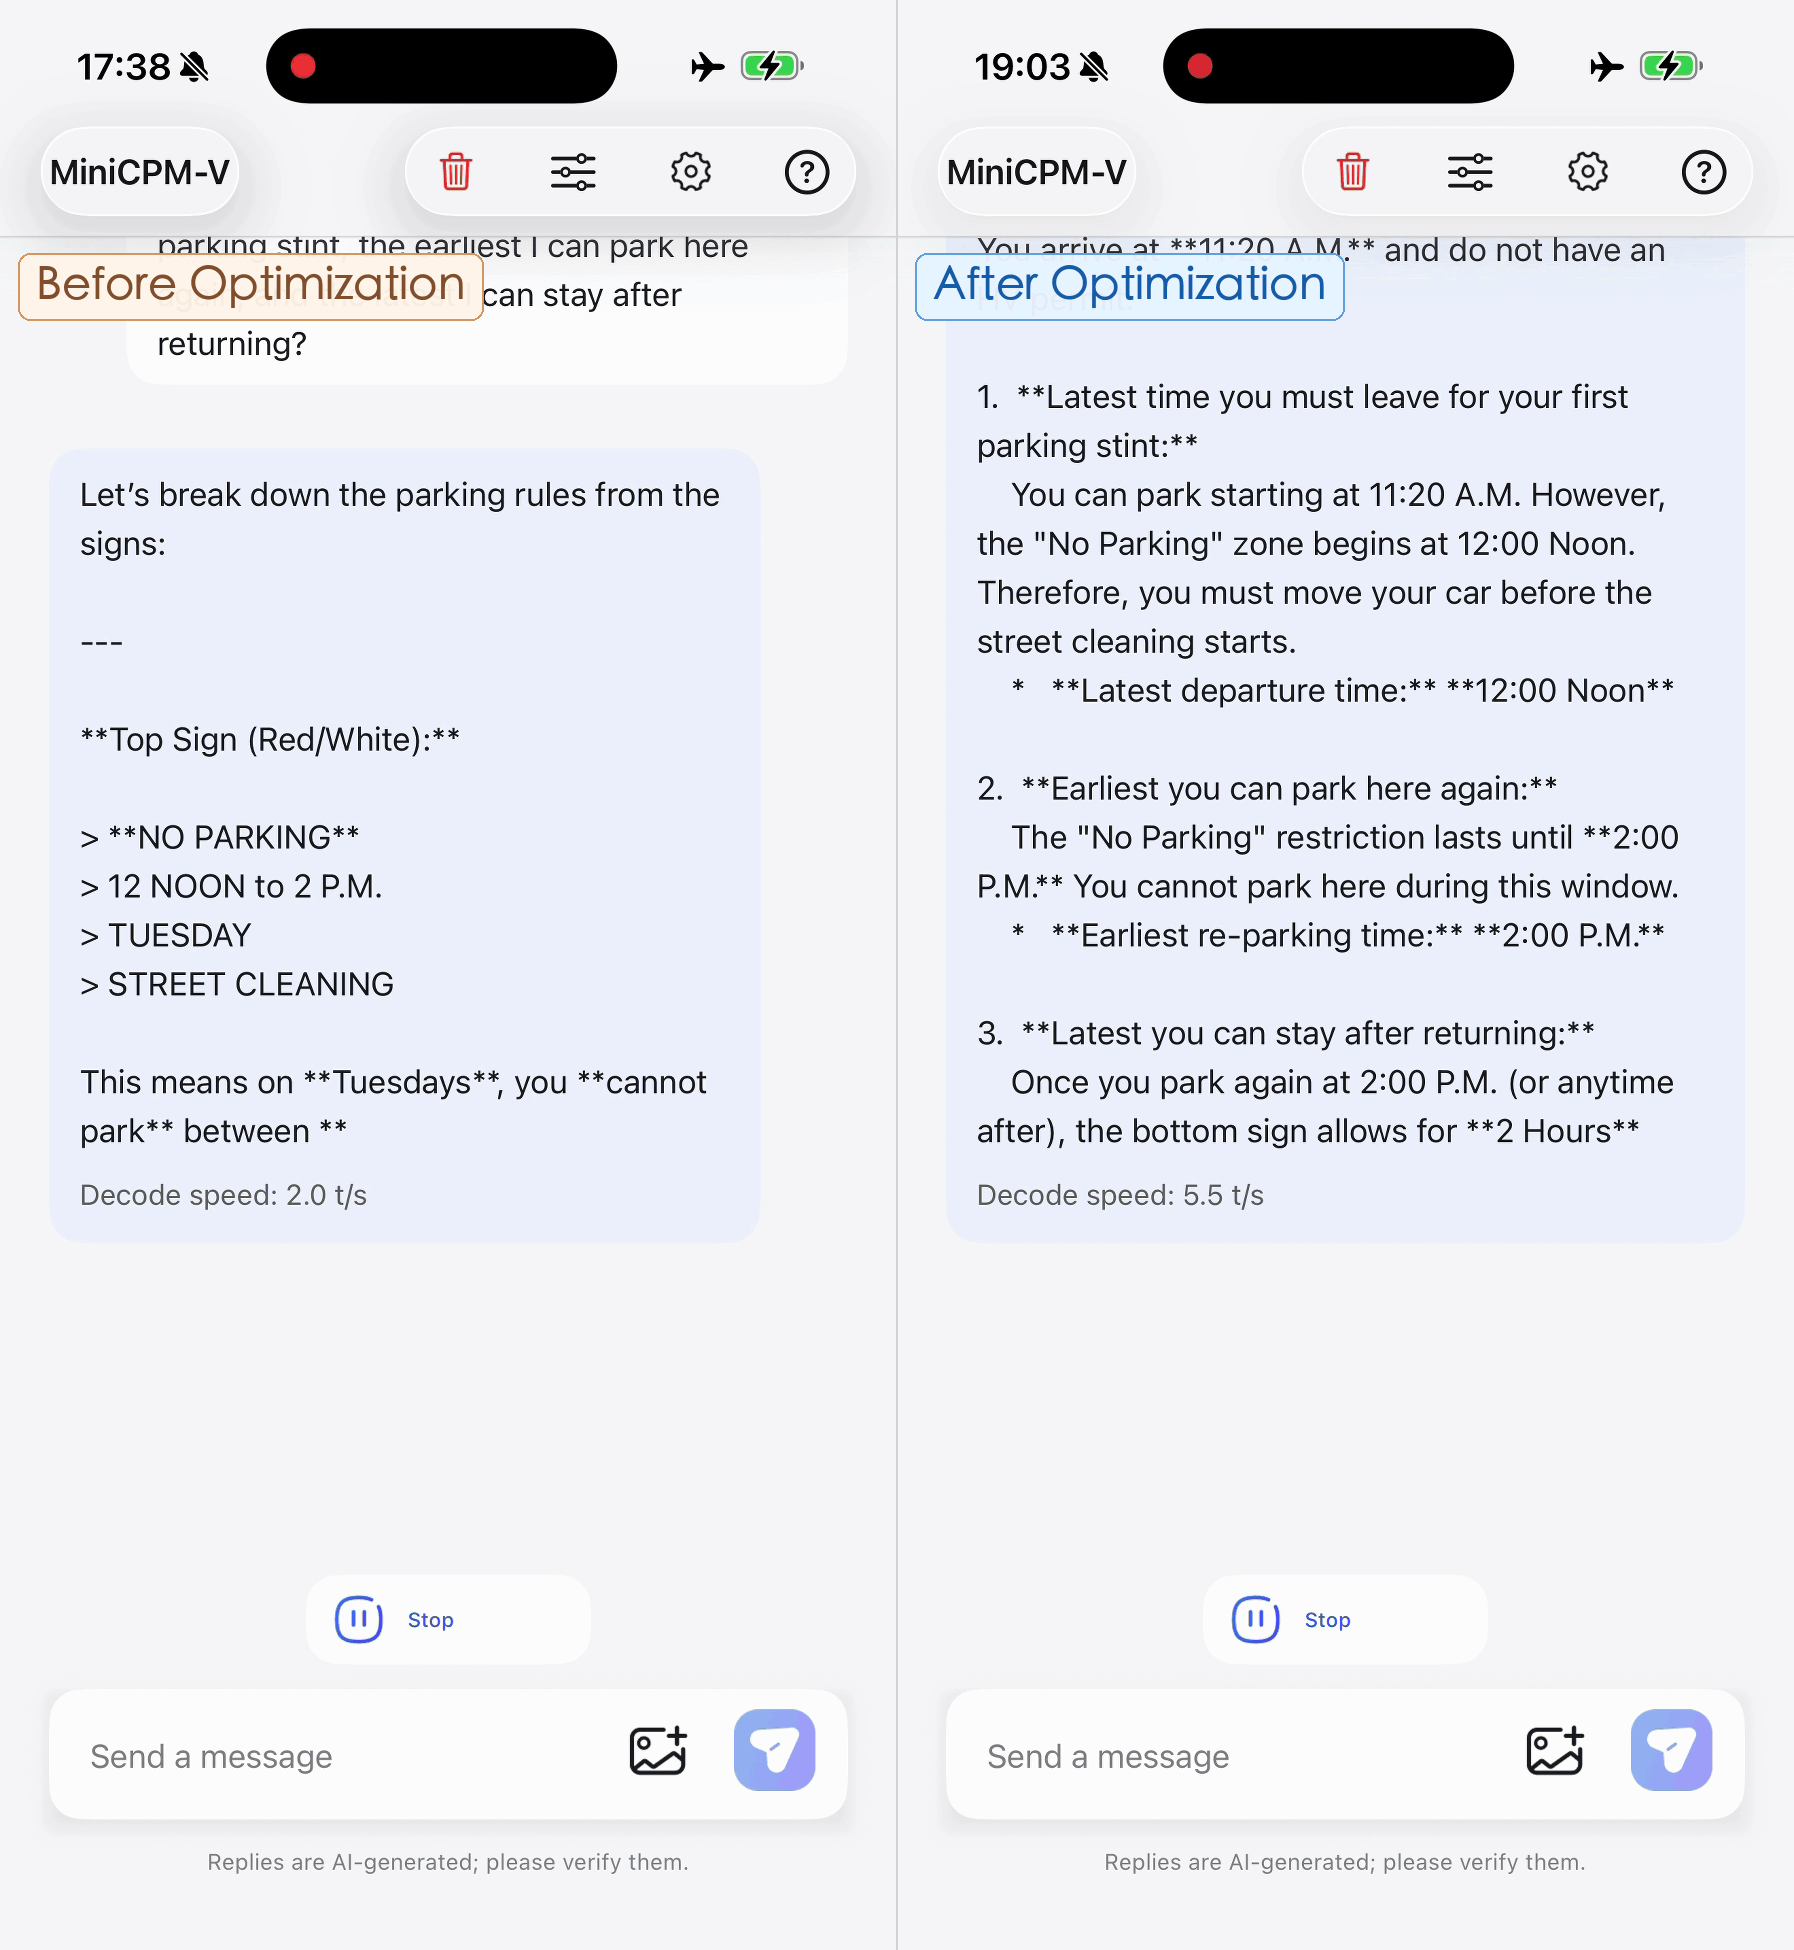
Running an MoE model on a device is only the starting point. The real challenge is to preserve model capability while delivering smooth generation. Storing expert weights on SSD can overcome memory capacity limits, but frequent loading stalls slow generation unless loading and computation overlap effectively. Restricting the number of experts or fixing an expert subset can speed up inference at the cost of model capability.
To address this trade-off, MiniCPM-V 4.7 introduces Lookahead Expert Scheduling, delivering a 5× speedup on real devices without sacrificing model capability. Cross-layer routing prediction preloads experts likely to be needed by the next layer and prioritizes computation for experts selected by the actual router that are already loaded, substantially reducing loading stalls. Weight quantization and an optimized storage layout also reduce the storage footprint and make scattered reads more efficient, further accelerating loading. The recording below compares generation speed before and after inference optimization:
Model Weights
MiniCPM-V 4.7 is available in 35B-A3B and 1B variants. Each row lists the model weights alongside its corresponding DSpark speculative decoding heads, available in BF16 and GGUF.
| Model | Description | Model weights | DSpark heads |
|---|---|---|---|
| MiniCPM‑V 4.7 35B-A3B | The first open-source MoE model to run smoothly on-device without compromising performance, raising the bar for on-device performance. | 🤗  BF16 🤗 FP8🤗 int4🤗 AWQ🤗 GPTQ🤗 GGUF | 🤗 BF16 🤗 GGUF |
| MiniCPM‑V 4.7 1B | Combines stronger capabilities with extremely high efficiency, advancing the performance–efficiency Pareto frontier for multimodal large language models. | 🤗 BF16 🤗 int4🤗 AWQ🤗 GPTQ🤗 GGUF | 🤗 BF16 🤗 GGUF |
The 1B int4 variant uses bitsandbytes; AWQ and GPTQ use W4A16 quantization. Quantized variants reduce memory usage; GGUF weights support CPU inference.
Also available on Ollama.
MiniCPM-o 4.5
MiniCPM-o 4.5 is the latest model in the MiniCPM-o series, a 9B end-to-end omnimodal model. It can continuously receive video and audio while generating speech and text, enabling real-time interactions that see, hear, and speak simultaneously.
Model highlights:
- 🔥 Vision capability approaching Gemini 2.5 Flash. It scores 77.6 on average across 8 popular OpenCompass benchmarks. With only 9B parameters, its visual understanding surpasses GPT-4o and Gemini 2.0 Pro, and a single model supports both instruct and thinking modes.
- 🎙 Strong speech capability. It supports bilingual real-time speech conversation with configurable voices in English and Chinese, making conversations more natural, expressive, and stable. A simple reference audio clip is enough for voice cloning and role play, and its voice cloning performance surpasses strong TTS tools such as CosyVoice2.
- 🎬 Full-duplex, proactive live interaction. It process real-time, continuous video and audio input streams simultaneously while generating concurrent text and speech output streams in an end-to-end fashion, without mutual blocking. This allows MiniCPM-o 4.5 to see, hear, and speak simultaneously, enabling smooth, real-time omnimodal conversations. Beyond responding to requests, the model can also interact proactively, for example by initiating reminders or comments based on its continuous understanding of the scene.
News
- 2026-05-17 · Released API access for MiniCPM-o 4.5.

Model overview
| MiniCPM-V 4.7 | MiniCPM-o 4.5 | |
|---|---|---|
| Models | 35B-A3B MoE · 1B | 9B end-to-end omnimodal model |
| Core capabilities | Image, multi-image, document and video understanding | Visual understanding, speech understanding and generation |
| Technical features | Mixed 4×/16× visual token compression; smooth on-device inference without compromising performance | Full-duplex multimodal live streaming, receiving audio and video while generating speech and text |
| Model guides | MiniCPM-V 4.7 model guide | MiniCPM-o 4.5 model guide |
| Examples | Examples | Examples |
| Evaluation | Evaluation | Evaluation |
Get started
| MiniCPM-V 4.7 | MiniCPM-o 4.5 |
|---|---|
| Model weights | Model weights |
| HF · vLLM · SGLang · Ollama · llama.cpp | HF · vLLM · SGLang · Ollama · llama.cpp |
| Fine-tuning | Fine-tuning |
| Live demo | Live demo |
| Local deployment | Local deployment |
| API | |
| Cookbook | |
Earlier updates
- 2026-06-25 · MiniCPM-V 4.6 joined the official Ollama model library.
- 2026-05-17 · Released API access for MiniCPM-V 4.6.
- 2026-05-11 · Released MiniCPM-V 4.6, with mixed 4×/16× visual token compression and mobile deployment support.
Community milestones
- 2025-01-19 · MiniCPM-o reached No. 1 on GitHub Trending and No. 2 on Hugging Face Trending.
- 2024-05-23 · MiniCPM-V reached No. 1 on both GitHub Trending and Hugging Face Trending.
Built with MiniCPM
| Project | What you can explore |
|---|---|
| OpenAvatarChat | Interactive digital-human conversations on a single PC |
| Ollama-OCR | Extract text from images and PDFs with local vision-language models |
| comfyui_LLM_party | Connect language and vision models to ComfyUI workflows |
Community projects may support different model generations. Check each project's model list. More community projects
Project resources
| Category | Links |
|---|---|
| Model documentation | MiniCPM-V 4.7 · MiniCPM-o 4.5 |
| Deployment & development | Deployment & training · Cookbook · Documentation site |
| Papers | Technical reports & related papers |
| Versions & updates | Earlier models · Full release history |
| Community | Discord · WeChat · Feishu / Lark · MiniCPM Wiki |
| License & usage | Apache-2.0 · Model license · Usage statement |

Developed by THUNLP and ModelBest. Code and model weights are released under Apache-2.0.
Citation
If you find our model/code/paper helpful, please consider citing our papers 📝 and staring us ⭐️!
@misc{cui2026minicpmo45realtimefullduplex,
      title={MiniCPM-o 4.5: Towards Real-Time Full-Duplex Omni-Modal Interaction},
      author={Junbo Cui and Bokai Xu and Chongyi Wang and Tianyu Yu and Weiyue Sun and Yingjing Xu and Tianran Wang and Zhihui He and Wenshuo Ma and Tianchi Cai and others},
      year={2026},
      url={https://arxiv.org/abs/2604.27393},
}

@proceedings{yu2025minicpmv45cookingefficient,
      title={MiniCPM-V 4.5: Cooking Efficient MLLMs via Architecture, Data, and Training Recipe},
      author={Tianyu Yu and Zefan Wang and Chongyi Wang and Fuwei Huang and Wenshuo Ma and Zhihui He and Tianchi Cai and Weize Chen and Yuxiang Huang and Yuanqian Zhao and others},
      year={2025},
      url={https://arxiv.org/abs/2509.18154},
}

@article{yao2024minicpm,
  title={MiniCPM-V: A GPT-4V Level MLLM on Your Phone},
  author={Yao, Yuan and Yu, Tianyu and Zhang, Ao and Wang, Chongyi and Cui, Junbo and Zhu, Hongji and Cai, Tianchi and Li, Haoyu and Zhao, Weilin and He, Zhihui and others},
  journal={arXiv preprint arXiv:2408.01800},
  year={2024}
}