✨ TDMM-LM: Bridging Facial Understanding and Animation via Language Models
🌐 Homepage | 🔬 Paper | 👩💻 Code
TDMM-LM Dataset
TDMM-LM Dataset is a large-scale facial animation dataset synthesized with foundation generative models, comprising roughly 80 hours of face-centric video that spans a wide spectrum of emotions, expressions, and head motions, with each clip paired with its text prompt and 3D facial parameters for training text-driven facial animation/understanding models.
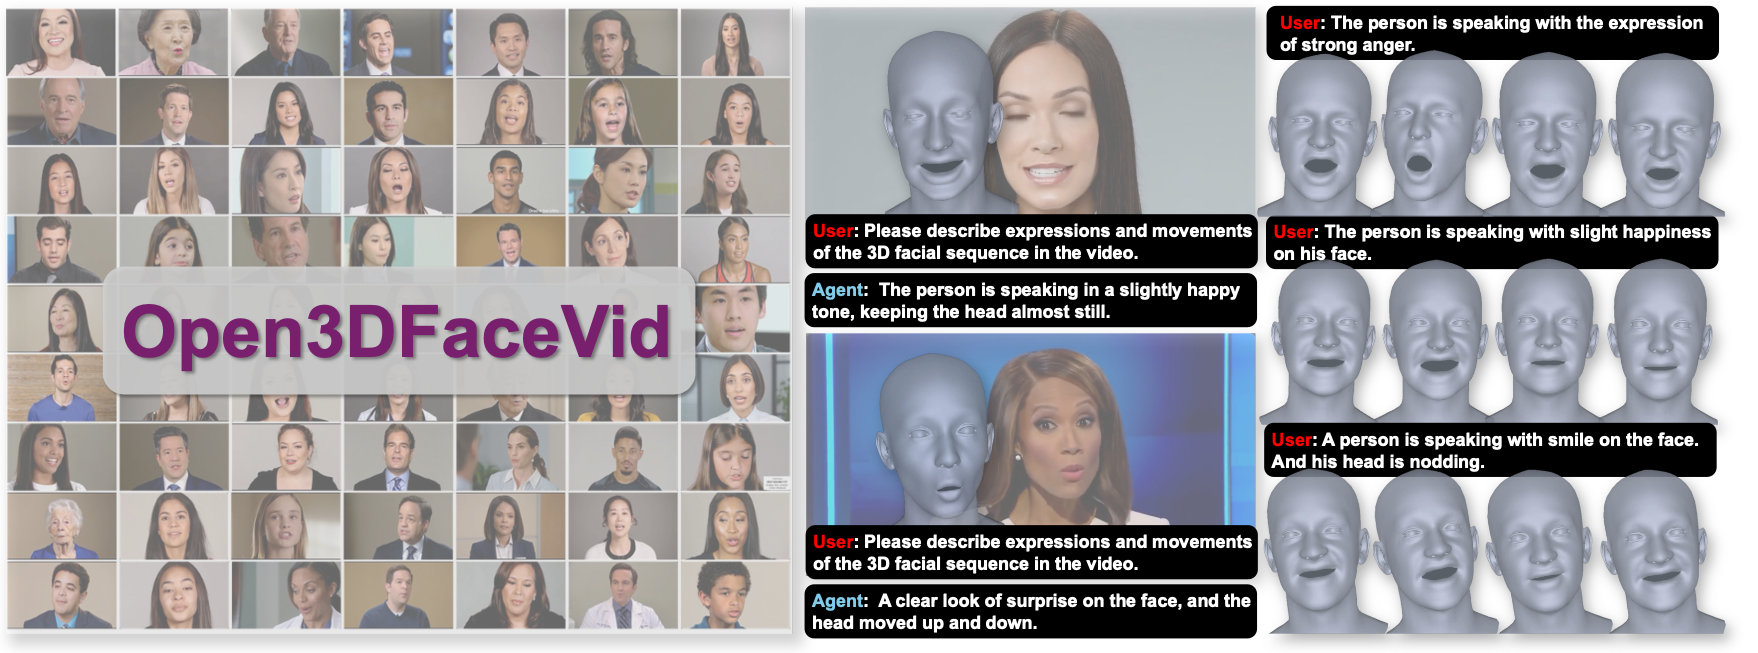
Our dataset enables researchers and practitioners to uncover the strengths, limitations, and potential areas for improvement in text-driven facial animation/understaning models, offering valuable insights into the challenges of generating expressive and emotionally faithful facial behavior.
📊 Video Dataset/Annotation [Part-1, ~70hr]
• Videos Download: Google drive (./download_gdrive_folder.sh)
• Language Annotation: As shown in json file.
📊 Video Dataset/Annotation [Part-2, ~10hr]
• Coming Soon.
🎵 Audios
• Coming Soon [Synchronized with videos in Part-1].
🔧 Tools
• We recommend using smirk or other facial tracking methods to extract the parameters.
• We provide a batch processing script by smirk as a reference.
• We provide a batch processing script by spectre as a reference.
✏️ Citation
@article{song2026tdmm,
  title={TDMM-LM: Bridging Facial Understanding and Animation via Language Models},
  author={Song, Luchuan and Liu, Pinxin and Liu, Haiyang and Jin, Zhenchao and Tang, Yolo Yunlong and Xu, Zichong and Liang, Susan and Bi, Jing and Corso, Jason J and Xu, Chenliang},
  journal={arXiv preprint arXiv:2603.16936},
  year={2026}
}