


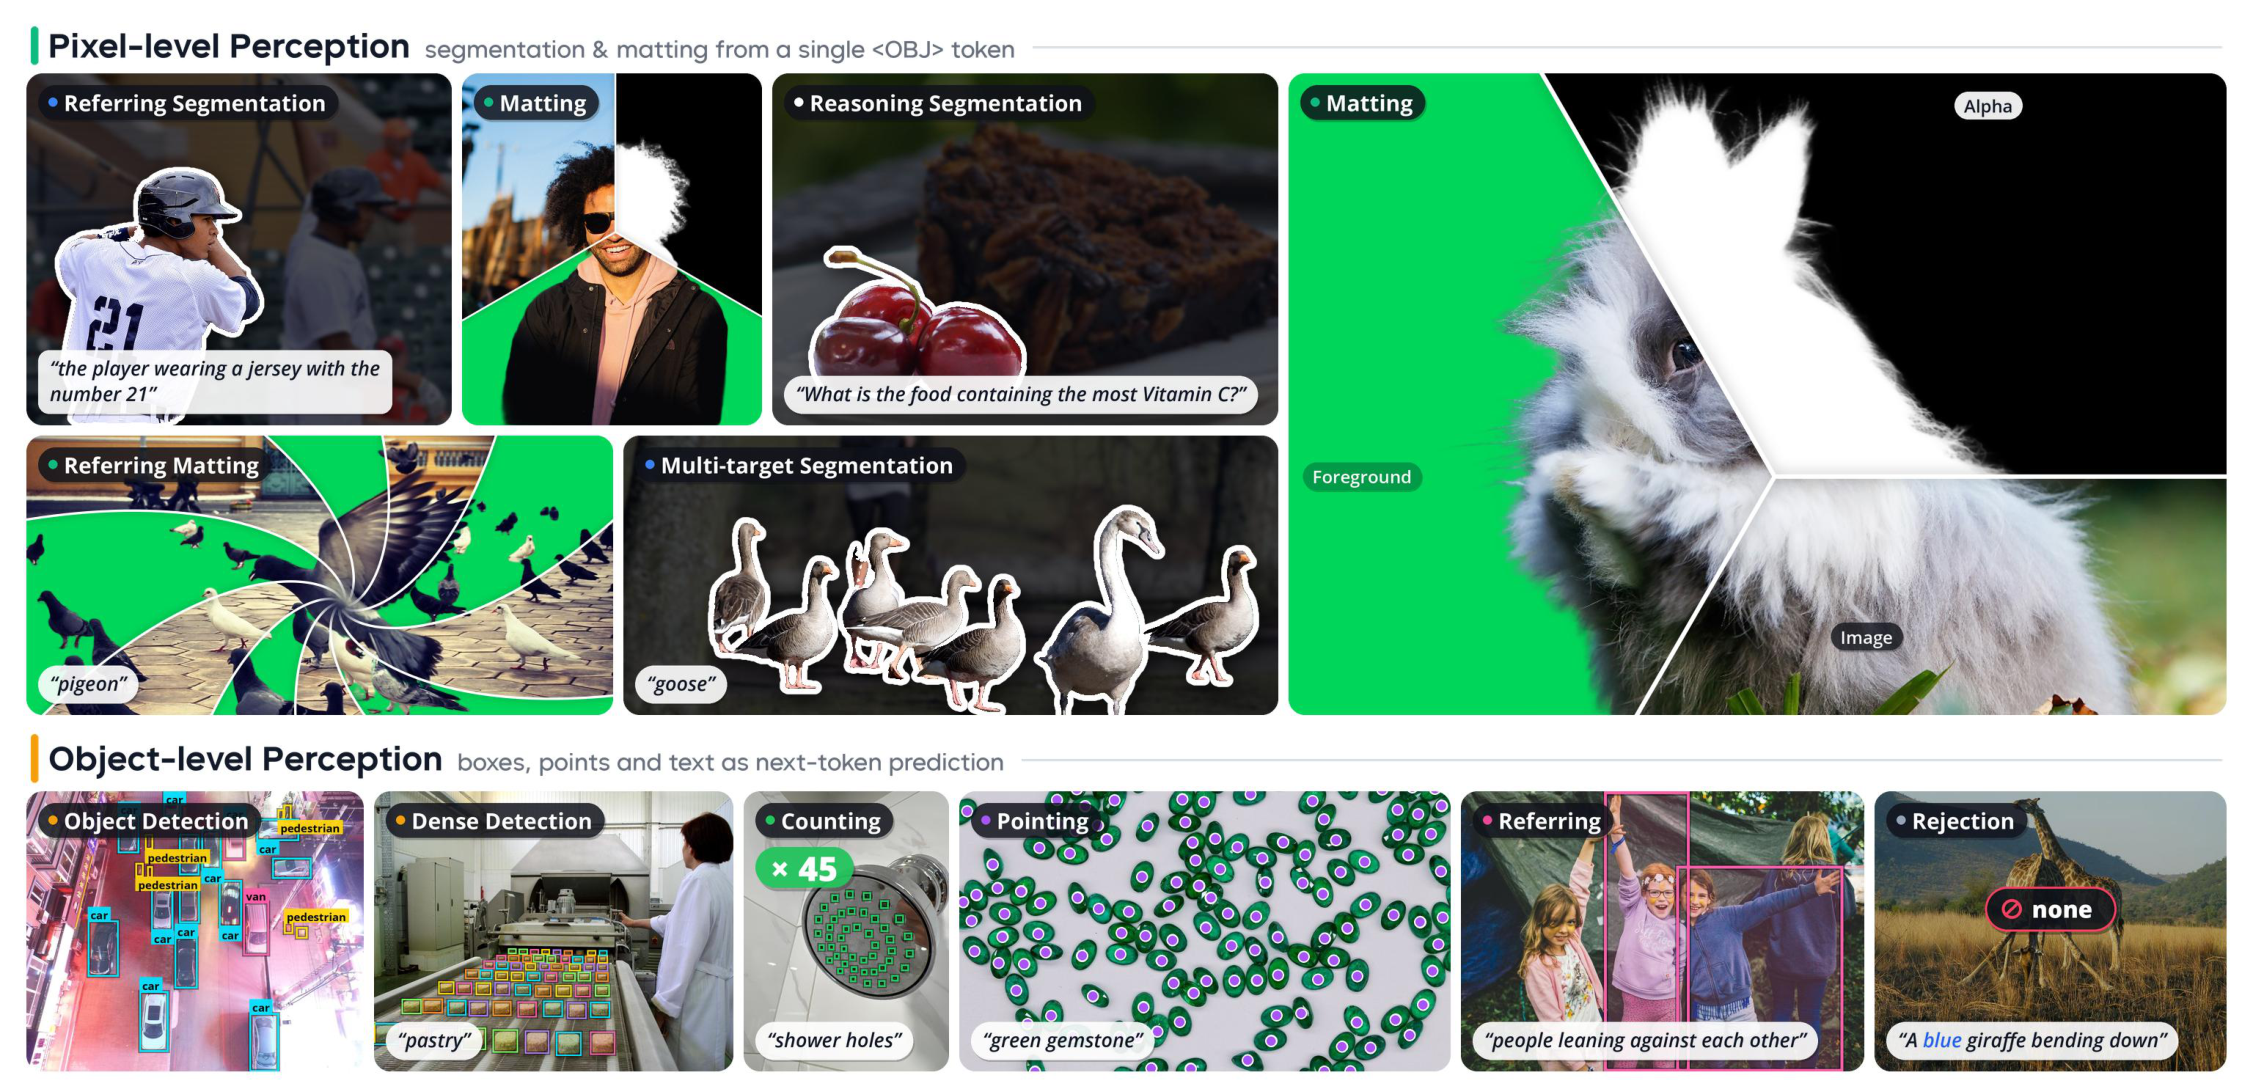
WeVisOne-VL (WeChat Vision All-in-One) is a vision-language foundation model that unifies object-level perception (object detection, referring localization, counting, pointing, and OCR) and pixel-level perception (referring segmentation and promptable alpha matting) through structured next-token prediction and a lightweight 9.6M-parameter pixel decoder—enabling localization at any user-specified granularity from points and boxes to binary masks and continuous alpha mattes, while reliably rejecting absent-target queries.
✨ Highlights
- 🎯 All-in-One: detection, referring, counting, pointing, OCR, segmentation and matting in a single model.
- 🪶 Lightweight Pixel Decoder: a 9.6M-parameter decoder outputs masks and alpha mattes, with no SAM required.
- 🚫 Reliable Rejection: returns
Nonefor absent targets instead of hallucinating.
📢 News
- [2026-10] 🎮 The demo is ready to try: 2B / 4B.
- [2026-10] 🔥🔥 We also open-sourced Mask2Alpha, the matting annotator used in the WeVisOne-VL Data Engine to turn binary masks into high-quality alpha mattes! Check out the
mask2alphabranch. - [2026-10] 🎉 We release the technical report, model weights (2B & 4B), inference package, Cookbooks, and evaluation pipeline!
📝 TODO
- Inference package and Cookbooks
- Gradio web demo
- Benchmark evaluation pipeline
- Model weights (2B & 4B) on Hugging Face
- Release our matting annotator
- Fine-tuning code
🏆 Performance at a Glance
Headline numbers for WeVisOne-VL-4B against the strongest open baseline in each benchmark (Qwen3-VL / Qwen3.5 up to 9B, Rex-Omni, LocateAnything, and task-specific segmentation / matting models).
| Task | Benchmark | Metric | Best Baseline | WeVisOne-VL-4B |
|---|---|---|---|---|
| 📦 Detection | LVIS | F1 Mean ↑ | 50.7 | 55.3 |
| 📦 Dense Detection | Dense200 | F1 Mean ↑ | 58.7 | 71.3 |
| 💬 Referring | RefCOCOg test | F1 Mean ↑ | 77.6 | 81.8 |
| 🚫 Rejection | WeRef-Bench | Rej. Rate ↑ | 73.0 | 96.4 |
| 🔢 Counting | PixMo-Count test | Acc ↑ | 82.8 | 89.6 |
| 📍 Pointing | PointBench | Acc ↑ | 69.9 | 71.9 |
| 🔤 OCR | TotalText | F1 Mean ↑ | 43.3 | 52.0 |
| 🎭 Referring Seg. | ReasonSeg val | gIoU ↑ | 65.0 | 71.2 |
| ✂️ Box Matting | P3M-500-NP | MAD ↓ | 15.4 | 7.3 |
| ✂️ Text Matting | WeRefMat (Referring) | MAD ↓ | 22.4 | 9.8 |
📊 Full Benchmark Results (click each task to expand)
F1 for detection, referring and OCR is averaged over IoU thresholds 0.5:0.95 ("Mean"). Greedy decoding, ≤ 1,960 visual tokens per image.
Object Detection (F1 Mean)
| Method | COCO | LVIS | Dense200 | VisDrone |
|---|---|---|---|---|
| GroundingDINO-T | 56.6 | 38.8 | 33.1 | 38.5 |
| Qwen3-VL-8B | 47.8 | 42.9 | 13.8 | 29.5 |
| Qwen3.5-9B | 49.5 | 43.7 | 18.0 | 31.3 |
| Rex-Omni-3B | 52.9 | 46.9 | 58.3 | 35.8 |
| LocateAnything-3B | 54.7 | 50.7 | 58.7 | 39.9 |
| WeVisOne-VL-2B | 55.2 | 53.3 | 61.4 | 40.4 |
| WeVisOne-VL-4B | 57.1 | 55.3 | 71.3 | 44.7 |
Referring Object Detection (F1 Mean / Rejection Rate %)
| Method | RefCOCOg test | RefCOCOg Rej | WeRef Mean | WeRef Rej | HumanRef | Ref-L4 |
|---|---|---|---|---|---|---|
| Qwen3-VL-8B | 74.9 | 22.5 | 36.7 | 18.3 | 71.6 | 72.4 |
| Qwen3.5-9B | 74.6 | 15.2 | 50.7 | 70.7 | 77.8 | 72.0 |
| Rex-Omni-3B | 74.3 | 0.5 | 50.3 | 43.3 | 79.9 | 65.2 |
| LocateAnything-3B | 77.6 | 0.6 | 51.7 | 73.0 | 78.7 | 74.3 |
| WeVisOne-VL-2B | 78.2 | 50.2 | 73.2 | 92.9 | 77.4 | 75.1 |
| WeVisOne-VL-4B | 81.8 | 67.4 | 78.7 | 96.4 | 80.7 | 78.1 |
Object Counting (Exact-match Accuracy %)
| Method | CountQA | PixMo-Count test | CLOC test | KubriCount testB | MixCount test |
|---|---|---|---|---|---|
| Qwen3.5-9B | 41.6 | 80.4 | 22.4 | 19.1 | 7.0 |
| Rex-Omni-3B | 37.6 | 71.9 | 22.3 | 18.8 | 11.4 |
| LocateAnything-3B | 52.4 | 82.8 | 23.9 | 22.4 | 15.2 |
| WeVisOne-VL-2B | 47.9 | 88.1 | 26.9 | 32.4 | 32.2 |
| WeVisOne-VL-4B | 57.1 | 89.6 | 28.3 | 40.1 | 40.4 |
Object Pointing
| Method | PointBench | PixMo-Points | COCO | LVIS | Dense200 | VisDrone |
|---|---|---|---|---|---|---|
| Qwen3-VL-8B | 62.5 | 72.2 | 77.5 | 67.7 | 42.2 | 46.4 |
| Rex-Omni-3B | 69.9 | 72.9 | 80.5 | 70.8 | 82.5 | 58.9 |
| LocateAnything-3B | 56.9 | 68.6 | 83.9 | 76.6 | 87.6 | 60.4 |
| WeVisOne-VL-2B | 62.9 | 73.2 | 85.8 | 78.9 | 83.2 | 62.4 |
| WeVisOne-VL-4B | 71.9 | 74.7 | 85.4 | 79.5 | 87.0 | 64.4 |
OCR — Text Grounding & Recognition (F1 Mean)
| Method | HierText | ICDAR2015 | TotalText | SROIE |
|---|---|---|---|---|
| PP-OCRv5 (specialist) | 30.5 | 25.6 | 25.7 | 58.6 |
| Qwen3-VL-8B | 25.7 | 27.1 | 35.4 | 43.3 |
| Rex-Omni-3B | 28.0 | 28.1 | 40.6 | 44.8 |
| LocateAnything-3B | 29.4 | 24.1 | 43.3 | 40.3 |
| WeVisOne-VL-2B | 30.5 | 42.6 | 42.5 | 62.1 |
| WeVisOne-VL-4B | 39.0 | 47.8 | 52.0 | 68.1 |
Referring Segmentation (cIoU; ReasonSeg uses gIoU)
| Method | RefCOCO testA | RefCOCO+ testA | RefCOCOg test | ReasonSeg val | Ref-ZOM cIoU | Ref-ZOM Rej |
|---|---|---|---|---|---|---|
| LISA-13B (ft) | 78.8 | 70.2 | 70.5 | 65.0 | - | - |
| GSVA-7B | 78.9 | 69.6 | 73.3 | 50.5 | 66.6 | 41.9 |
| UniPixel-7B | 83.0 | 80.1 | 77.1 | 60.5 | 62.9 | 0.3 |
| Youtu-VL-4B | 82.0 | 79.6 | 76.6 | - | 61.0 | 1.3 |
| WeVisOne-VL-2B | 82.9 | 79.0 | 74.9 | 60.9 | 73.4 | 62.4 |
| WeVisOne-VL-4B | 84.5 | 81.1 | 77.8 | 71.2 | 72.2 | 86.0 |
Promptable Matting (MAD ×10³ ↓)
| Method | P3M-500-NP (Box) | AM-2K (Box) | PPM-100 (Box) | WeRefMat (Category) | WeRefMat (Referring) |
|---|---|---|---|---|---|
| Matte Anything | 24.4 | 13.2 | 10.5 | - | - |
| SAM2-Matting (SAM3) | 15.4 | 12.1 | 10.8 | 70.8 | 51.9 |
| Qwen3.5-9B + SAM2-Matting | - | - | - | 77.8 | 22.4 |
| WeVisOne-VL-2B | 6.6 | 5.7 | 5.3 | 17.7 | 15.8 |
| WeVisOne-VL-4B | 7.3 | 5.0 | 6.1 | 16.4 | 9.8 |
See the technical report for all splits and metrics, and evaluation/README.md to reproduce the public benchmarks.
🏗️ How It Works
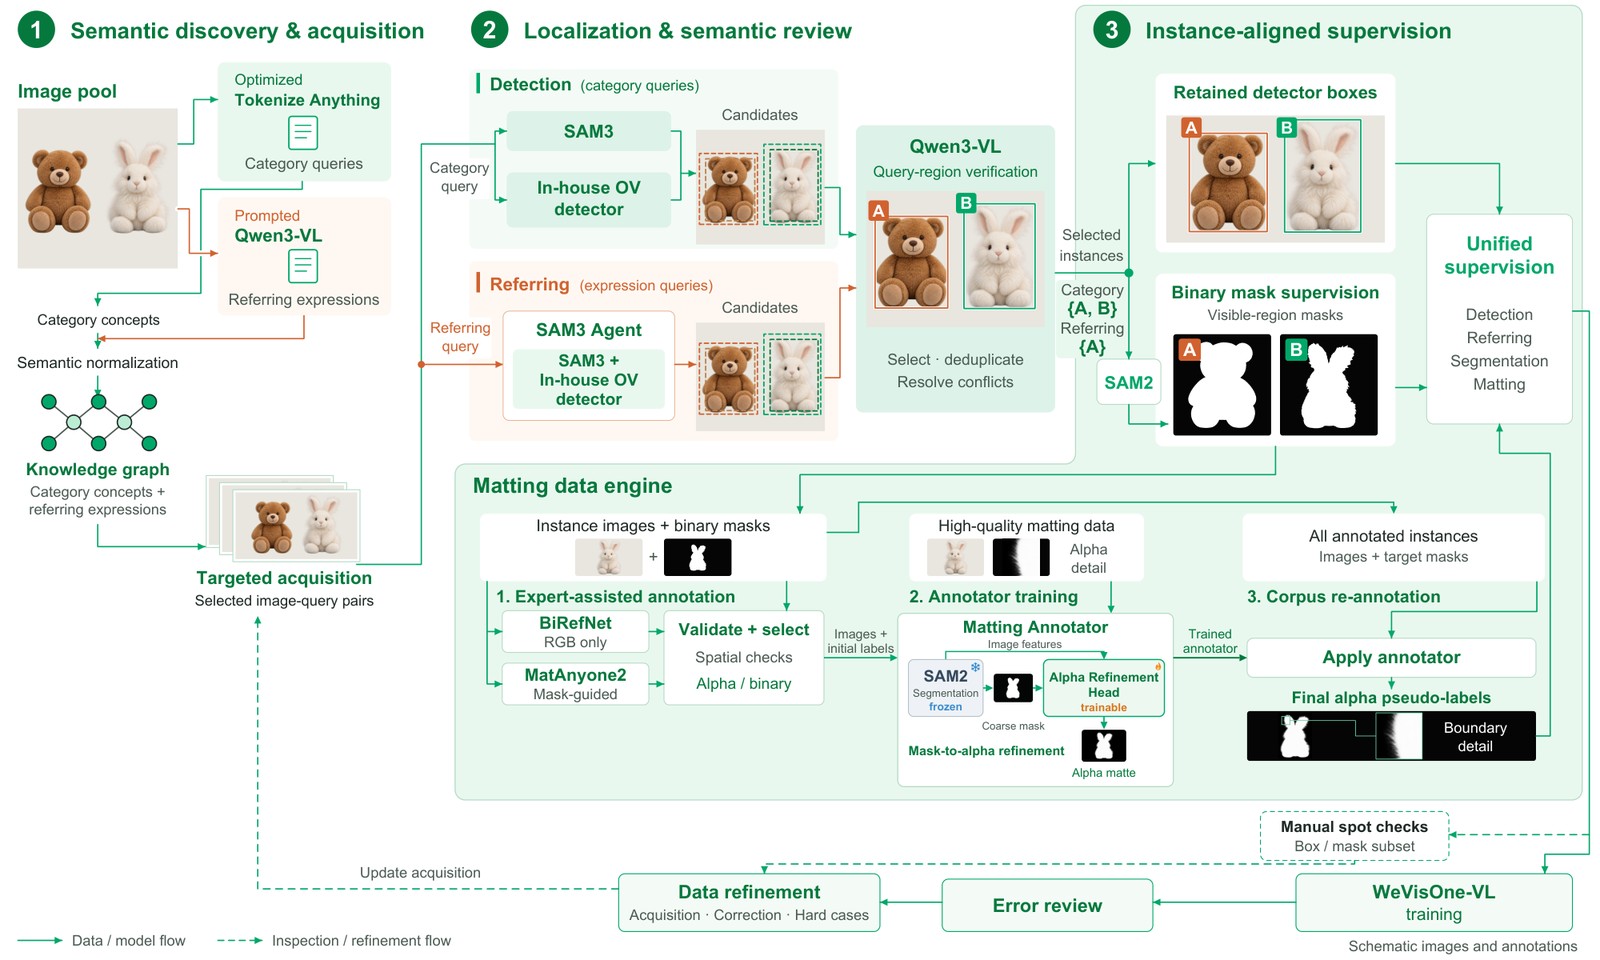
1. Data Engine. A knowledge-graph-driven engine discovers concepts, localizes them with complementary experts verified by a VLM, and extends the verified boxes to masks and alpha mattes. Over 100M images are annotated this way.
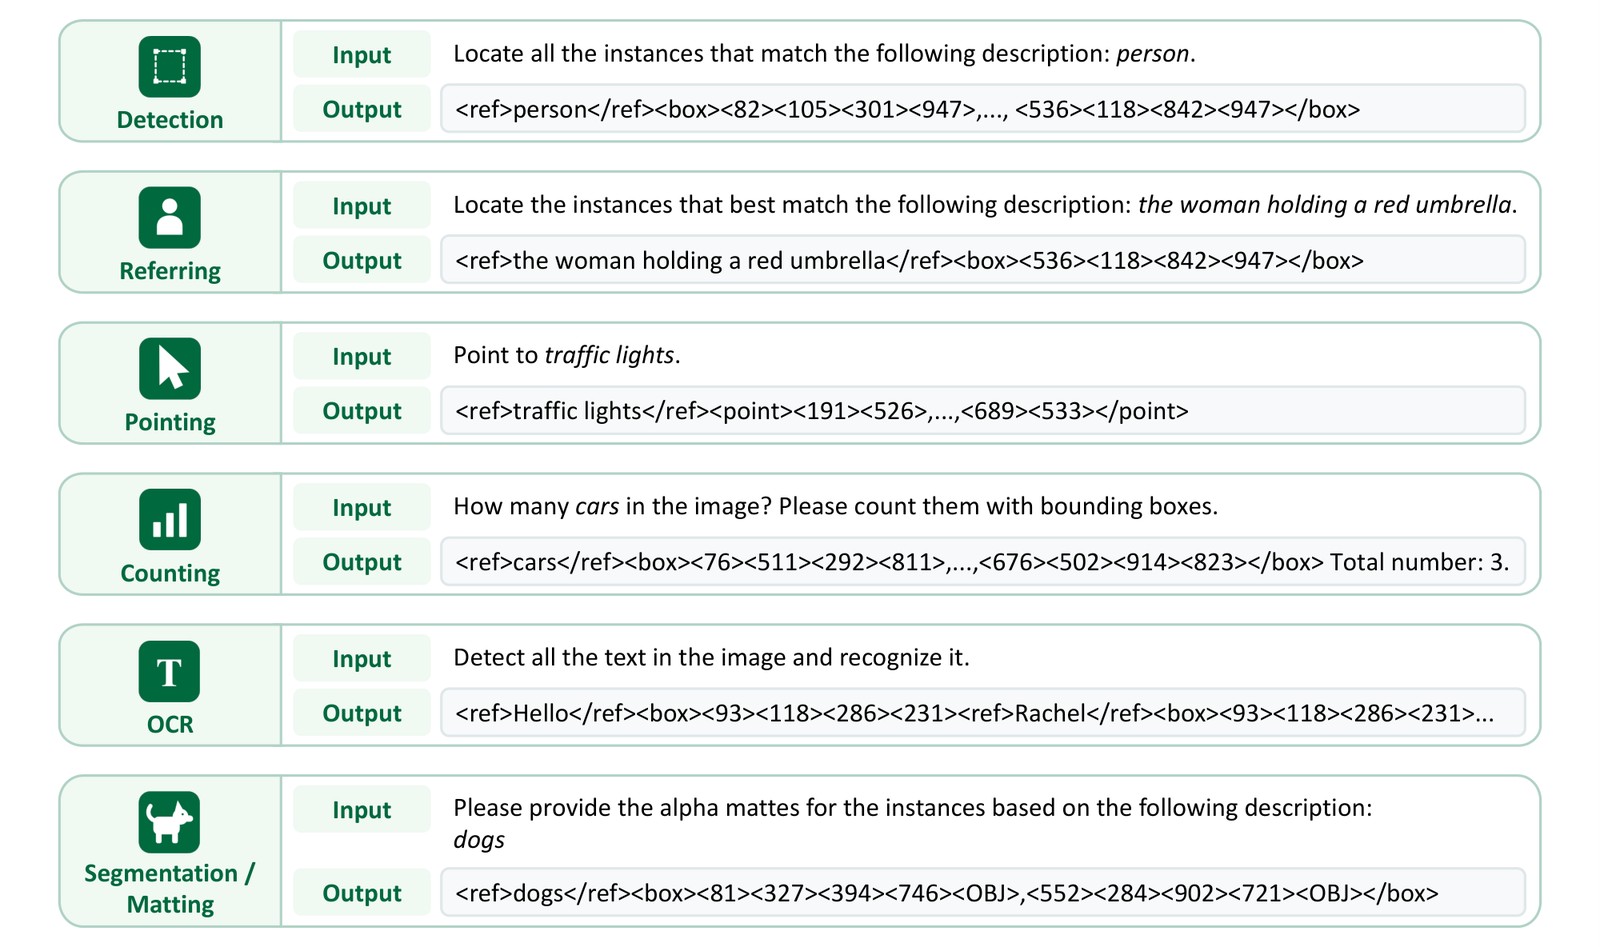
2. Unified Task Formulation. Every task is written as structured text, with coordinate tokens <0> … <1000> for boxes and points, None for absent targets, and an <OBJ> token after each box for pixel-level outputs.
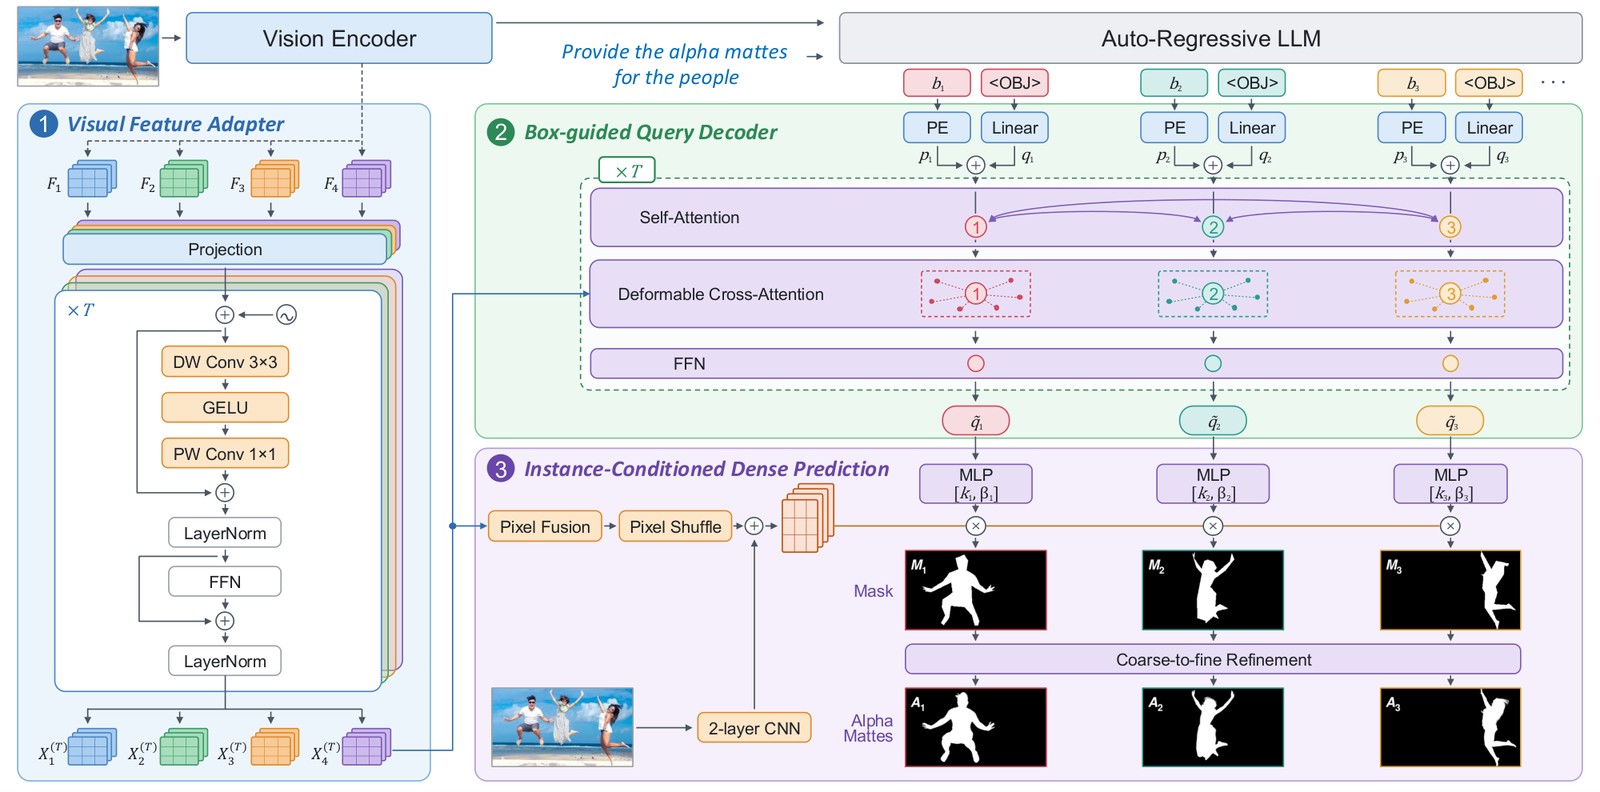
3. Model Architecture. A 9.6M-parameter pixel decoder combines the hidden state of each <OBJ> token, its predicted box and multi-level Qwen3-VL ViT features to predict a full-resolution mask or alpha matte.
🚀 Quick Start
Installation
git clone https://github.com/Tencent/WeVisOne-VL.git && cd WeVisOne-VL
conda create -n wevisone-vl python=3.10 -y && conda activate wevisone-vl
pip install -r requirements.txt && pip install -v -e .
Inference
from PIL import Image
from wevisone_vl import WeVisOneVL
from wevisone_vl.visualization import save_result
model = WeVisOneVL("tencent/WeVisOne-VL-4B", backend="transformers") # or backend="vllm"
# model = WeVisOneVL("tencent/WeVisOne-VL-2B", backend="transformers") # Use 2B instead
# Object-level: open-vocabulary detection
image = Image.open("demo/examples/images/livingroom.jpg").convert("RGB")
result = model.predict(image, task="detection", query=["sofa", "pillow", "coffee table", "lamp"])
save_result("outputs/detection", image, result)
# Pixel-level: promptable alpha matting
image = Image.open("demo/examples/images/seabreeze.jpg").convert("RGB")
result = model.predict(image, task="matting", query="person")
save_result("outputs/matting", image, result)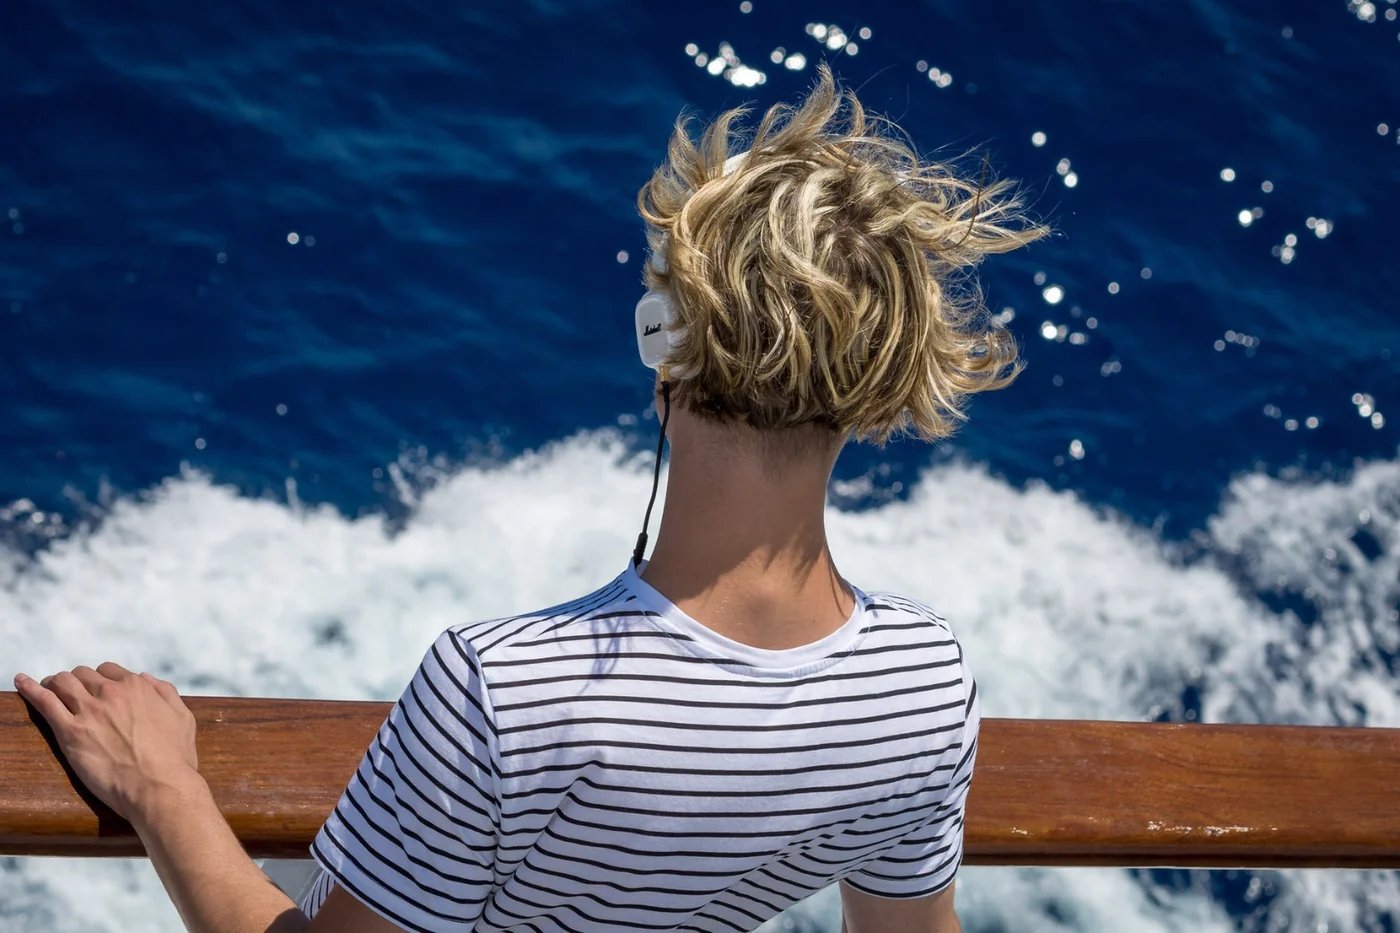 Input · query="person" | 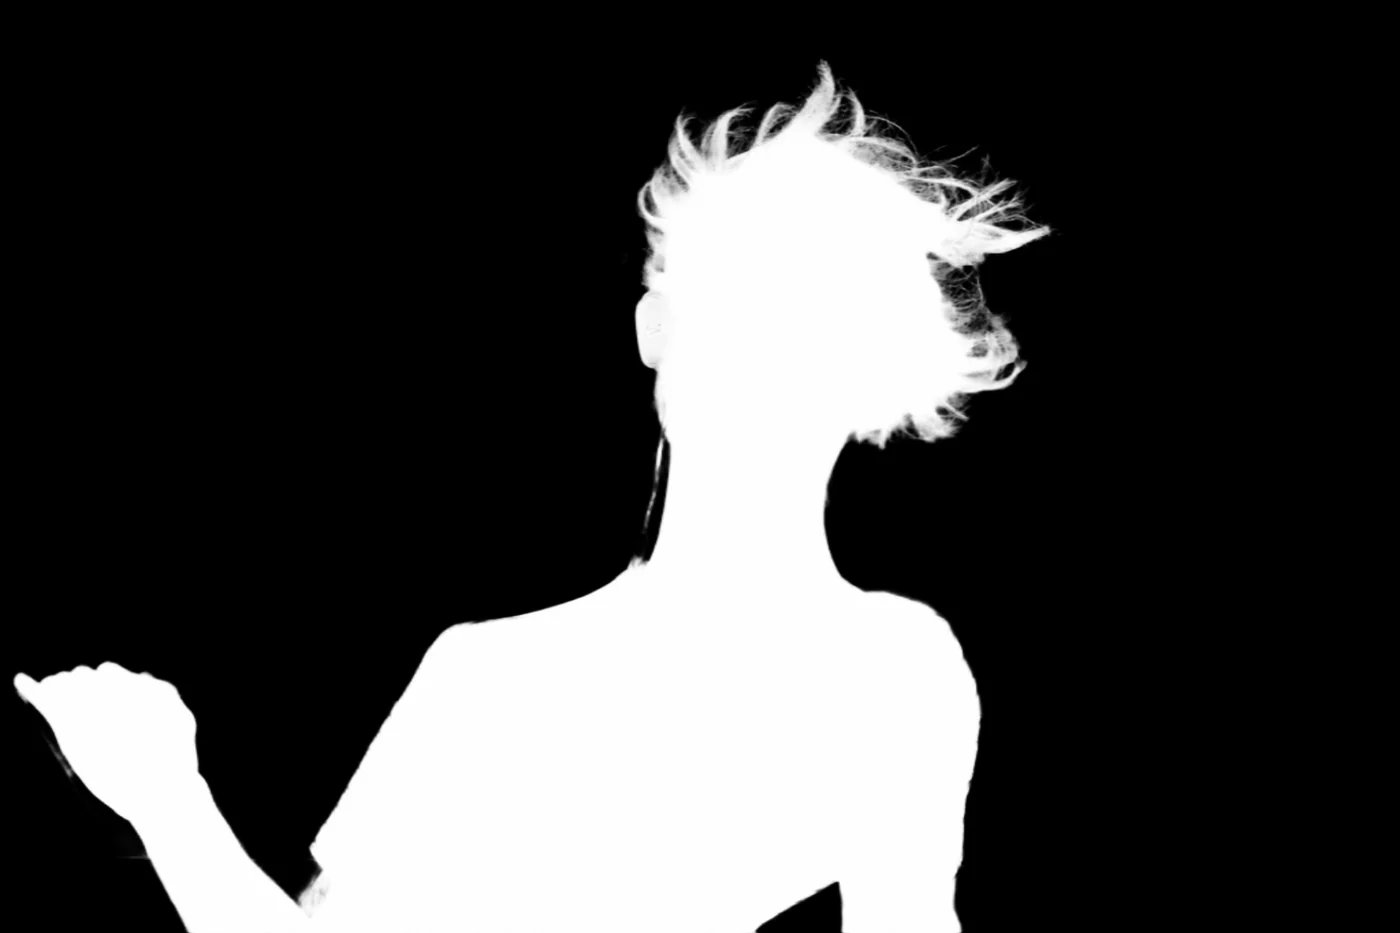 Predicted alpha matte | 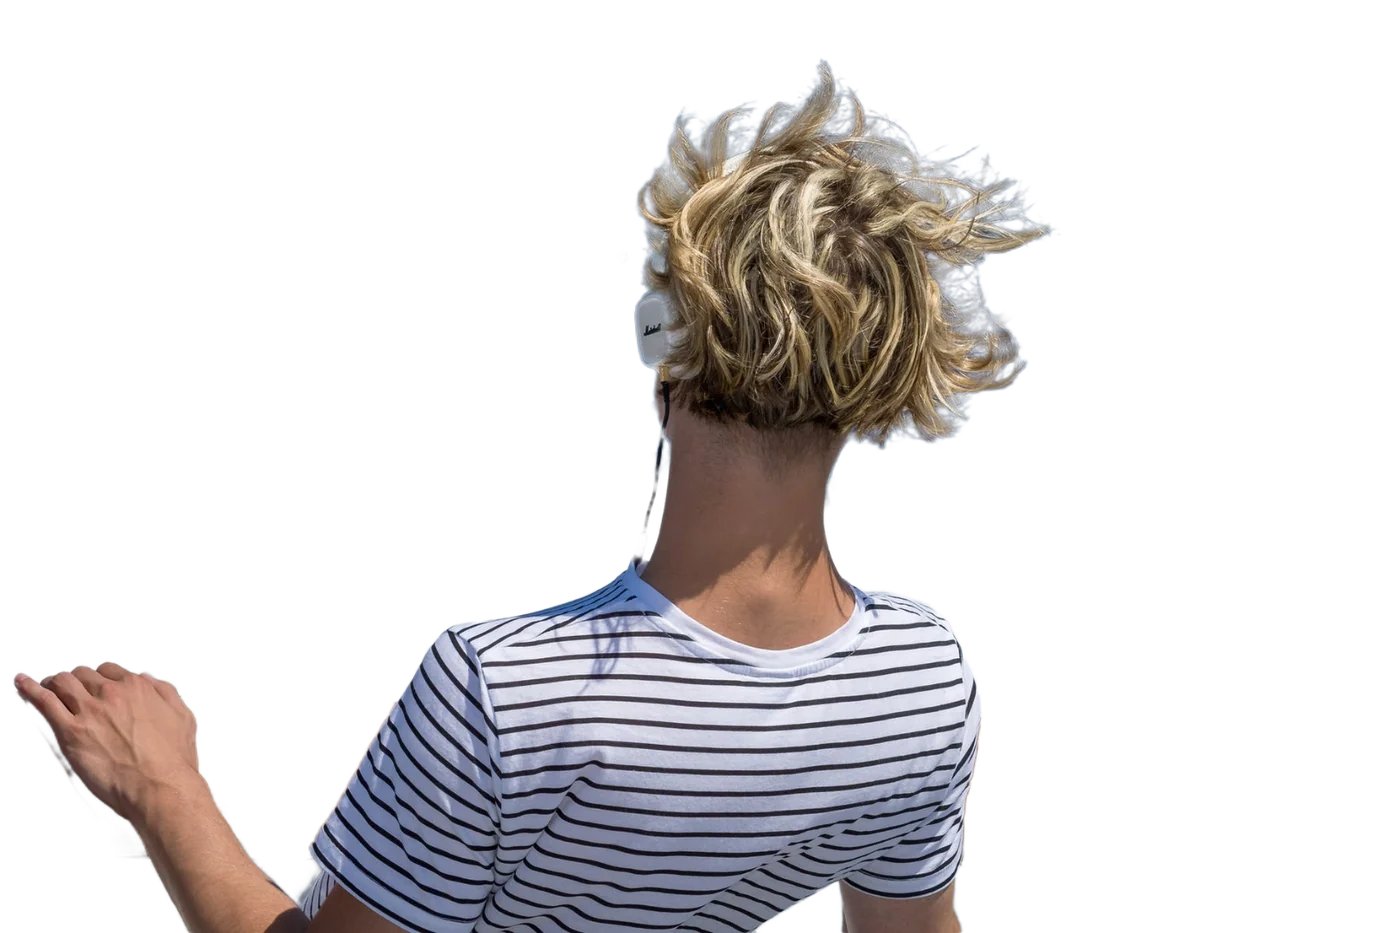 Cutout |
Supported Tasks
task | query | Output | |
|---|---|---|---|
| 📦 | detection | category list | boxes |
| 💬 | referring | referring expression | boxes or None |
| 📍 | point | category / expression | points |
| 🔢 | count_box / count_point | category / expression | boxes / points + count |
| 🔤 | ocr / ocr_grounding | – / text to find | text + boxes |
| 🎭 | segmentation | category / expression | boxes + binary masks |
| ✂️ | matting | category / expression | boxes + alpha mattes |
[!TIP]
device("auto","cuda:0","npu:0","cpu"),dtype,min_pixels/max_pixels, and the usual decoding arguments (max_new_tokens,temperature, ...) are also available. The Cookbooks walk through each task in detail.
📓 Cookbooks
| Tutorial | Covers |
|---|---|
| 📦 Object-level pipeline | Detection, Referring, Counting, Pointing |
| 🔤 OCR pipeline | OCR, Text Grounding |
| 🎭 Pixel-level pipeline | Segmentation, Matting |
🎮 Gradio Demo
Launch the demo locally:
CUDA_VISIBLE_DEVICES=0 python demo/app.py --model tencent/WeVisOne-VL-4B
# Or use 2B:
# CUDA_VISIBLE_DEVICES=0 python demo/app.py --model tencent/WeVisOne-VL-2B
More launch options
# vLLM backend on a custom port, with a public share link
CUDA_VISIBLE_DEVICES=0 python demo/app.py \
    --model tencent/WeVisOne-VL-4B --backend vllm \
    --server-name 0.0.0.0 --server-port 8080 --share
📊 Evaluation
See evaluation/README.md.
🖼️ Representative Visualizations
Side-by-side comparisons with strong baselines. Click a task to expand or collapse it.
Referring Detection — locating the objects described by a natural-language expression
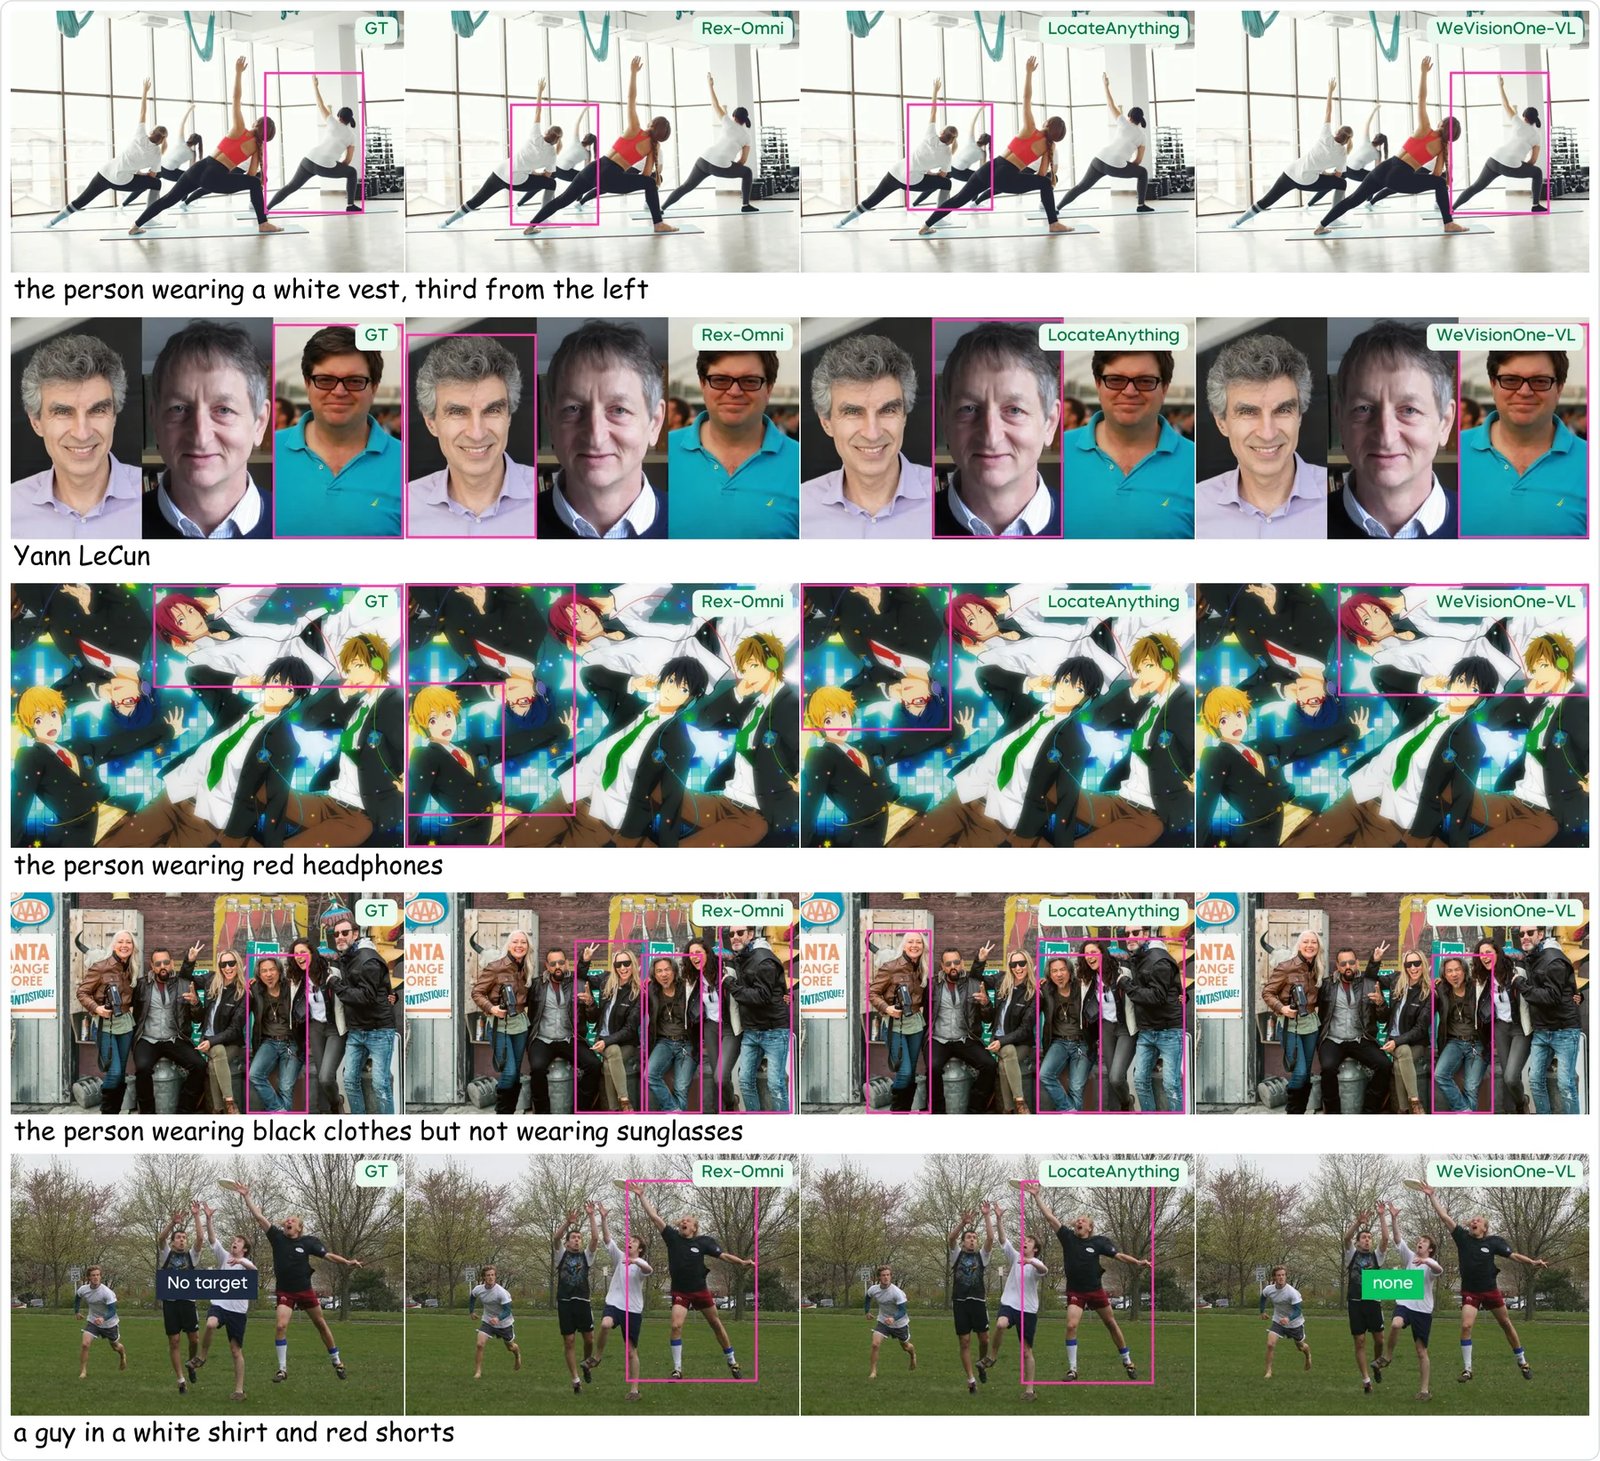
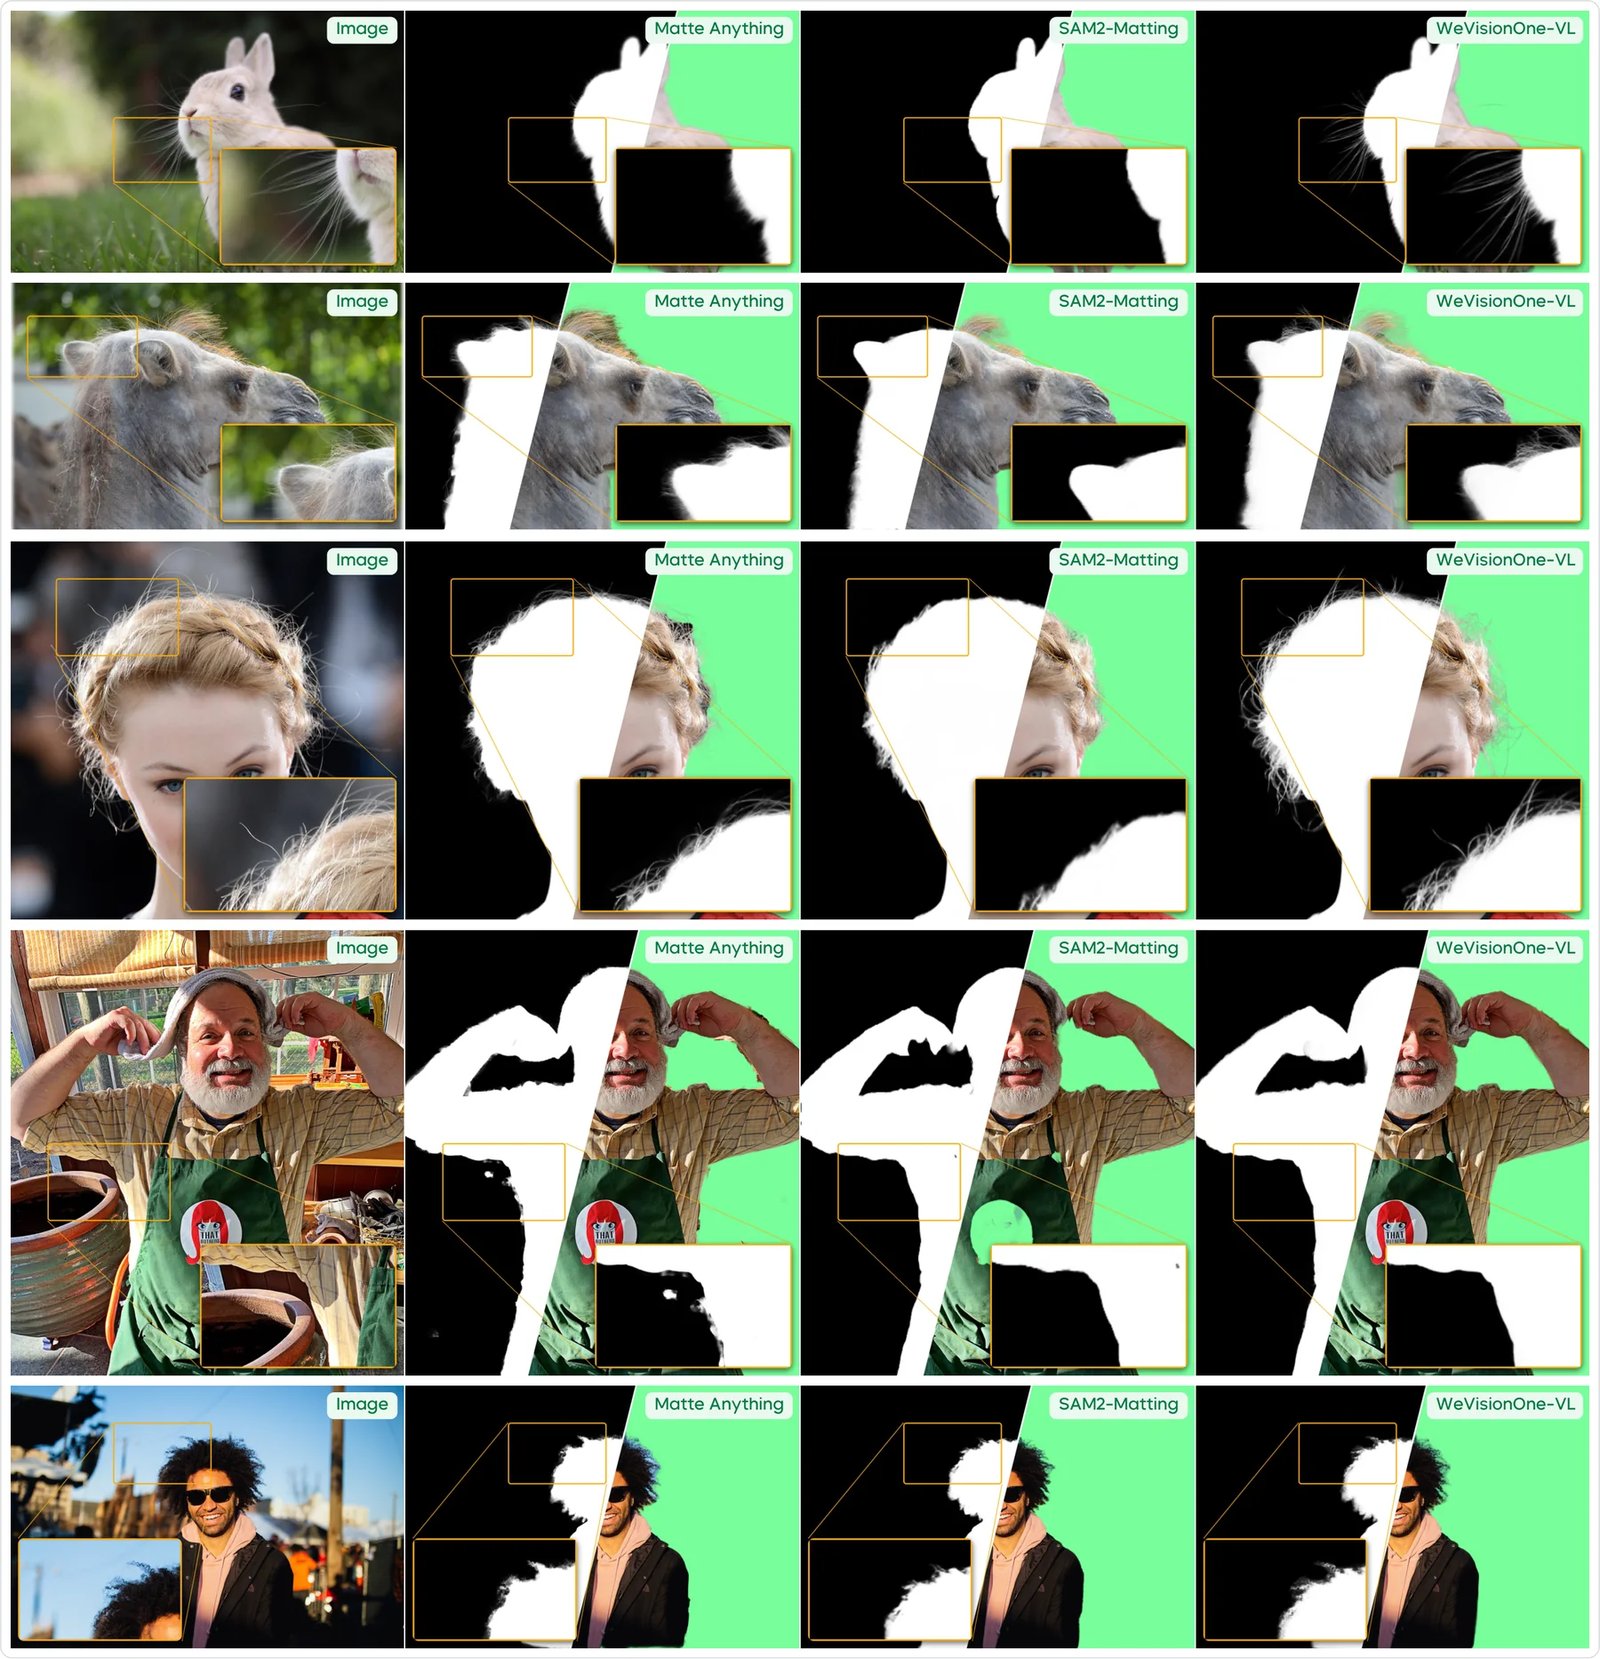
Box-prompted Matting — predicting the alpha matte of the target inside a given box
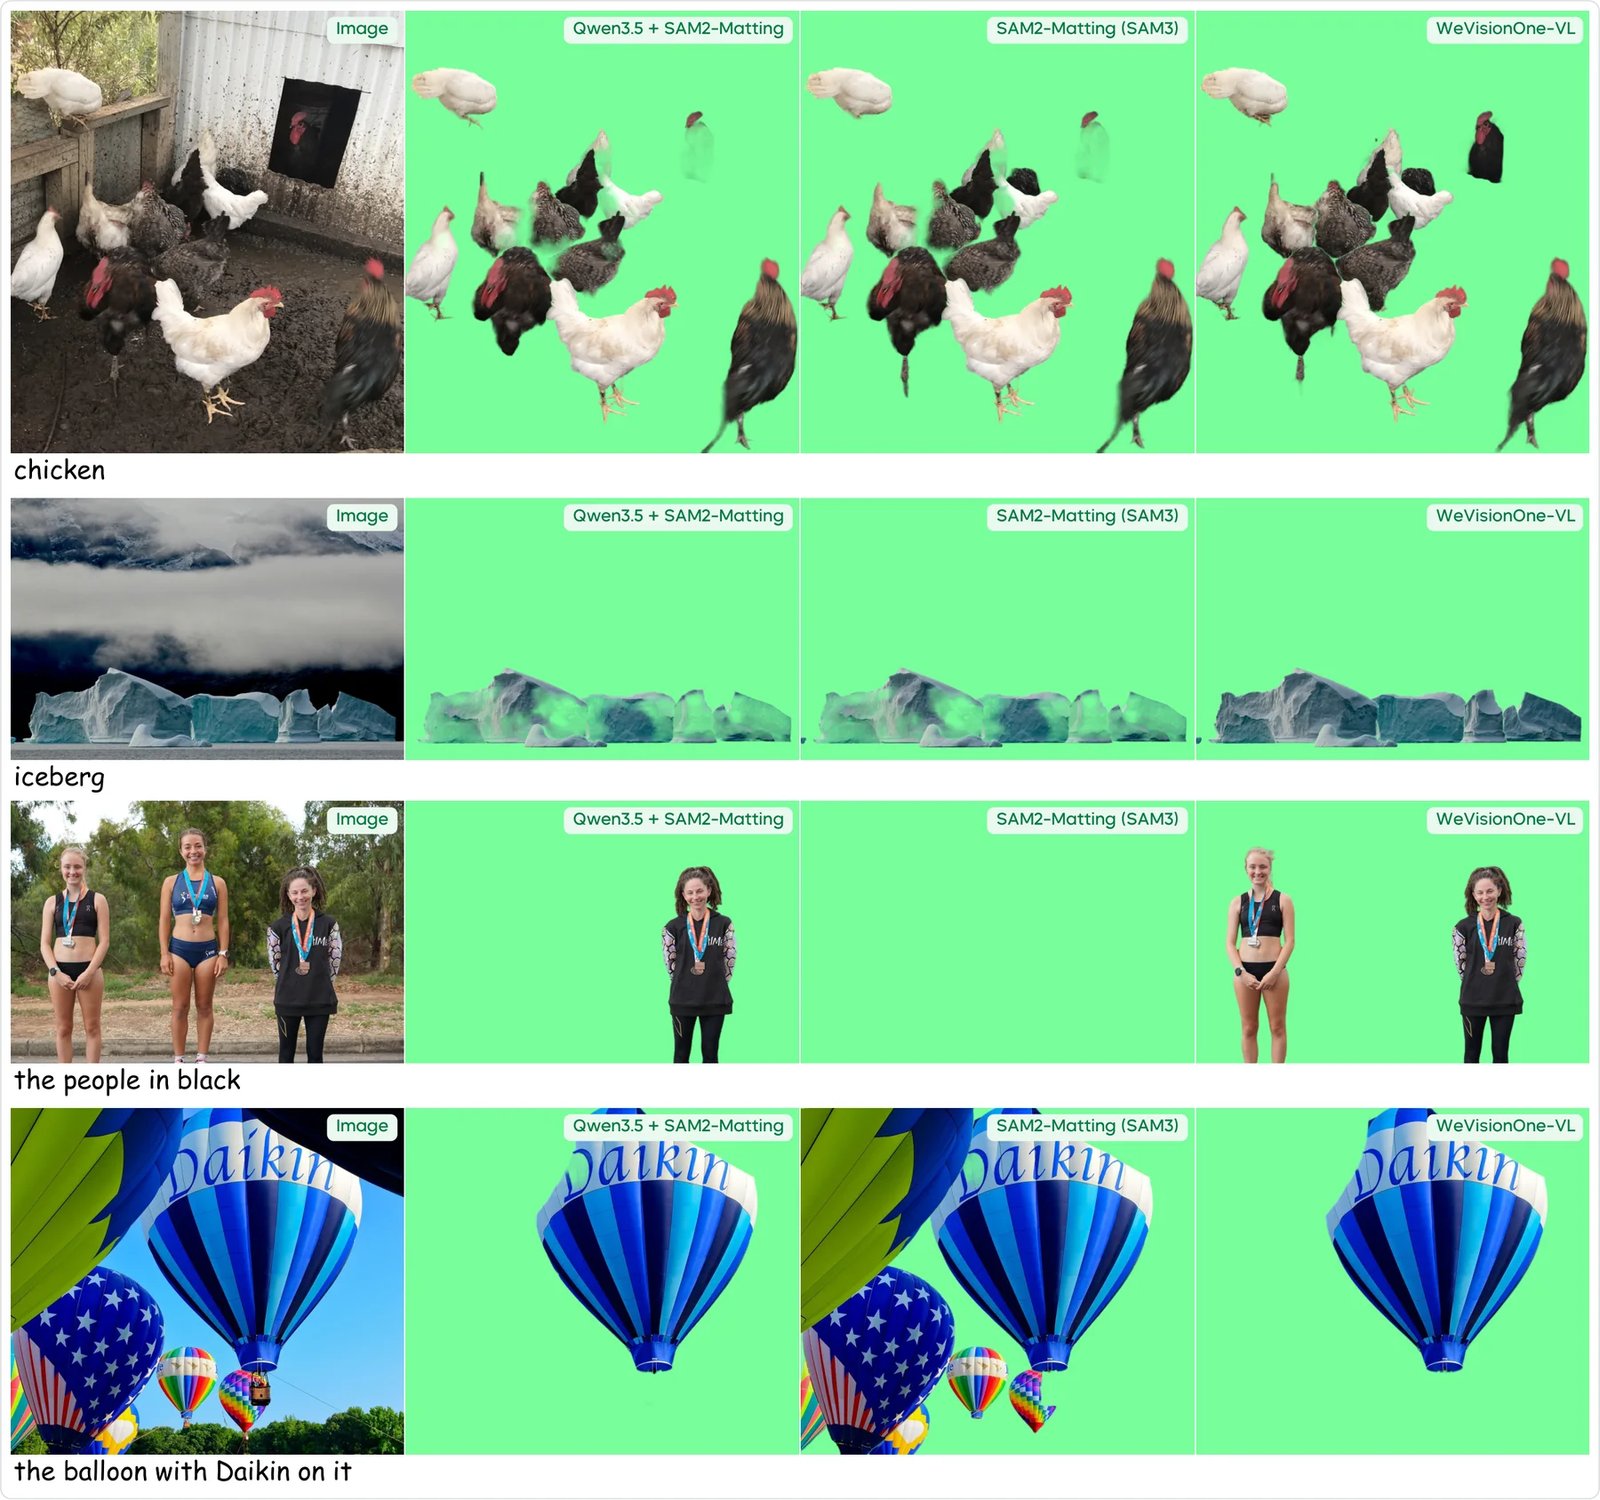
Text-prompted Matting — predicting the alpha matte of the target specified by a category name or referring expression
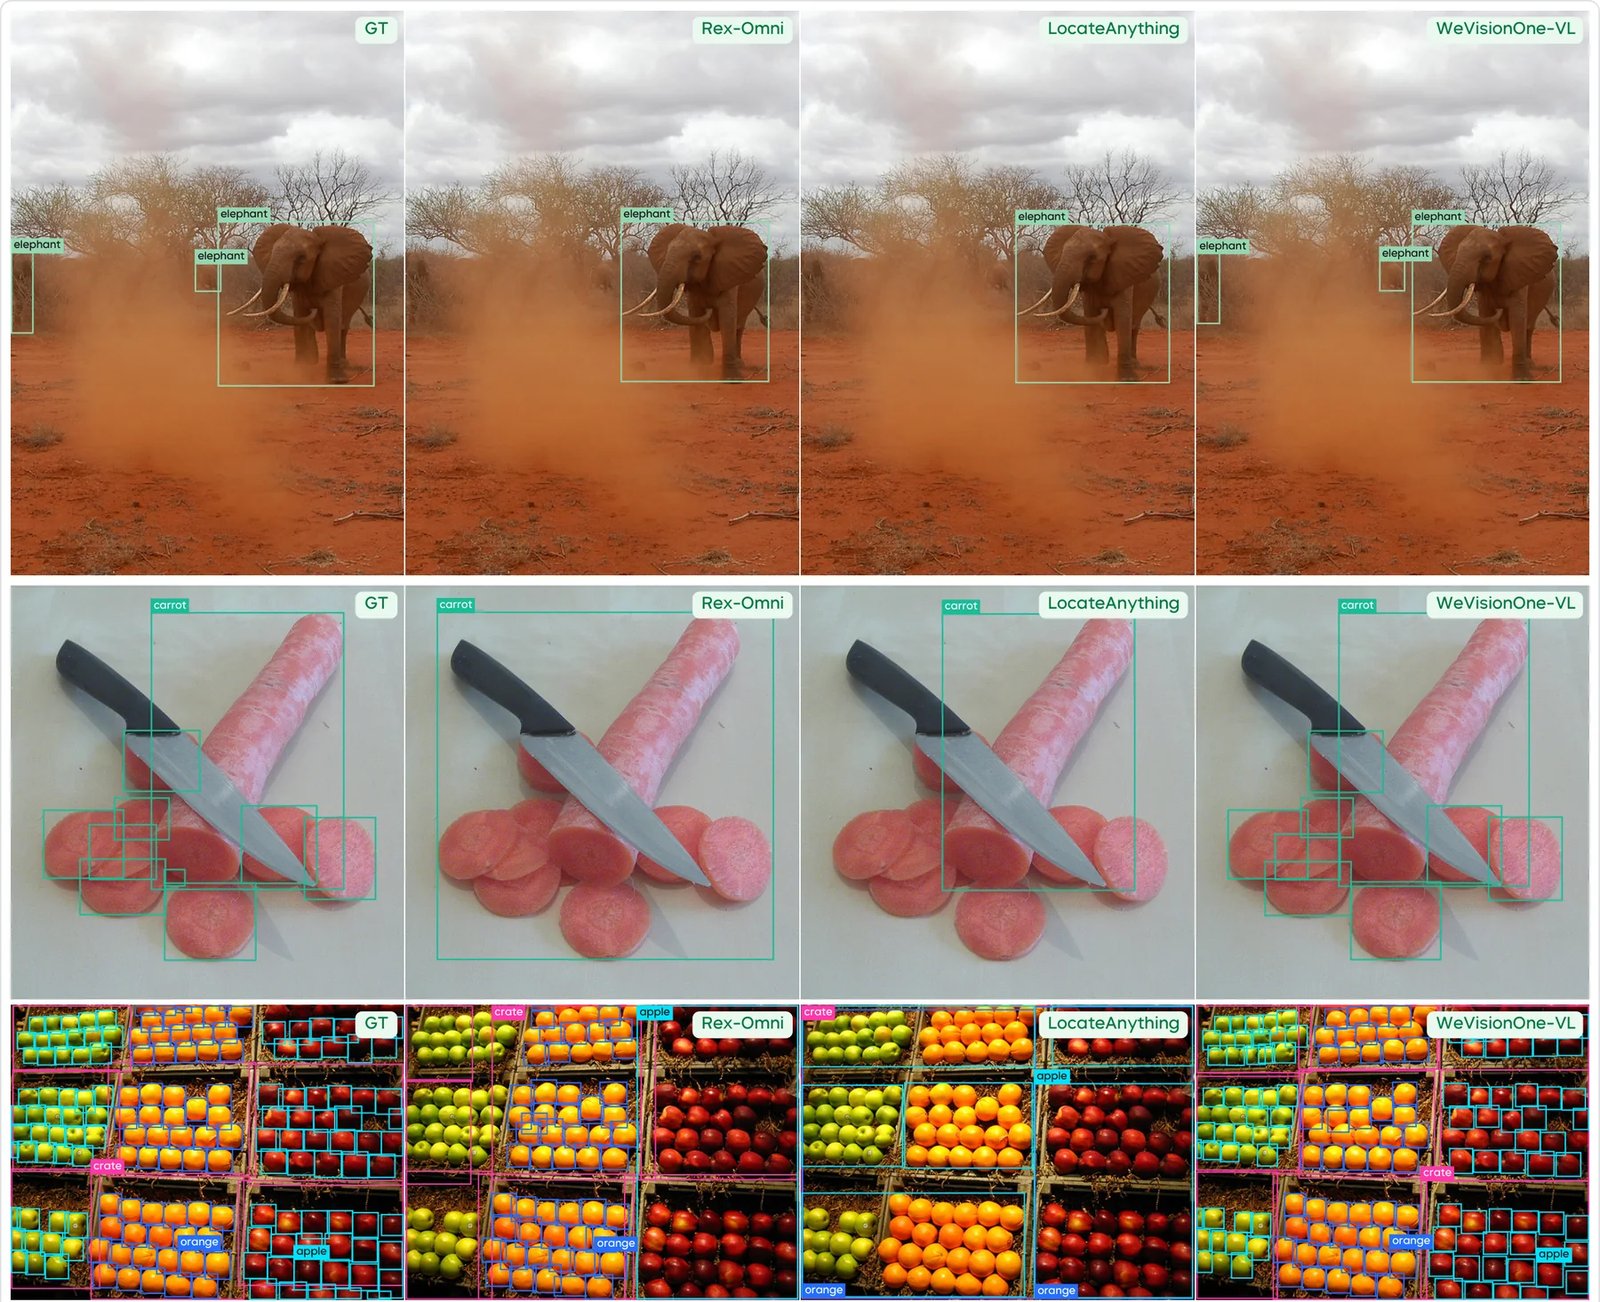
Object Detection — locating all instances of the given categories with boxes
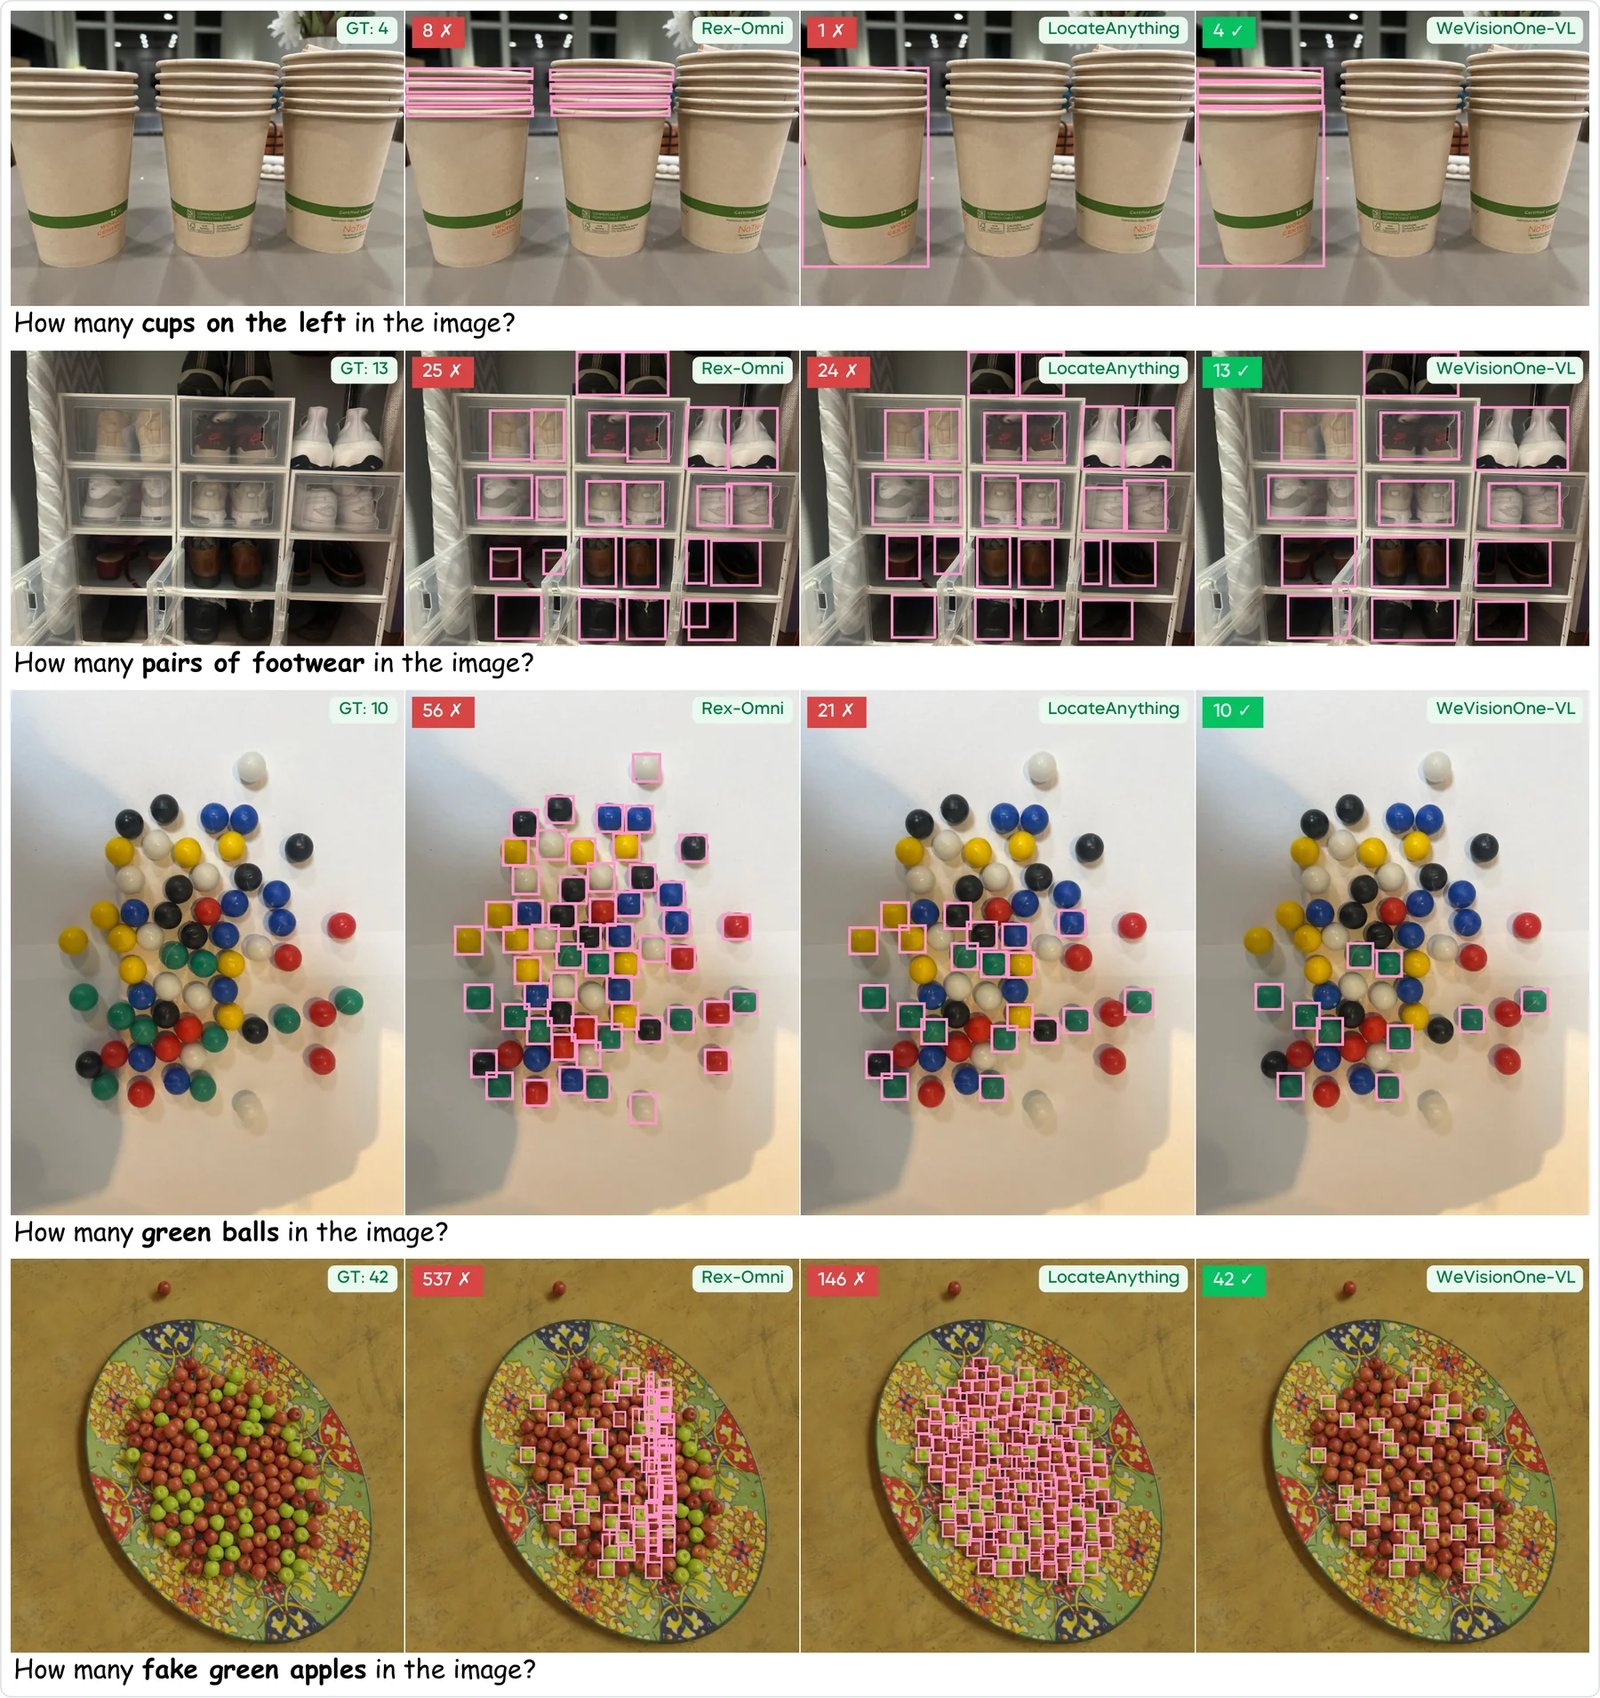
Object Counting — counting the instances that match a category or expression
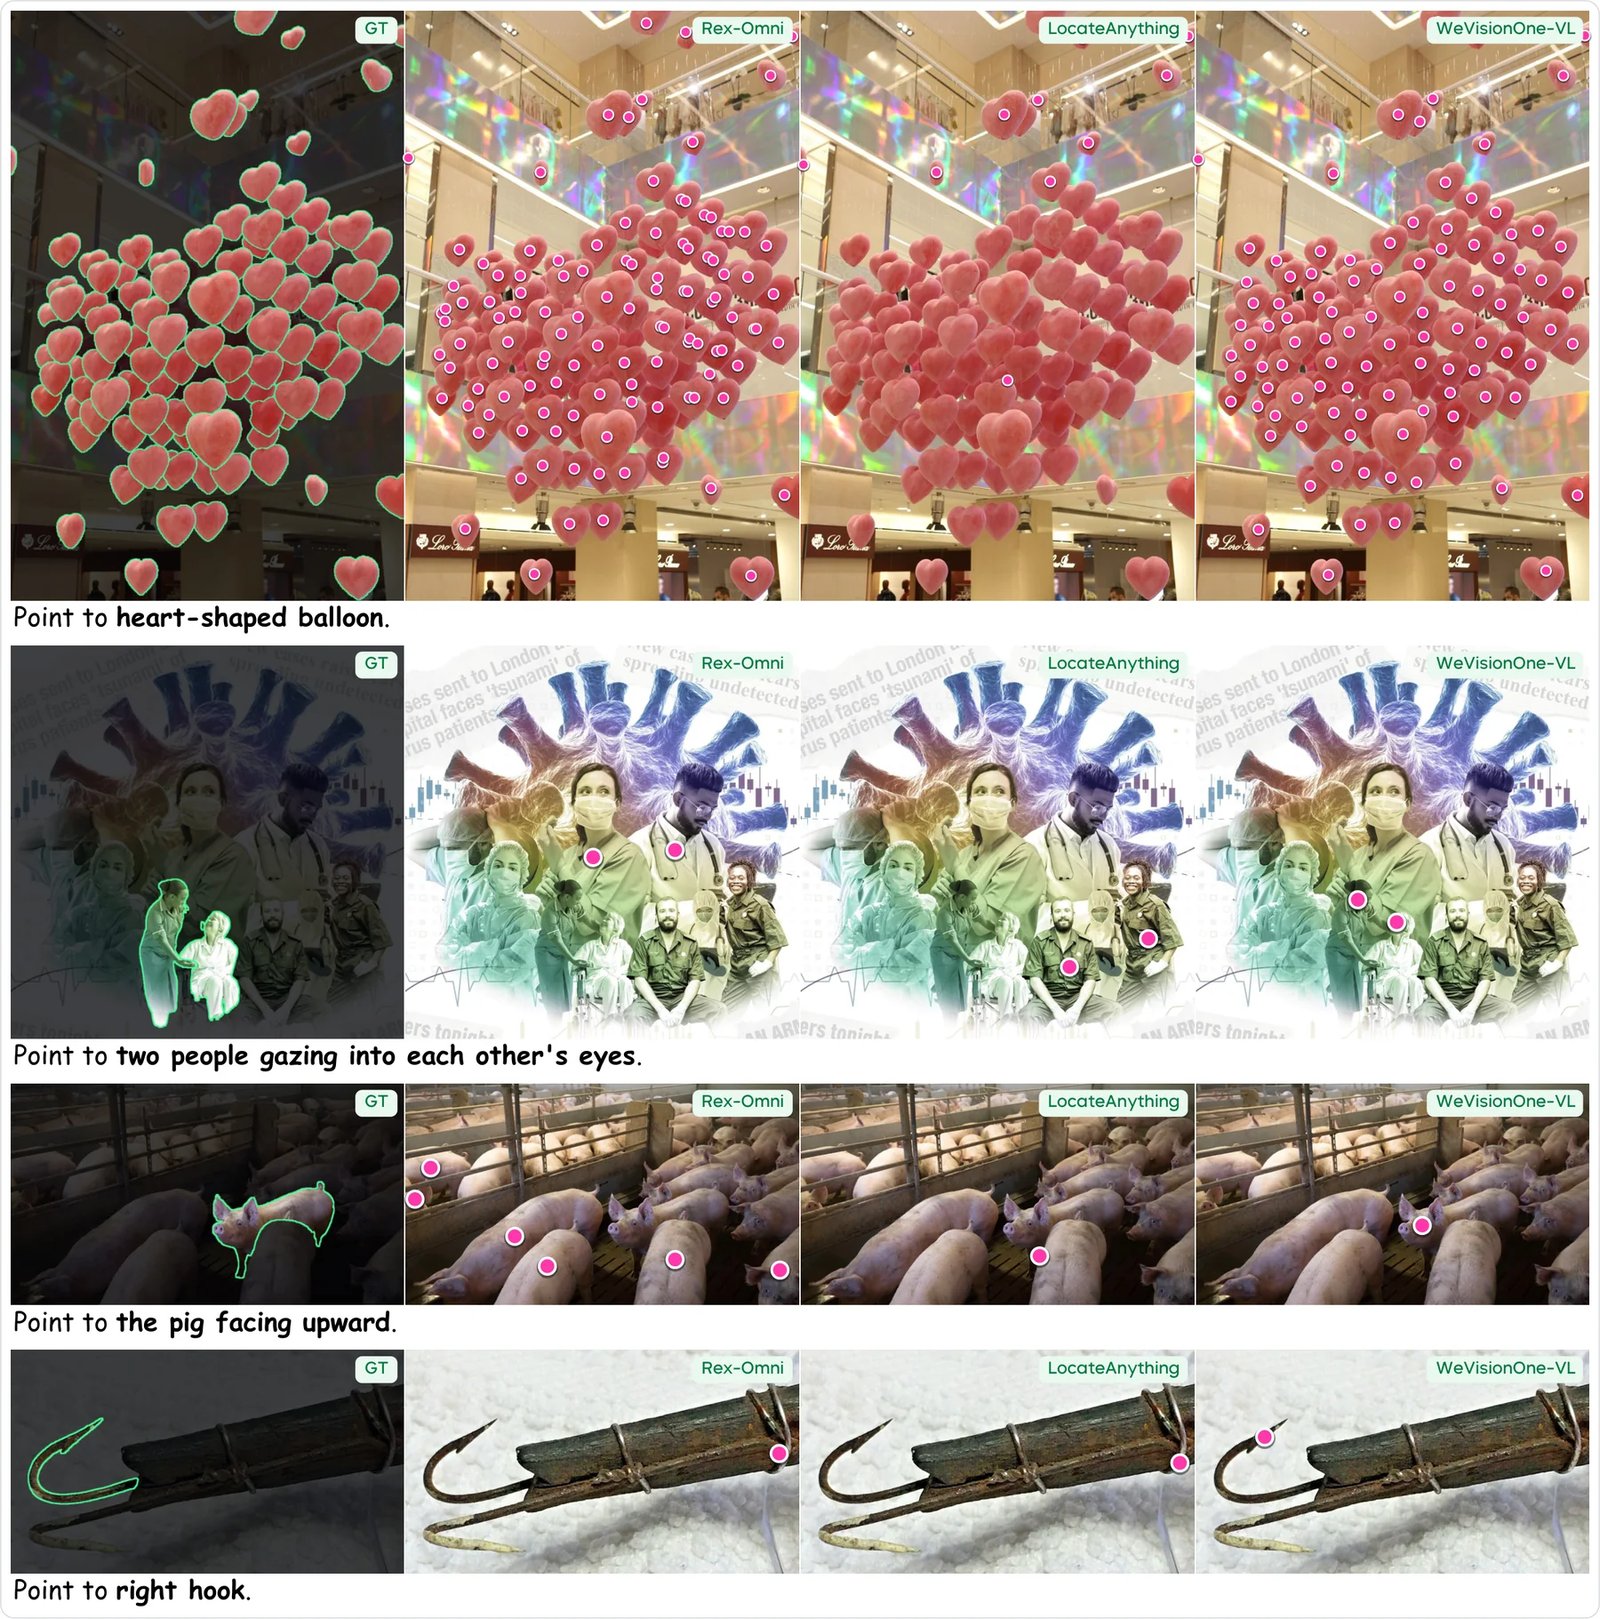
Object Pointing — marking each queried object with a point
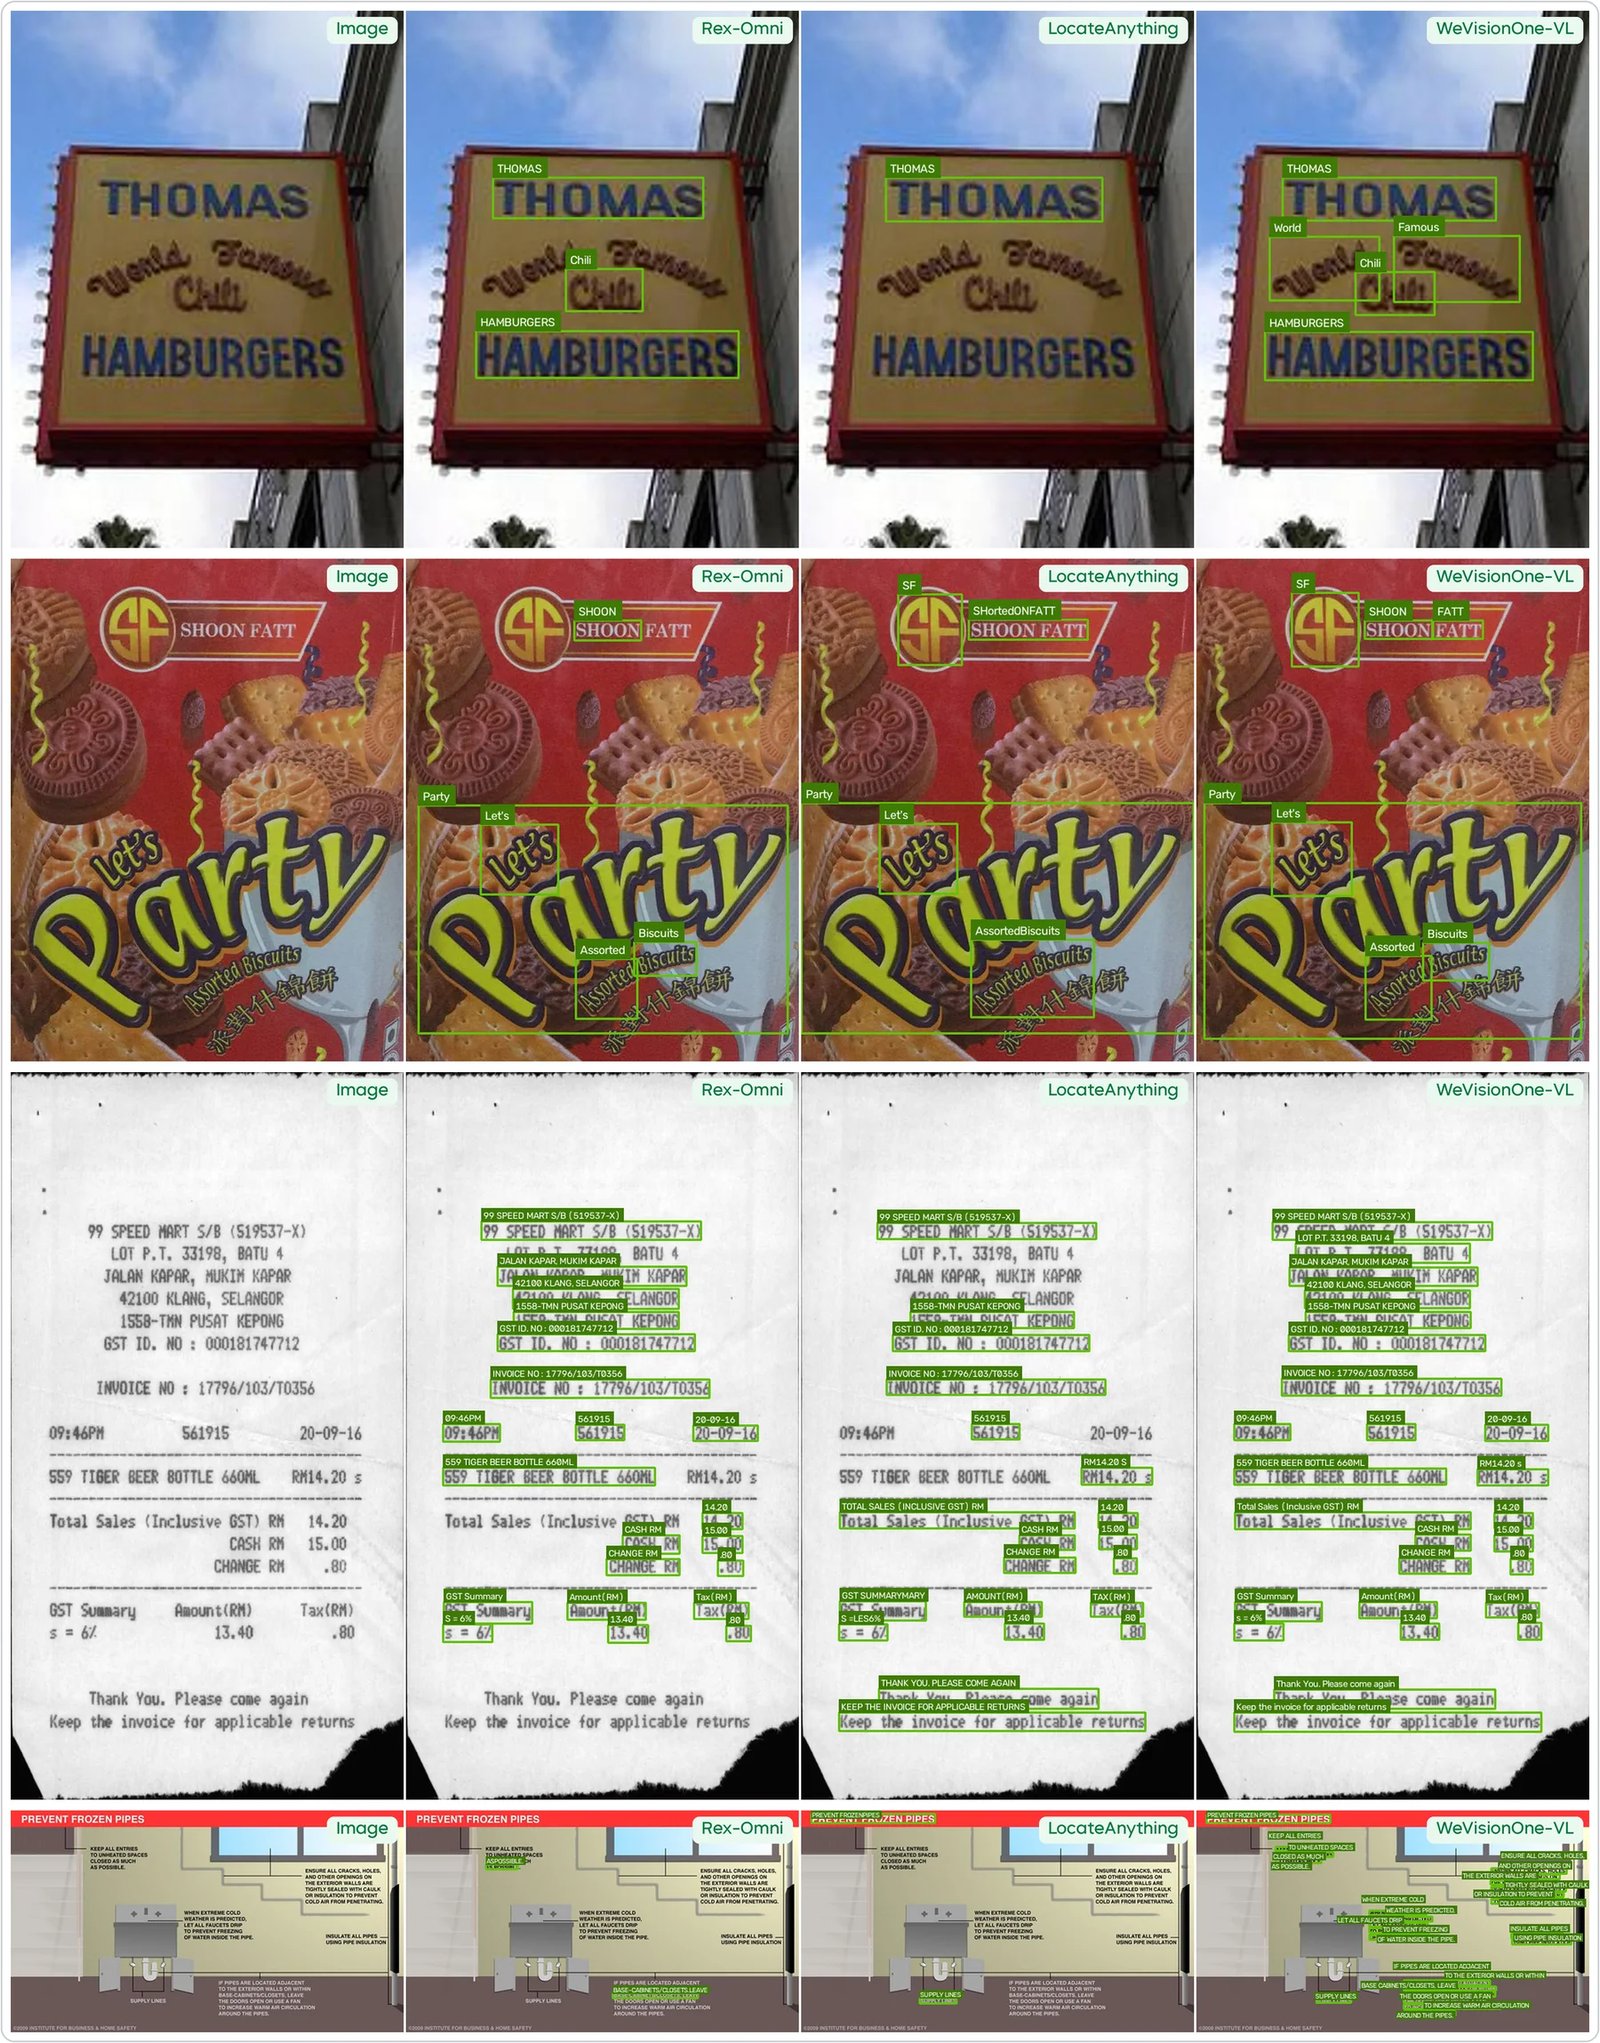
OCR — locating and recognizing text in the image
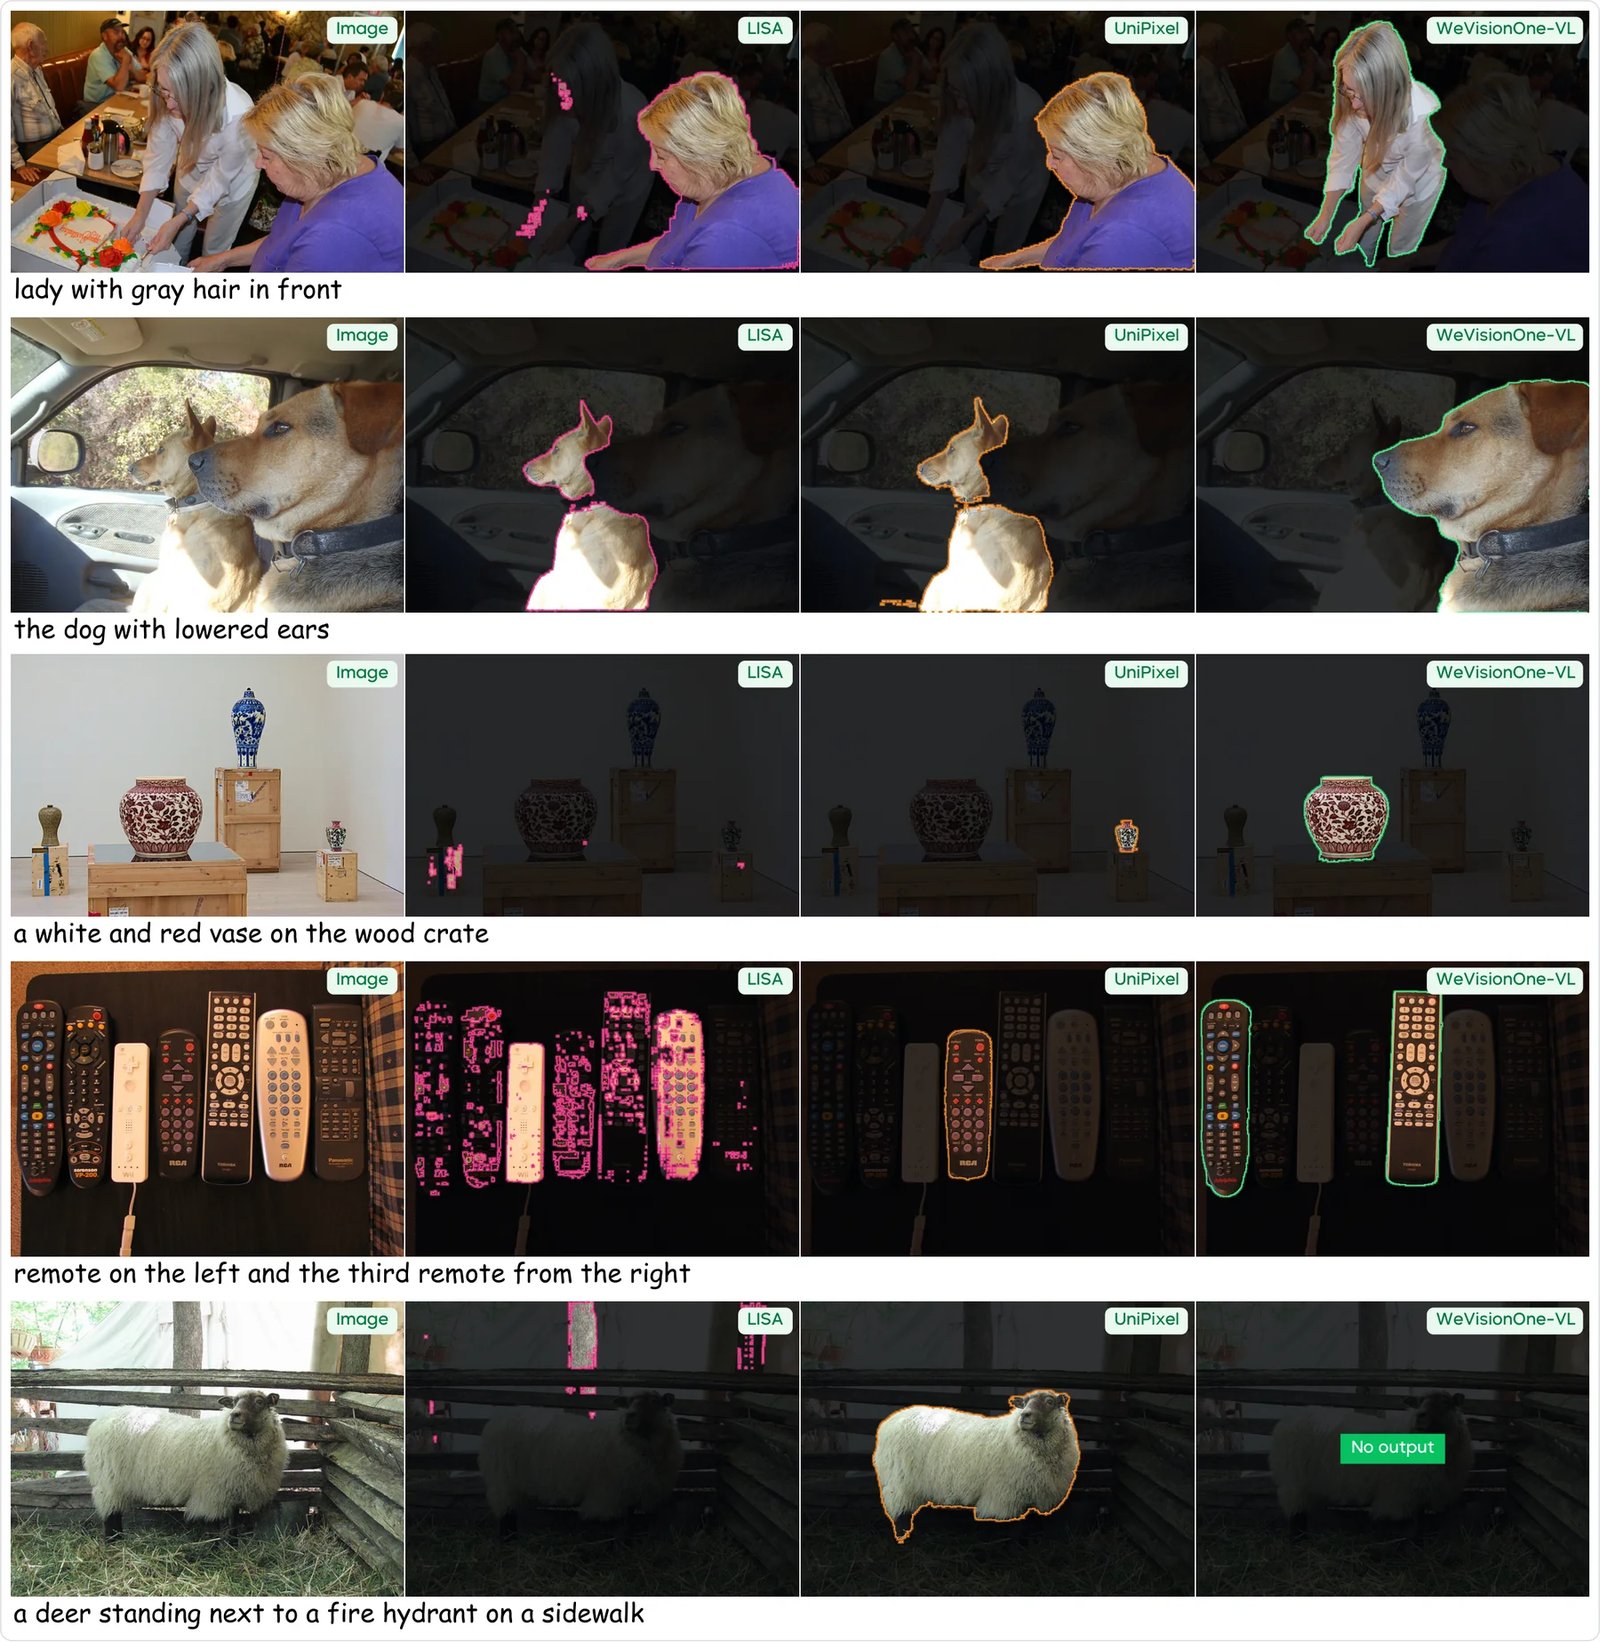
Referring Segmentation — segmenting the objects described by a natural-language expression
📜 License
Tencent-authored code in this repository is released under the Apache License 2.0. Third-party components keep their original licenses; please check the corresponding source files.
📖 Citation
If WeVisOne-VL is helpful to your work, please consider giving us a ⭐ and citing:
@article{liang2026wevisone,
  title={WeVisOne-VL: Unified Visual Perception from Objects to Pixels},
  author={Liang, Tianming and Pan, Junyi and Li, Yuxi and Fu, Canmiao and Huang, Zhipeng and Sun, Chong and Li, Chen and Lyu, Jing},
  journal={arXiv preprint arXiv:2610.31329},
  year={2026}
}