EAGLE-4
One Flexible Drafter for All Batch Sizes and Hardware
Paper (EAGLE-4) · EAGLE-4 draft for Qwen3.8-27B · Documentation


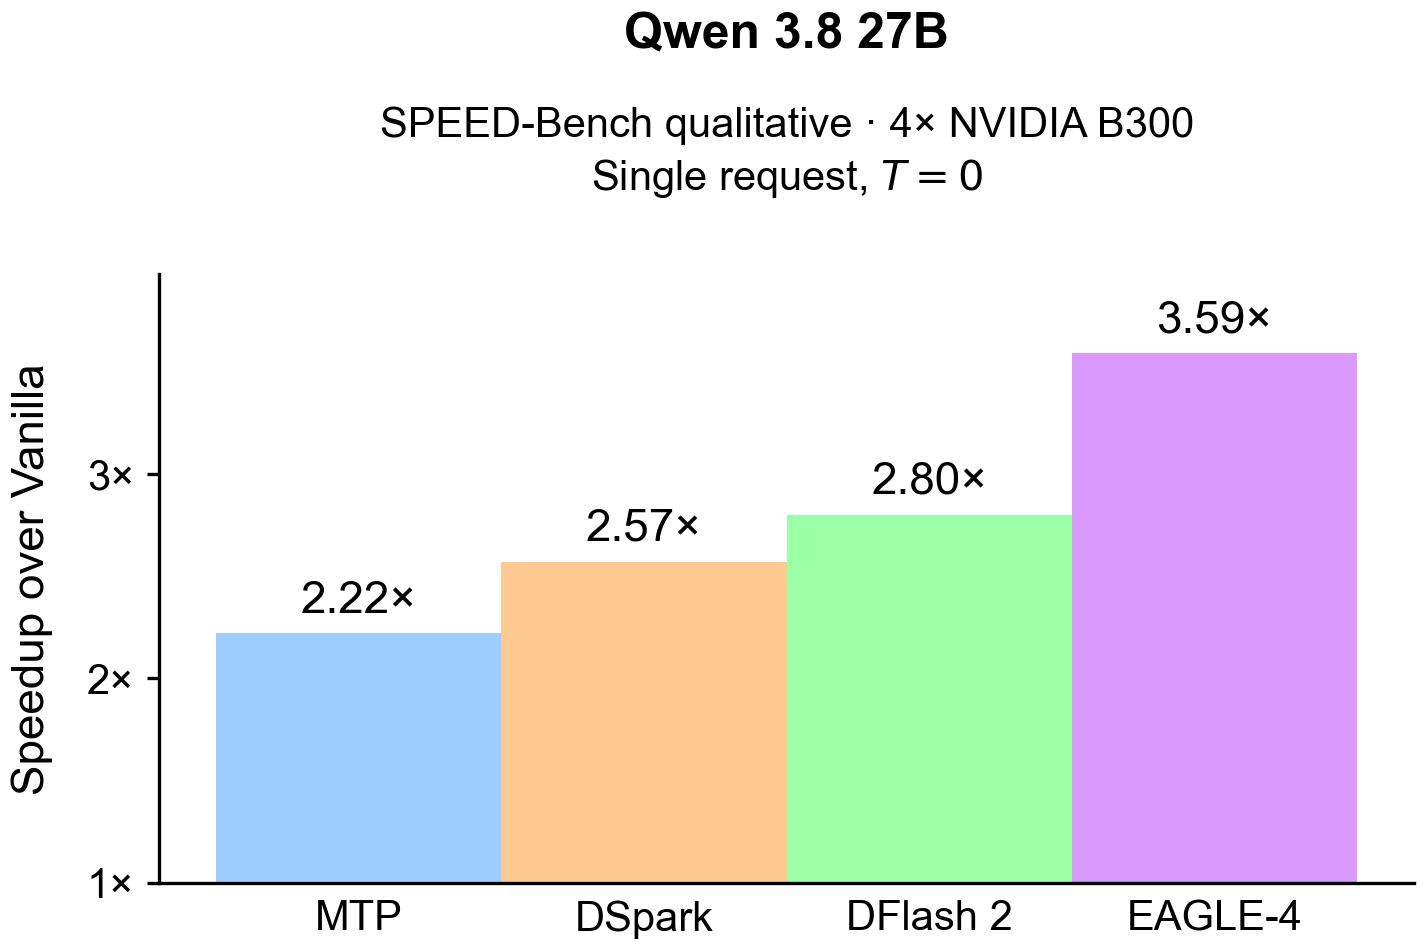
Figure 1(a) of the EAGLE-4 paper: Qwen3.8-27B on the SPEED-Bench qualitative split, 4× NVIDIA B300, one request, temperature 0. The numbers this release measured with EAGLE-4 are in the support matrix.
EAGLE-4
EAGLE-4 (Extrapolation Algorithm for Greater Language-model Efficiency) speeds up LLM inference with speculative decoding. One draft model adapts its draft tree to the batch size, the hardware and the workload, and keeps the target model's output distribution. On four B300 GPUs it serves Qwen3.8-27B 3.40× faster than SGLang without speculation for one request at a time.
This repository is eagle-harness, the package that runs EAGLE-4 drafts inside SGLang, vLLM and TokenSpeed.
Quick start
You need Linux, four NVIDIA GPUs with a CUDA 13 driver (tested on B300) and about 70 GB of disk for Qwen3.8-27B and its EAGLE-4 draft, which download on the first start.
Start an SGLang server with Docker:
docker run --gpus all --ipc host -p 127.0.0.1:30000:30000 \
  -e HF_HOME=/hf -v ~/.cache/huggingface:/hf \
  ghcr.io/eagle-hq/eagle-4-sglang:0.1.0 \
  sglang serve --model-path Qwen/Qwen3.8-27B --tp-size 4 --host 0.0.0.0 \
  --disable-overlap-schedule --speculative-algorithm EAGLE_HARNESS \
  --speculative-draft-model-path EAGLE-Corp/Qwen3.8-27B-EAGLE4 \
  --speculative-num-steps 12 --speculative-eagle-topk 4 --speculative-num-draft-tokens 16 \
  --speculative-algorithm-config '{}'
Or install with pip, in Python 3.12. Pip installs also need the CUDA toolkit and a C++ compiler:
python3.12 -m venv .venv && source .venv/bin/activate
pip install "eagle-harness[sglang]" "sglang==0.5.23.dev252+eagle.5" \
  --extra-index-url https://eagle-hq.github.io/EAGLE-4/whl/cu130/ \
  --extra-index-url https://download.pytorch.org/whl/cu130 \
  --extra-index-url https://pypi.nvidia.com
sglang serve --model-path Qwen/Qwen3.8-27B --tp-size 4 \
--speculative-algorithm EAGLE_HARNESS \
--speculative-draft-model-path EAGLE-Corp/Qwen3.8-27B-EAGLE4When the server logs The server is fired up and ready to roll!, send a request from another terminal:
curl http://localhost:30000/v1/chat/completions -H 'Content-Type: application/json' \
  -d '{"model": "Qwen/Qwen3.8-27B", "messages": [{"role": "user", "content": "Explain how a hash table works."}], "max_tokens": 256}'
For vLLM, TokenSpeed (experimental) and AMD MI355X, follow the engine guides.
Measured speedup
Each speedup divides EAGLE-4 throughput by the same engine's throughput without speculation, on Qwen3.8-27B at temperature 0 on the SPEED-Bench client, with the measured recipe of each engine guide. The support matrix has the tokens/s, the correctness checks and how each number was measured.
| Engine | GPUs | 1 request | 8 concurrent | 64 concurrent |
|---|---|---|---|---|
| SGLang | 4× B300 | 3.40× | 1.91× | 1.35× |
| vLLM | 4× B300 | 2.99× | 1.70× | 1.16× |
| TokenSpeed, experimental | 4× B300 | not measured | 2.02× | 1.42× |
On one AMD MI355X, SGLang with EAGLE-4 is 2.07× faster at 8 concurrent requests and 1.56× at 32.
More
- Install: pins, wheel indexes, Docker images and the ROCm closure.
- Engine guides with the measured recipes: SGLang, vLLM, TokenSpeed, experimental, AMD MI355X.
- Support matrix and known limits.
- Calibration, configuration and troubleshooting.
- How it works, kernels, compatibility, new models and the FAQ.
Citation
If you use EAGLE-4, cite the EAGLE-4 paper. EAGLE-4 builds on EAGLE, EAGLE-2 and EAGLE-3, which
CITATION.cff also lists.
@misc{eagle4,
    author = {EAGLE-4 Team},
    title = {{EAGLE-4}: One Flexible Drafter for All Batch Sizes and Hardware},
    year = {2026},
    note = {Preprint}
}
Acknowledgements
- Thanks to Aditya Nandakumar (@proaditya) and the contributors to the original EAGLE-4 PR 1 for the ROCm port of EAGLE-4 on AMD Instinct MI355X.
- Thanks to Andy Luo (@andyluo7) and the contributors to the original EAGLE-4 PR 2 for the AMD AITER and Triton kernels on GFX950.
- Thanks to Andy Luo (@andyluo7), Aditya Nandakumar (@proaditya) and the contributors to the merged AMD series in the original EAGLE-4 PR 4 for AITER/FA3 and Split-KV on GFX950.
- Thanks to Nicolas Perrin (@nperrin-fr) and the TokenSpeed/LightSeek contributors for the TokenSpeed implementation in the original EAGLE-4 PR 3, including the MLP L2 warm-ahead and TGV SwiGLU work used in the TokenSpeed fork.
- SPEED-Bench is by NVIDIA. Model weights are licensed by their owners.
License and trademark policy
Eagle 4 is source-available software, not OSI-approved open-source software. The terms of the Eagle 4 Source-Available License govern its use, modification, and distribution, and incorporate the Eagle Trademark Policy. See also the NOTICE file.
Commercial Use of a Competing Offering requires a separate written commercial license regardless of revenue. Other Commercial Use is permitted only within the conditions of the license, including the US $20 million Aggregate Revenue threshold measured over any consecutive 12-month period. If the threshold is exceeded, a separate commercial agreement is required before beginning or continuing any Commercial Use. The license specifies that the requirement continues after a subsequent revenue decrease.
Downloading, cloning, forking, copying, accessing, modifying, using, hosting, distributing, or otherwise exercising any licensed right constitutes acceptance of the Source-Available License and incorporated Eagle Trademark Policy. Mere viewing or inspection does not itself constitute trademark use.
For separate commercial terms, see the
Commercial License Agreement and contact
licensing@eagle.ai. Publishing that agreement does
not grant commercial-license rights; it becomes binding only as stated in
its Section 1. Files derived from
sglang, vLLM, FlashInfer and other projects keep those projects' notices, listed in
THIRD_PARTY_NOTICES.md.
Contributing
By submitting, uploading, pushing, committing, proposing, or otherwise providing
a pull request, patch, issue attachment, model, weight, dataset, documentation,
or other contribution to this repository, you agree to the Eagle Contribution
License and Submission Terms
(PDF). If you do not agree, do not submit a contribution. If you act for an
employer, client, partner or other entity, you represent that you have authority
to submit the contribution and have obtained all required permissions.
Submitting a contribution does not change the license of existing Eagle code;
Eagle AI Corp controls outbound licensing for accepted contributions. See
CONTRIBUTING.md for the licensing structure and for how to
build, test and open a pull request.