
Basalt is a local inference engine for large language models: Qwen3.8-Flash-Next, DeepSeek-V4.1-Flash, Qwen3.8-27B, Hy4-flash and Inkling 2 Mini. It runs on an NVIDIA Blackwell GPU (sm_120) on Linux and Windows x64, with what does not fit in VRAM (the experts of a mixture-of-experts model) in system RAM, and optionally on more GPUs. The server speaks the OpenAI and Anthropic APIs. Website: basalt.jgulfo.com.
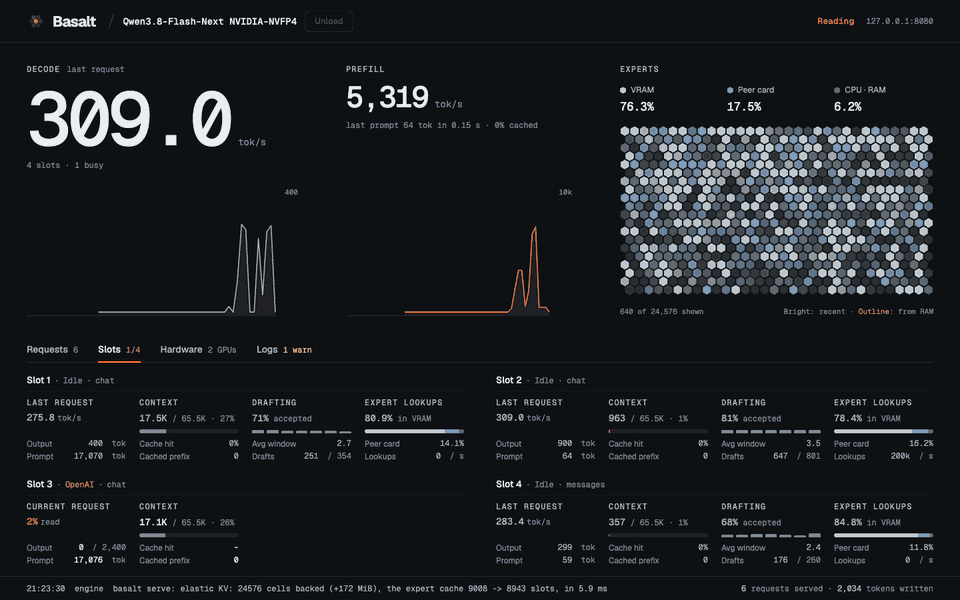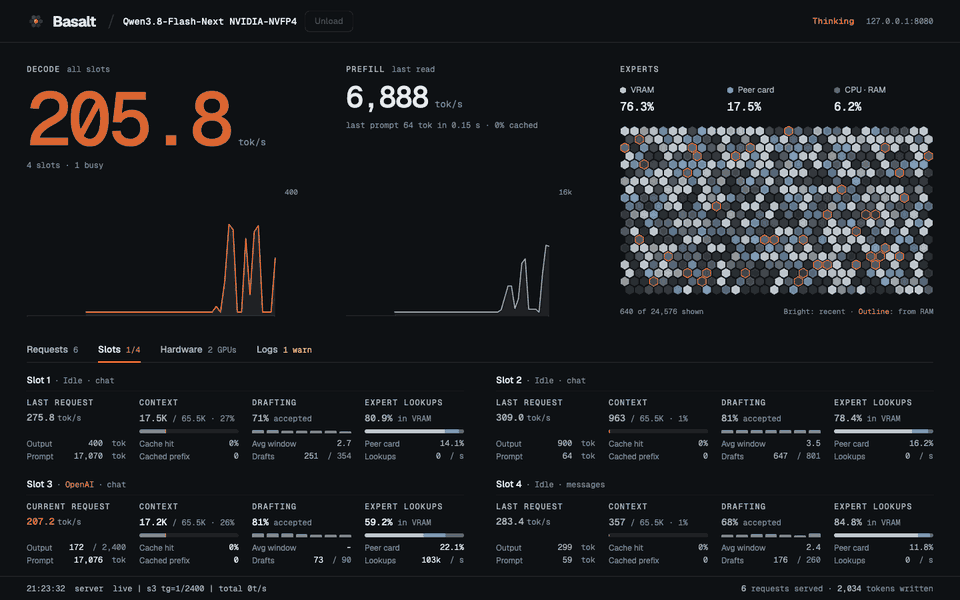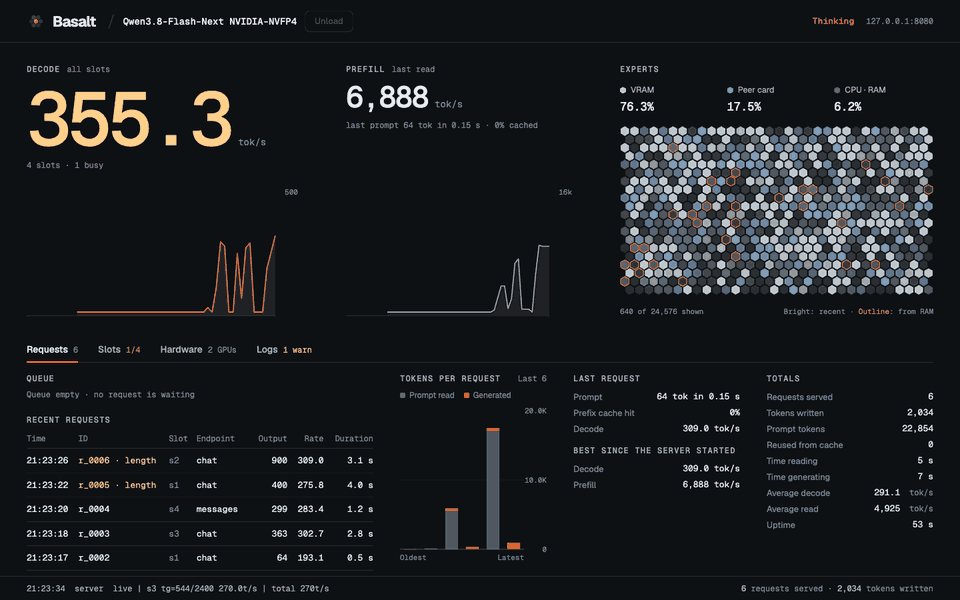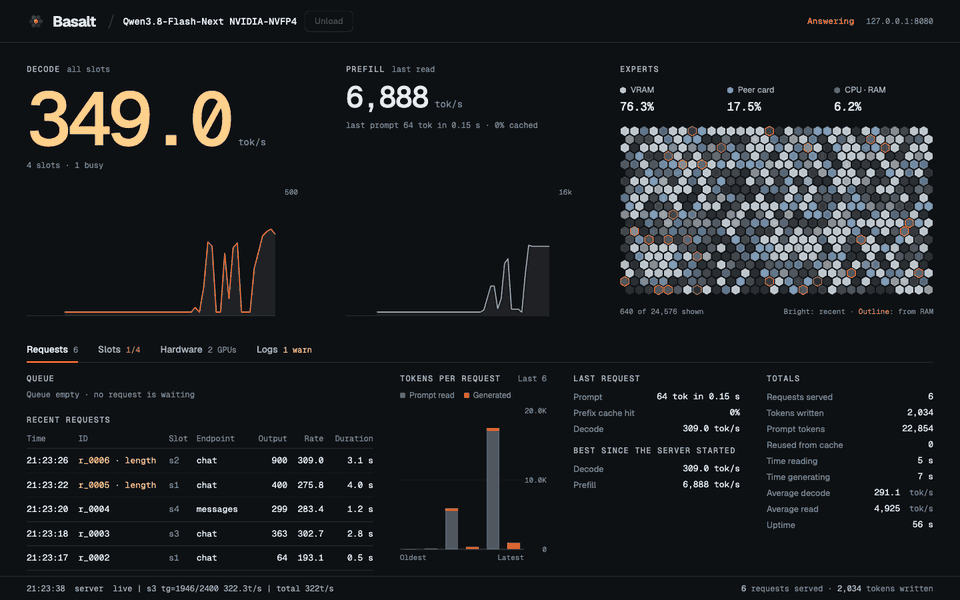
Help wanted: spare Blackwell compute for testing? See Contributing.
Requirements
- Linux x86-64 with AVX2, or Windows 10 1903+ x64 (platforms).
- An NVIDIA Blackwell GPU (compute capability 12.0) with CUDA 13.
- CMake 3.24+, GCC 13+ (Linux), Python 3.10+, and enough system RAM for the experts that do not fit in VRAM.
Quick start
Prebuilt Linux and Windows archives are attached to each release (what they need); otherwise build from source:
git clone https://github.com/jesdga95/basalt && cd basalt
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release
cmake --build build -j                  # bin/basalt, bin/basalt-bench, bin/basalt-probe, bin/basalt-vision
                                        # Windows: add -G Ninja to the first line, from an x64 VS 2022 prompt ([platforms](docs/platforms.md#building-on-windows))
                                        # one model only: -DBASALT_MODELS=qwen4exp, deepseek41, qwen35, hy4flash or inkling2 ([building](docs/building.md#building-only-some-models))
pip install -r requirements.txt
hf download jesdga/Qwen3.8-Flash-Next-Basalt Qwen3.8-FN-NVFP4-DQ6_K.basalt --local-dir models
Put the settings in basalt_config.json:
{
  "version": 2,
  "models": [{ "model": "models/Qwen3.8-FN-NVFP4-DQ6_K.basalt", "gpu": "0,1", "kv": "int8" }],
  "engine": { "resident-experts": true },
  "server": { "port": 8080 }
}
bin/basalt serve --config basalt_config.jsonThe server listens on 127.0.0.1. Every setting: configuration. More examples: example configurations.
Models
| Qwen3.8-Flash-Next | DeepSeek-V4.1-Flash | Qwen3.8-27B | Hy4-flash | Inkling 2 Mini | |
|---|---|---|---|---|---|
| Packs | default Qwen3.8-FN-NVFP4-DQ6_K, Hugging Face | default DeepSeek-V4.1-Flash-1017-UD-IQ1_M, Hugging Face | Qwen3.8-27B-QUASAR-NVFP4, Hugging Face | Hy4-flash-NVFP4, Hugging Face | Inkling-2-Mini-NVFP4-DQ8, Hugging Face |
| Context | up to 262,144 (longer with YaRN) | up to 1,048,576 | up to 262,144 | up to 1,048,576 | up to 1,048,576 |
| Drafting | MTP, on by default | DSpark, on by default | DFlash 2, on by default | DFly2, on by default | DSpark, on by default |
| Images | yes | yes | yes | yes | yes |
| Documents (PDF, text) | yes | yes | yes | yes | yes |
| Guide | guide | guide | guide | guide | guide |
| Precision | precision | precision | precision | precision | precision |
All models compared, with each one's context limit, flags and cards: models.
Video
Qwen3.8-Flash-Next and Qwen3.8-27B read video; DeepSeek, Hy4-flash and Inkling 2 Mini do not. A video is named like an image in a chat message, and needs
--vision and FFmpeg on the machine. Flash-Next decodes frames on the GPU with NVDEC; the 27B decodes them on the CPU.
How a request names a video, and the limits: video.
Documentation
- Run: running, configuration, models and the router, sampling, image sources, documents, diagnostics, basalt-probe, platforms.
- Models: models, Flash-Next, DeepSeek,
Qwen3.8-27B, Hy4-flash, Inkling 2 Mini,
the
.basaltfile, file format changes. - Quality: precision, method.
- Build and develop: building, adding a model, community runs, changelog, contributing.
Credits
- Code: Strata, the project Basalt forks (MIT); Infernix (Ian Ranson and contributors, Apache-2.0), whose kernels are adapted; ggml and llama.cpp (MIT); and ideas from NInfer. Licences: THIRD_PARTY_LICENSES.
- Models: Qwen, DeepSeek, Tencent (Hy4-flash) and Thinking Machines Lab (Inkling 2 Mini), under the licences on their cards; Unsloth's GGUFs; NVIDIA's NVFP4 checkpoints; QUASAR-QAT's NVFP4 27B (Apache-2.0); z-lab's DFlash 2 drafter.
Thank you to everyone who has contributed or sponsored the project.
License
MIT, see LICENSE.