


Jiamu Zhang1 Tianze Yang1 Yucheng Shi2 Liang Wu1
1 Nokia, Sunnyvale, CA 2 Tencent Hunyuan
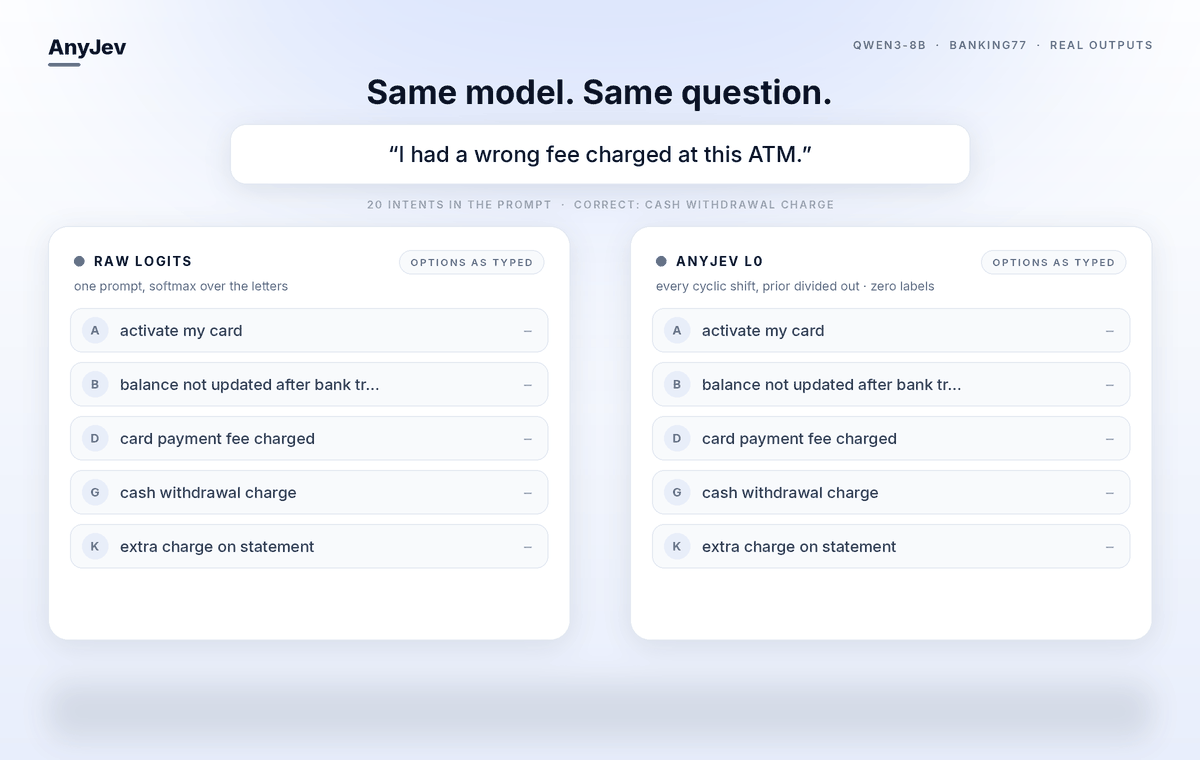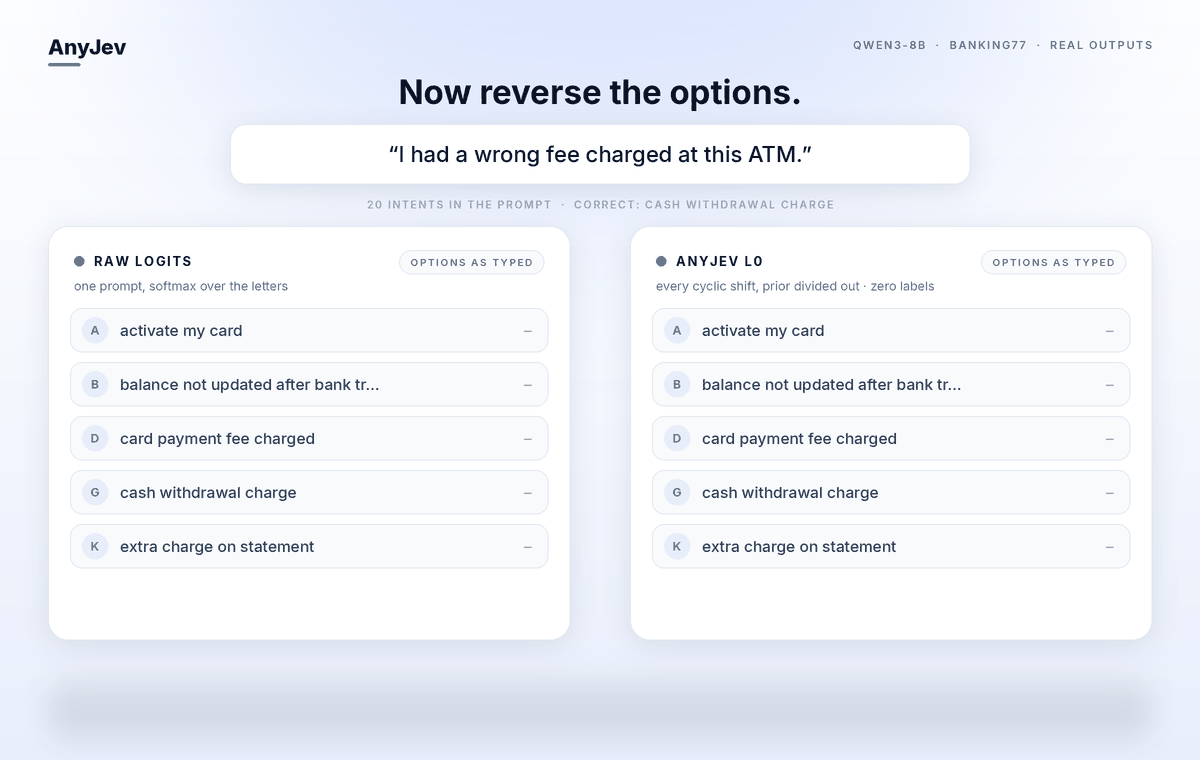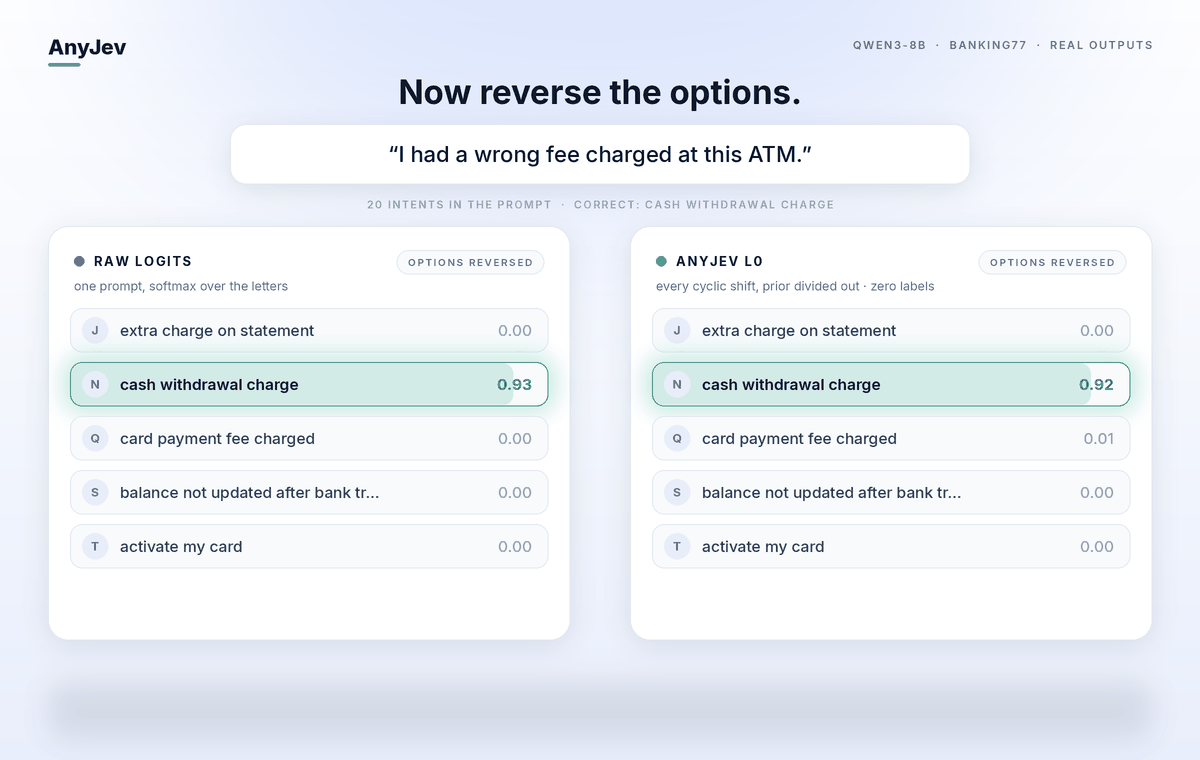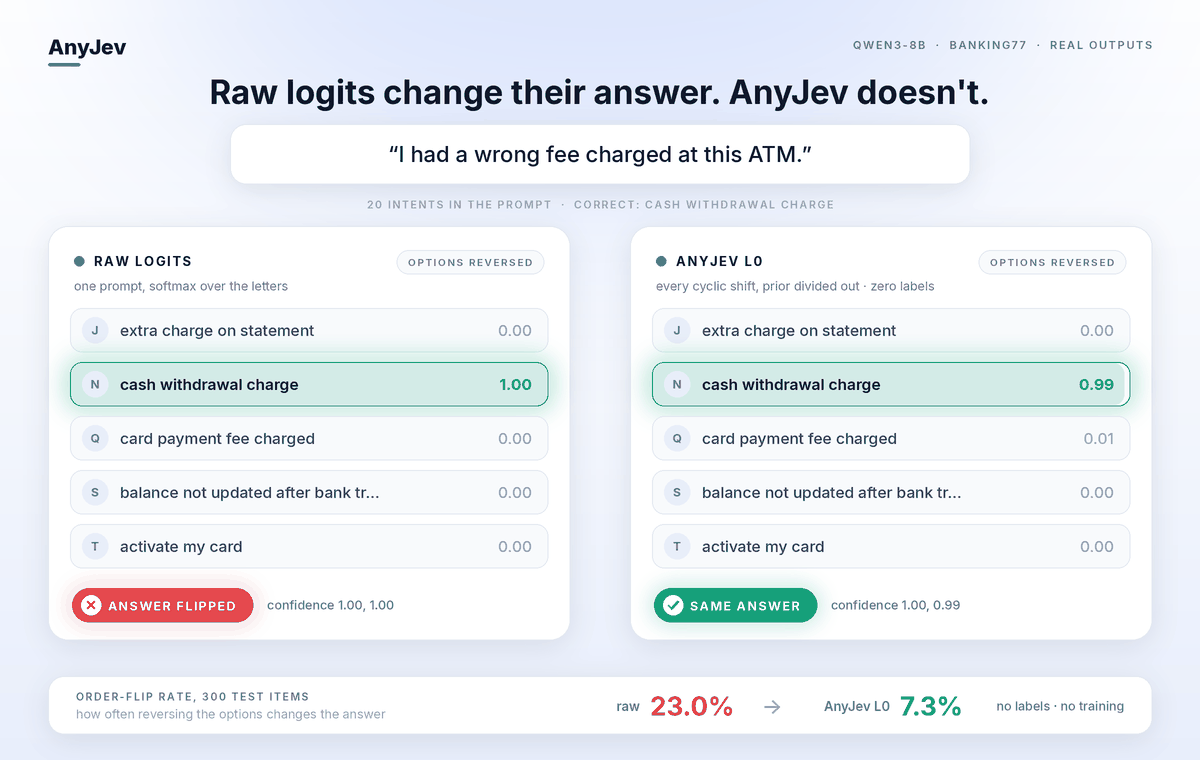
Qwen3-8B on a real BANKING77 item. Every number is a model output.
[!TIP] 🆕 L2 has landed. A closed-form head per question, solved on 100–300 labels in seconds, served from one prompt stopped at two thirds of the model's depth. It follows its question across rewordings without new labels. Jump to it ↓
✨ What it does
Ask any open LLM a typed question and get back a decision with a probability you can threshold, read from one prefill of its next-token distribution. No generation, no parsing, no fine-tuning. Raw logits change their answer when you reorder the options, and their confidence cannot be trusted; AnyJev fixes the first with zero labels and the second with a few hundred.
| raw logits | AnyJev L0 | AnyJev L1 | |
|---|---|---|---|
| Labels required | none | none | 100–500 |
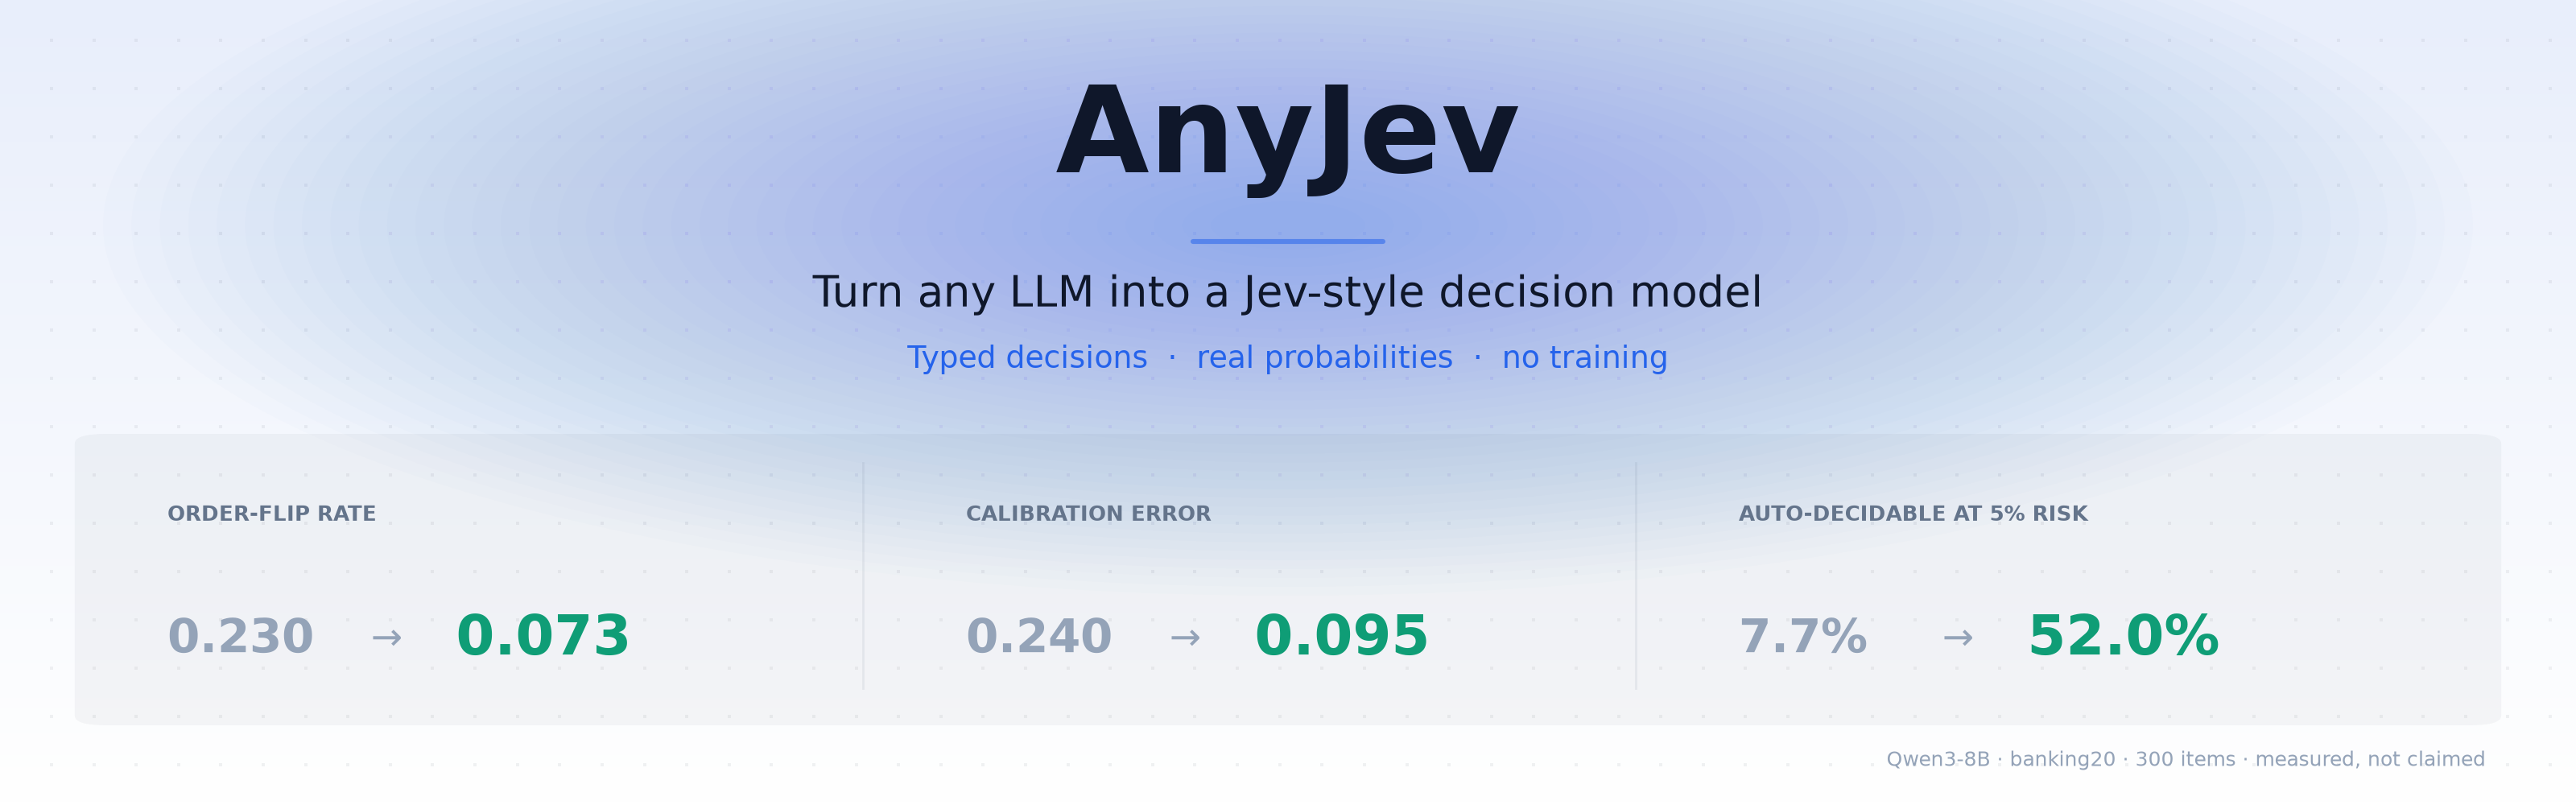
| Answer flips when options are reversed | 0.230 | 0.073 | 0.077 |
| Accuracy | 0.747 | 0.803 | 0.807 |
| Calibration error (ECE) | 0.240 | 0.184 | 0.095 |
| Auto-decidable at ≤5% error | 7.7% | 46.3% | 52.0% |
Qwen3-8B, BANKING77 20-way, 300 test items. Full table incl. every ablation: docs/results_bench.md
The last row is the point. Accuracy moves by 6 points, but the share of traffic you can safely automate goes from 7.7% to 52.0%, a 6.8× difference on this task (a point estimate at n=300; the interval is wide, see Limitations). With raw logits a "0.9" is not trustworthy enough to act on, so everything goes to a human. Once the probability means what it says, you can set a threshold.
🚀 Usage
📦 1. Install
pip install "anyjev[hf]"💬 2. Ask typed questions. L0 is on by default and needs no labels.
from anyjev import Decider, Question
from anyjev.backends.hf import HFBackend

d = Decider(HFBackend("Qwen/Qwen3-8B"))

route = Question.choice("Which team should handle this?", ["billing", "technical", "sales", "other"], name="route")
risky = Question.noul("Is this tool call destructive or irreversible?", name="risky")
done  = Question.score("How complete is the task?", bins=5, name="done")

r = d.decide({"conversation": [...], "tool_call": {...}}, [route, risky, done])
r["route"].distribution    # {"billing": 0.81, "technical": 0.07, ...}
r["risky"].p_true          # 0.12
r["done"].value            # 0.35
r.level                    # "L0"
🎯 3. Add labels when you have them. A temperature is L1; a closed-form head is L2, the accurate one.
d.calibrate(risky, states, labels)          # 100–500 labels → L1 (a temperature)
d.fit_head(route, states, labels)           # 100–300 labels → L2, one forward + a closed-form solve, seconds
d.save_artifacts("qwen3-8b.json")           # d.load_artifacts(...) next time; ~100 KB per head

r = d.decide(state, [route], level="auto")  # L2 where a head routes, else L1, else L0
r["route"].level                            # "L2"
🔁 4. Or let the loop feed it. d.observe(route, state, label) stores labels as they arrive and solves the head by itself at 30, re-solving at 60, 120, …
⚡ Serving. The transformers backend (anyjev.backends.hf) serves every level today; serving through vLLM / SGLang is on the roadmap, not in this release. For many states and one question, d.decide_batch(states, question).
🎬 Try it in one command. python -m demo.jev_mode --backend fake runs the whole thing on a synthetic model in under a second, no download. --lifecycle plays the deployment loop; drop --backend fake to run a real Qwen3 with the shipped heads (demo).
🧠 How it works
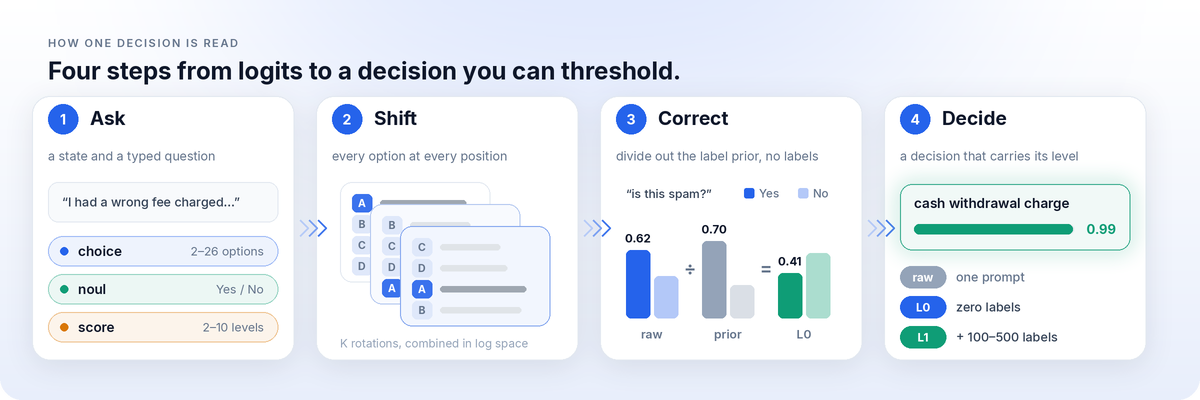
| Level | Needs | Does | Does not |
|---|---|---|---|
raw | nothing | restricted softmax over label tokens (what the clones do) | anything about bias or calibration |
L0 | nothing | averages position bias out over the K rotations and divides out the label prior | make the model's uncertainty calibrated |
L1 | 100–500 labels per question | temperature scaling on top of L0 | change the ranking |
L2 | 100–300 labels per question, a local model | a closed-form head (shrunk LDA / ridge) on the hidden state at ~⅔ depth, one prompt per state | transfer to another question or model |
Every Decision carries its level, so downstream code can refuse to act on the wrong one. L0 costs K prefills for a K-option choice (about 0.25 s per decision at batch 32 on one H100, K = 20); L2 costs less than one plain forward — one prompt, stopped early: 0.68× on Qwen3-8B.
🔁 A head that maintains itself
L2 is not a training run. Labels buy a head in one closed-form solve (seconds on a CPU, no gradients, the model's weights untouched). After that only the head's feature mean and scale move, re-estimated from unlabelled traffic — so the head follows its question across rewordings and option orders by itself, and new labels are needed only for a new question.
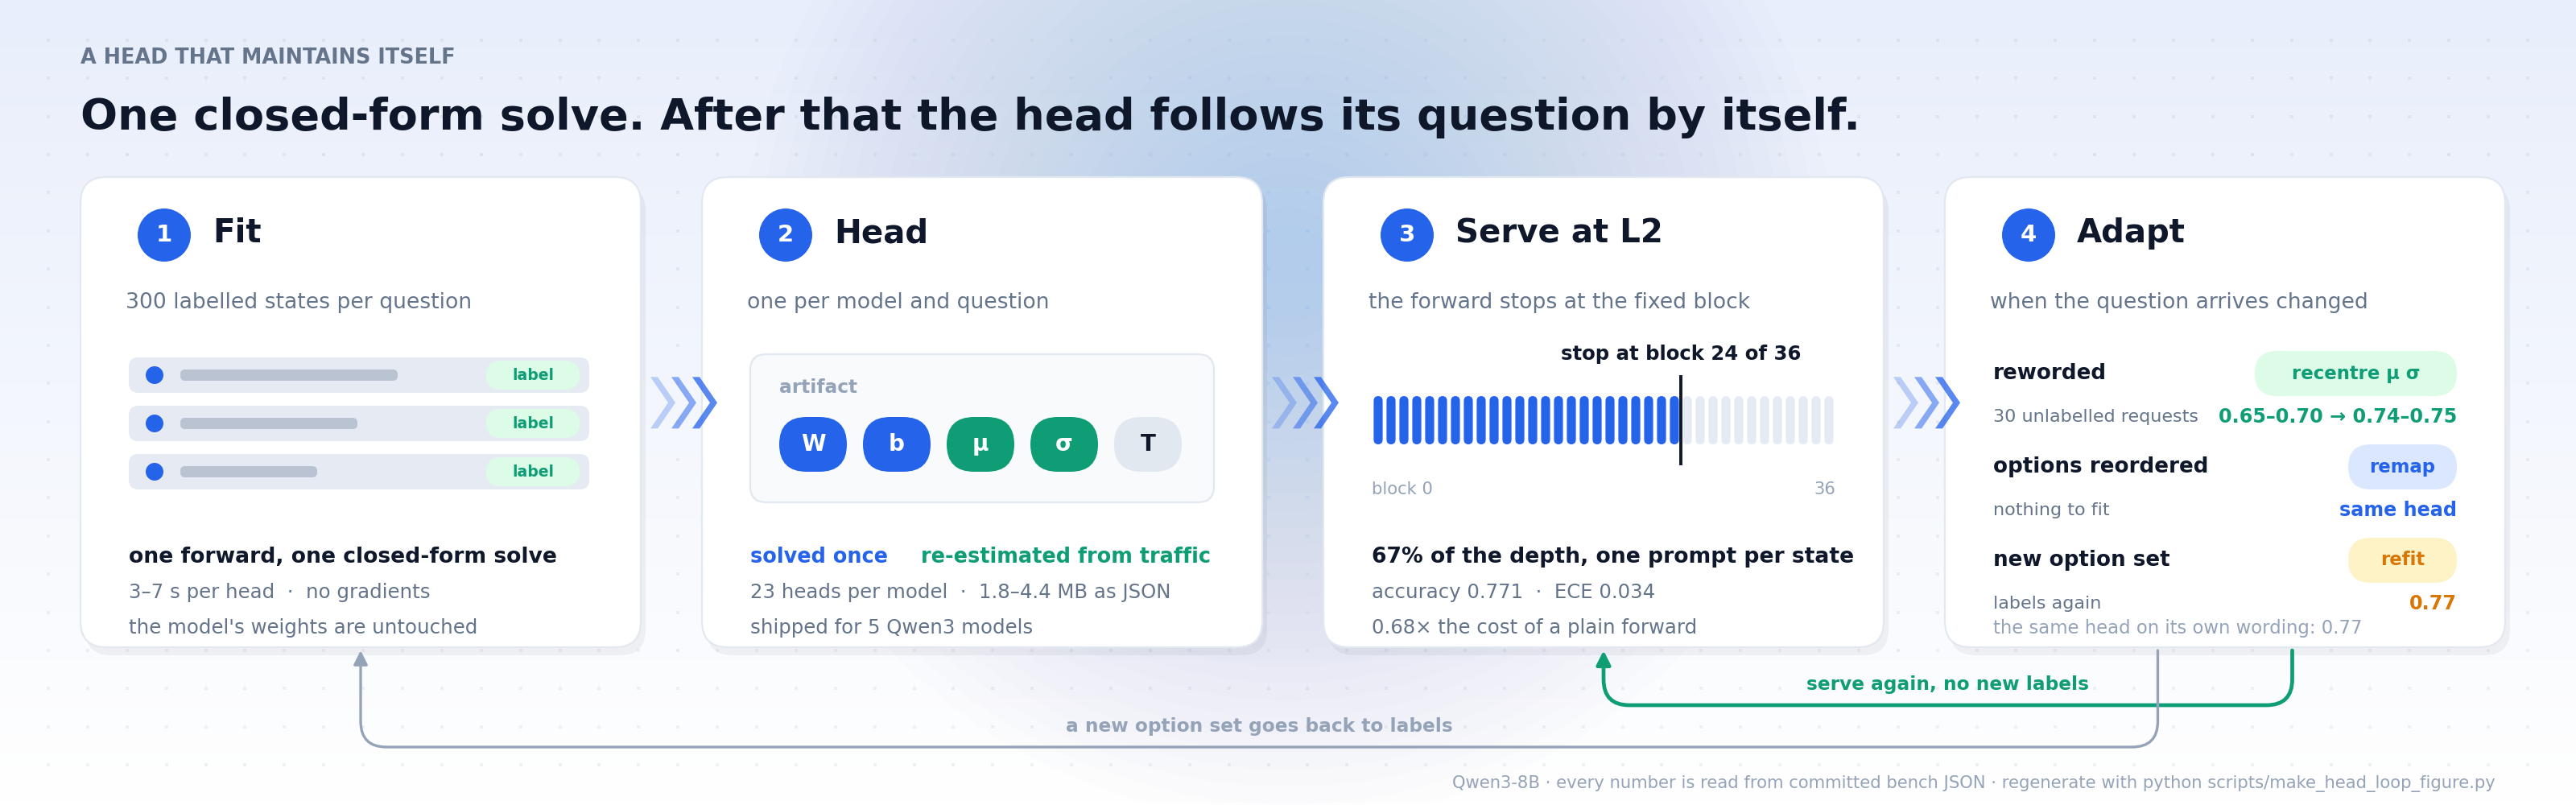
Reworded, the Qwen3-8B head as is drops from 0.77 to 0.65–0.70; 30 unlabelled requests of the new wording bring it back to 0.74–0.75, against 0.77 for a fully relabelled refit (JSON).
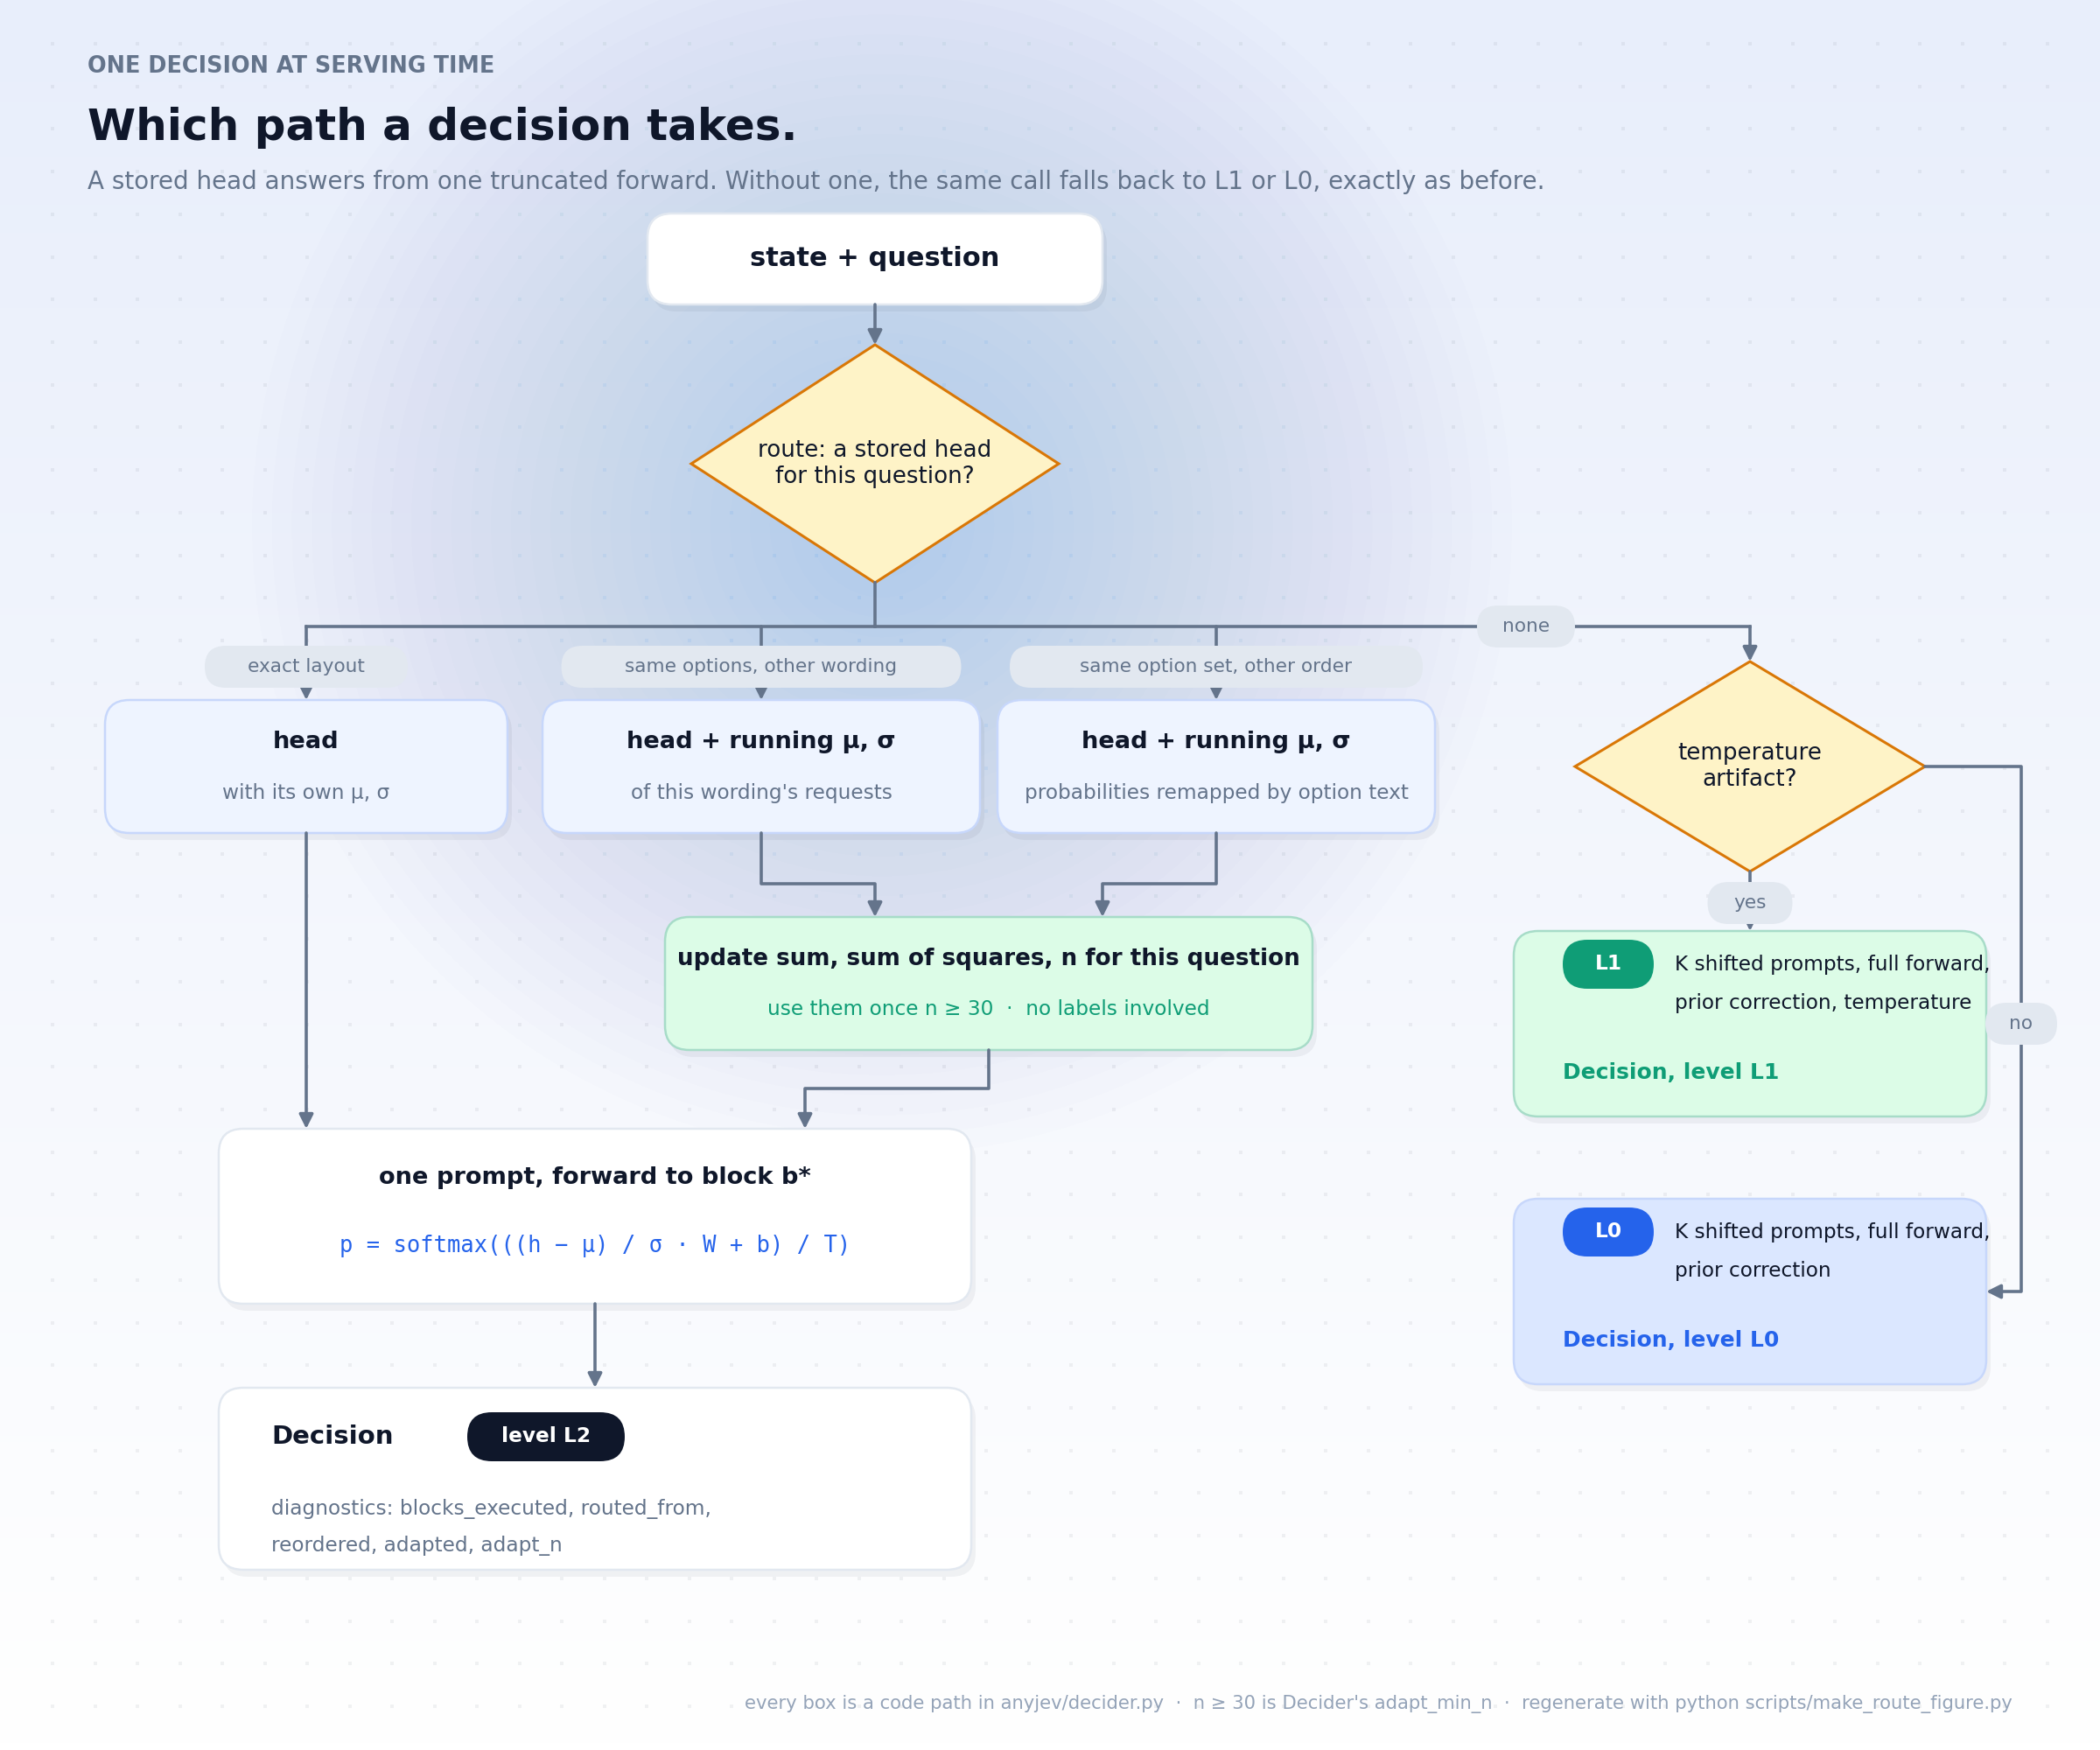
One decision at serving time. A stored head answers from one truncated forward. Without one, the same call falls back to L1 or L0 exactly as before; the routing is in docs/method_v3.md.
Deployment lifecycle: day 0 at L0, labels from the loop, heads in seconds
flowchart LR
    D0["day 0: define the questions,<br/>serve with level auto;<br/>every answer is L0, zero labels"] --> C["collect labels from the loop:<br/>review queue, outcomes, or the LLM<br/>being replaced; dec.observe fits at 30"]
    C --> F["fit_head per question;<br/>export_artifacts to one JSON per model"]
    F --> S["serve: L2 where a head routes,<br/>L1 or L0 elsewhere"]
    S --> W{"what changed?"}
    W -->|"wording or option order"| S
    W -->|"new question or option set"| C
    W -->|"new base model"| R["re-solve every head from<br/>the stored labelled states"]
    R --> S

    classDef shipped fill:#dcfce7,stroke:#0f9d76,color:#0f172a
    classDef decision fill:#fef3c7,stroke:#d97706,color:#0f172a
    class D0,C,F,S,R shipped
    class W decision
A shift in the states (not the wording) is invisible to the recentring, so a periodic spot check on a labelled slice stays in the recipe. Full method: docs/method_v3.md.
📊 Results
9 / 9🔁 Order flips cutevery model × task row, at L0, zero labels 3 models × 3 tasks → |
0.80🧩 Typed-decisions accuracyQwen3-32B and 30B-A3B at L2, 300 labels per question; Jev 0.727 as published, fine-tuned Laya 0.768 5 models → |
0.68×⚡ Cost of one decisionof a single plain forward, Qwen3-8B at L2: one prompt, stopped at block 24 of 36 latency → |
Jev mode, on LocalLLaMA/typed-decisions (20 questions, 300 labels each, 2,000 held-out decisions):
| model | L0, zero labels | L2 | block | cost vs one forward |
|---|---|---|---|---|
| Qwen3-1.7B | 0.494 | 0.730 | 18 / 28 | 0.70× |
| Qwen3-4B | 0.564 | 0.786 | 24 / 36 | 0.69× |
| Qwen3-8B | 0.647 | 0.771 | 24 / 36 | 0.68× |
| Qwen3-30B-A3B | 0.630 | 0.799 | 40 / 48 | not measured |
| Qwen3-32B | 0.700 | 0.798 | 52 / 64 | 0.84× |
Pooled ECE at L2 is 0.03–0.05. Jev 0.727 and fine-tuned Laya 0.768 on the same set, as published by their authors. Every cell: docs/results_exit.md
A 1.7B at 64% of its depth reaches the number Jev publishes; a 4B ties the fine-tuned 421M Laya. 100 labels already put the 8B head at 0.740 (20 labels: 0.654, 300: 0.772).
More: Jev mode in full · 2048 and Minesweeper · NanoJev maze · when L0 helps · small models · the research log, negative results included
Heads you can load today, and what a head costs
anyjev-heads/<model>.json ships 23 heads per model (the 20 typed-decisions questions and three bench tasks) for Qwen3-1.7B / 4B / 8B / 30B-A3B / 32B, built and validated through the same fit_head → decide_batch path a user runs (scripts/build_heads.py). A head is a [hidden, K] matrix plus a bias, a standardisation vector and a temperature: ~100 KB, solved in 2–8 s on the 1.7B–8B.
The big model's heads also distil into a small one without gradients: the 32B's heads labelling 1,200 generated cases per workflow lift the 1.7B from 0.730 to 0.760 (the 4B and 8B do not move). docs/jev_mode.md
All models and tasks in one figure
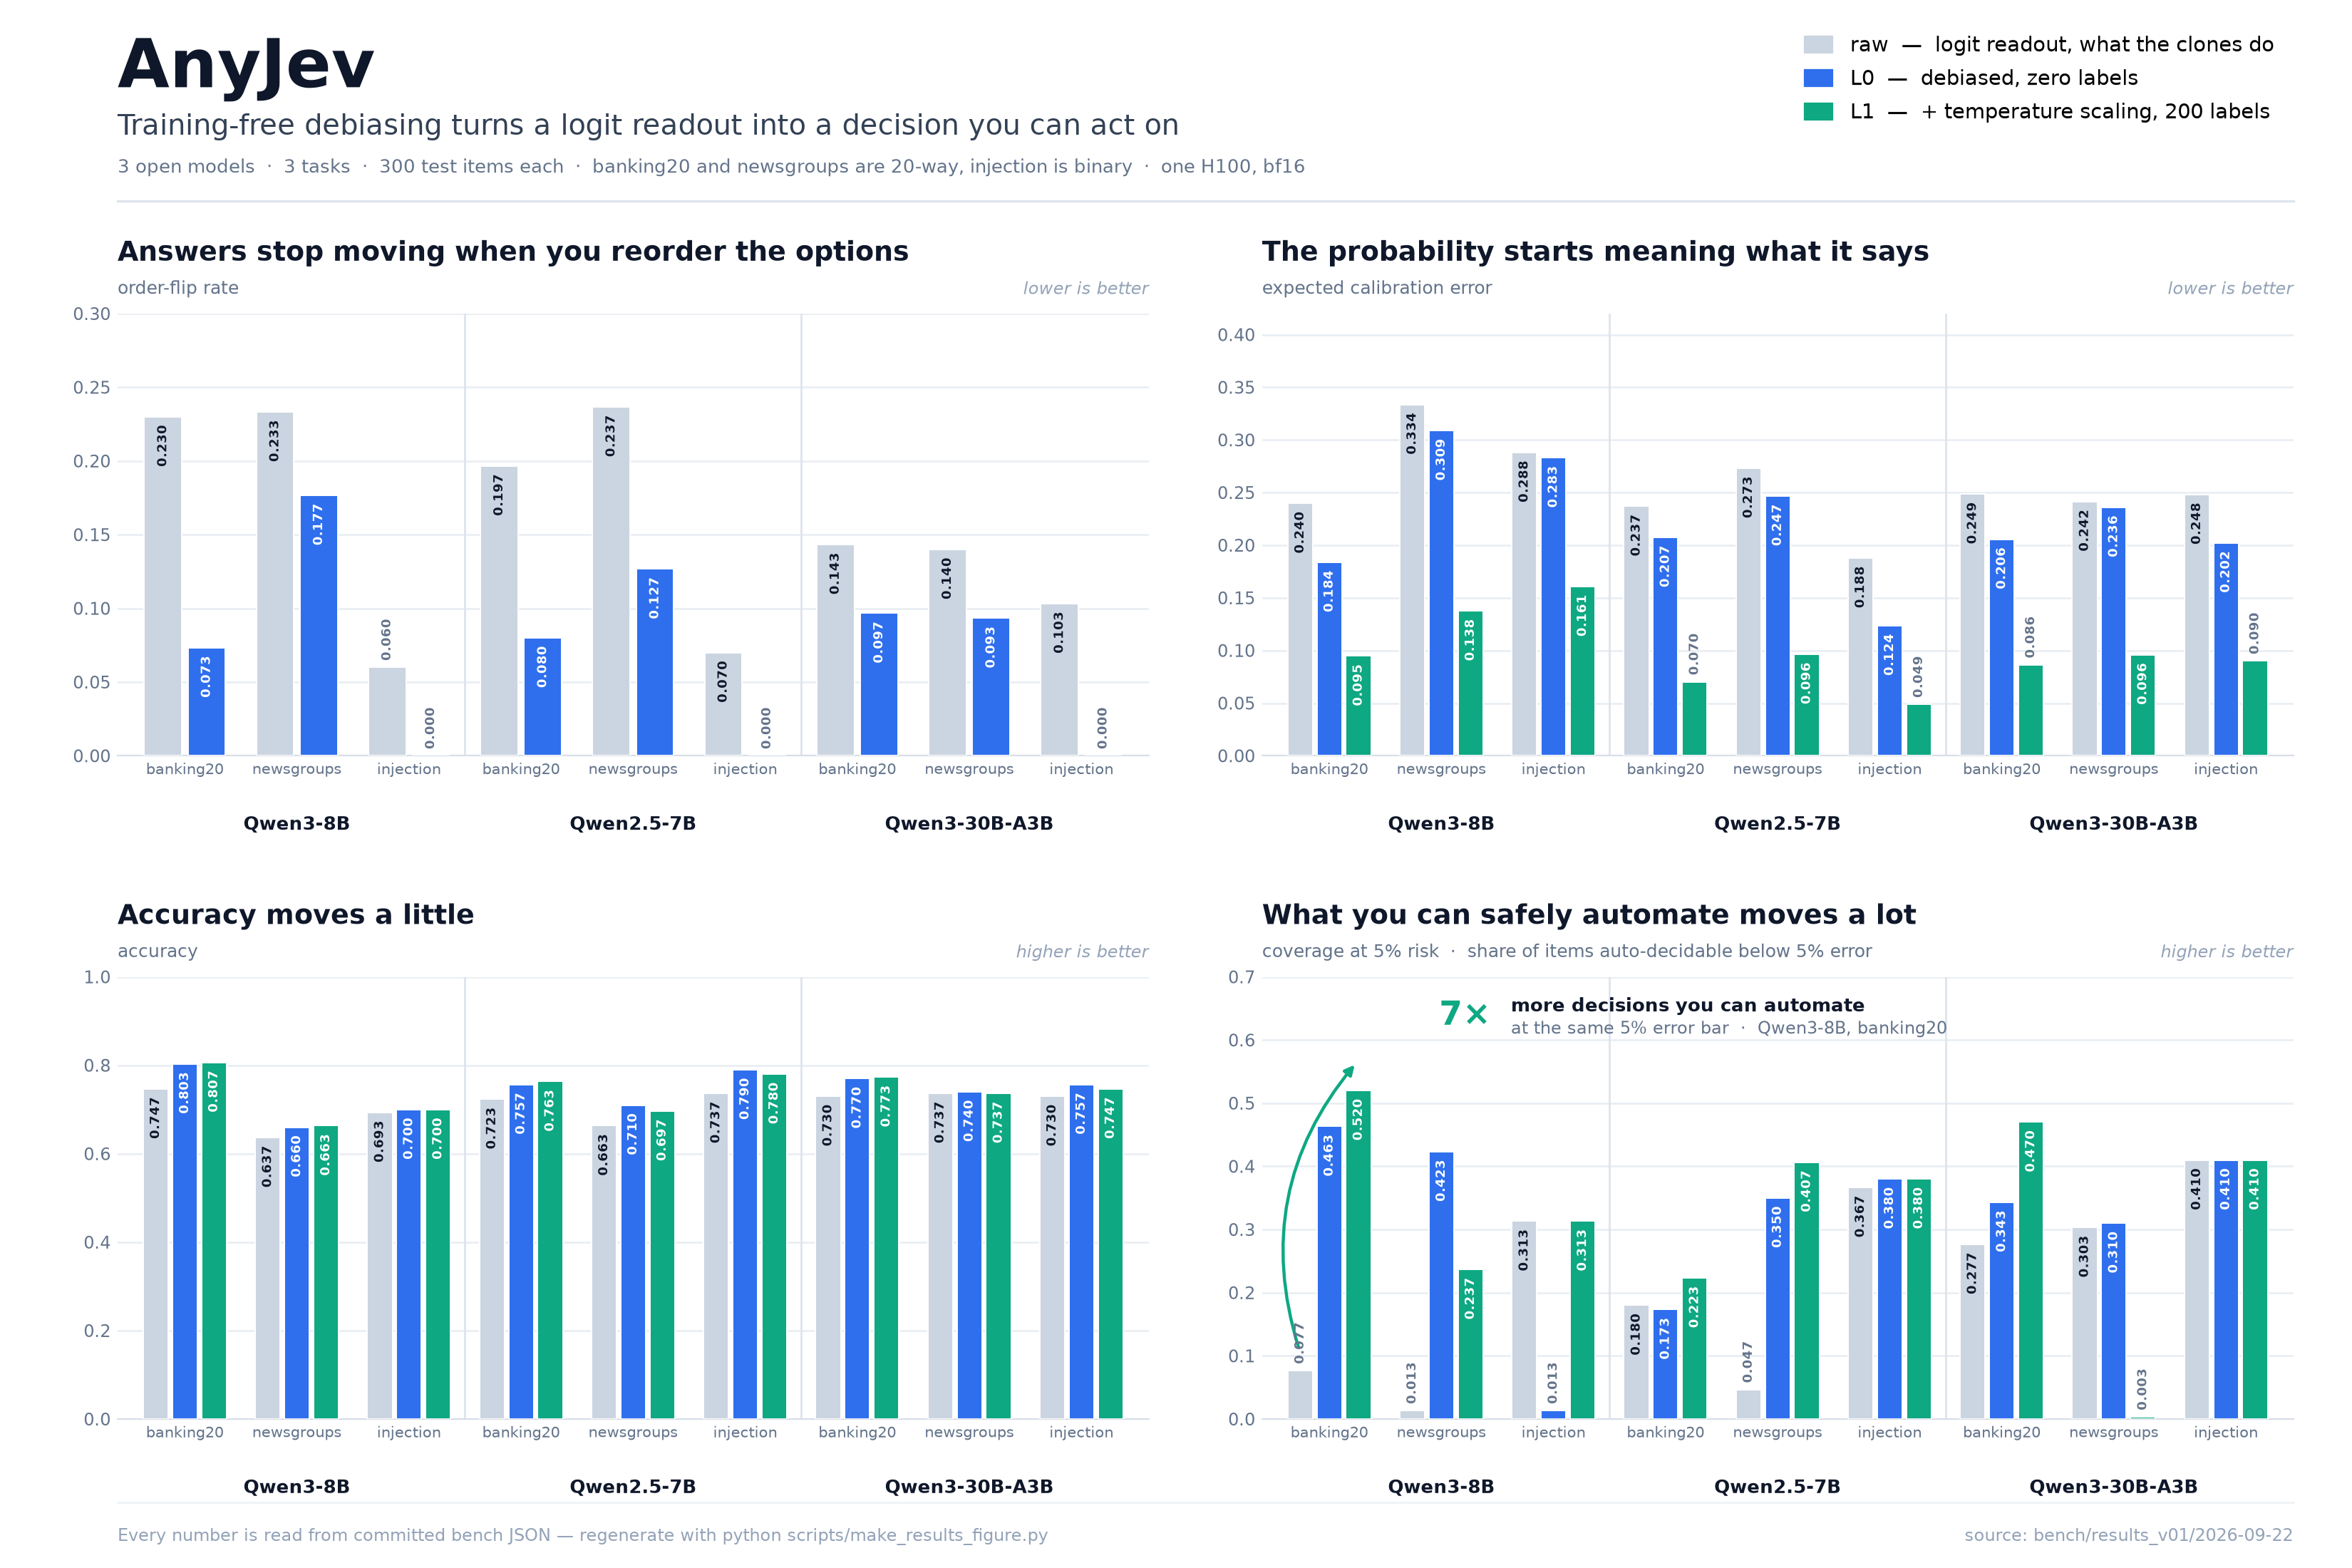
Every number is regenerated from committed JSON (bash scripts/regen_docs.sh); a second run from a clean checkout reproduced every zero-label number bit for bit. Not affiliated with TypeSafe AI or Jev; rows published by their authors were not rerun here.
🧭 Roadmap
-
choice,noulandscorefrom one prefill, nothing generated - L0 with zero labels; L1 artifacts as JSON; levels enforced with
require= - L2: a closed-form head per question, routing, label-free adaptation,
level="auto",observe - Shipped heads for five Qwen3 models; a packaged demo (
python -m demo.jev_mode) - L2 on served engines (vLLM / SGLang): the residual stream at one block, or a truncated checkpoint
- Agent-loop evaluation: the same decisions inside a real agent, against the LLM they replace
- Heads on the Hugging Face Hub, an interactive Space, a technical report
- More models (Llama, Gemma, Mistral, DeepSeek), span readout beyond 26 options, conformal abstention
Dated plan and help-wanted files: ROADMAP.md.
🔍 Limitations
- On typed-decisions, "accuracy" is agreement with a teacher LLM. The gold is the mean of three samples of one model; a fresh sample of that teacher agrees with it 0.735 of the time.
- L2 is per question and per model. Heads fit on other questions do not help a new one, and only Qwen3 heads ship. It also needs hidden states: transformers today; vLLM / SGLang are on the roadmap.
- Calibration cannot fix a model that cannot answer. On maze edges and Minesweeper no readout beats the trivial baseline.
- L0 is not a free win everywhere. The batch prior costs accuracy when one label dominates (when L0 helps).
Also: at most 26 options in the letter readout (a span readout is on the roadmap, not in the code); coverage at 5% risk is a high-variance estimate at n = 300; the headline tables are Qwen models; every decision here is scored in isolation, not inside an agent loop.
🤝 Contributing and citation
Backends and bench providers are one file each; several are help wanted (ROADMAP.md, CONTRIBUTING.md). Changes: CHANGELOG.md. Credits: CREDITS.md.
@software{anyjev2026,
  title  = {AnyJev: Turn any LLM into a Jev-style decision model},
  author = {Zhang, Jiamu and Yang, Tianze and Shi, Yucheng and Wu, Liang},
  year   = {2026},
  url    = {https://github.com/nokia-applied-research/AnyJev}
}
Apache-2.0, see LICENSE. Datasets keep their own licenses, see THIRD_PARTY.md.