$\tau$-Bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains




τ-bench 2.0
τ-bench 2.0 adds τ-i18n (also called τ-multi): the same customer-service tasks in six languages, in text and in full-duplex voice, plus post-hoc judges for how the agent speaks.
What's new:
- Six languages.
--languageselects a language pack: English, Spanish, Portuguese, Hindi, Chinese and Korean. Each pack localizes the tasks, the database and the caller personas for airline, retail and telecom. - Voice in every language. Full-duplex voice runs with realtime agents (OpenAI, Gemini, xAI and others) against a simulated caller who speaks the language.
- New
intakedomain (τ-Entity): capturing names, addresses and other entities exactly on an outbound call, over 200 tasks. See τ-Entity. banking_knowledgein voice. The retrieval domain from v1.0 now also runs as a custom voice run (--audio-native --benchmark none).- Judges.
tau2 judgesscores naturalness, speech fidelity, tool use and language-specific checks after a run. Judges do not change the task reward. - Released benchmarks. Frozen task sets with pinned data, so runs can be checked and compared.
The benchmarks
| Benchmark | Mode | Cells | Calls at 1 trial | Run with |
|---|---|---|---|---|
text-v1 | text | 6 languages × 3 domains | 900 | tau2 run --benchmark text |
voice-v2 (τ-i18n) | voice | 6 languages × 3 domains | 900 | tau2 run --audio-native |
voice-v1 | voice | English × 3 domains | 278 | tau2 run --audio-native --benchmark voice-v1 |
The domains are airline, retail and telecom. text-v1 and voice-v2 use the
same 50 frozen tasks per domain in every language. voice-v1 is the English-only
frame of the current English voice leaderboard (50 airline, 114 retail, 114
telecom tasks). See the glossary for cell, frame and
the other terms used in these docs.
Quickstart
git clone https://github.com/sierra-research/tau2-bench
cd tau2-bench
uv sync --extra voice          # drop --extra voice for text only
cp .env.example .env           # add OPENAI_API_KEY (and voice keys for voice)
Text benchmark:
tau2 run --benchmark text --agent-llm openai/gpt-5.5 \
  --agent-llm-args '{"reasoning_effort":"low"}' --save-to text-run --dry-run
Voice benchmark (create your own caller voices first; the shipped voice IDs are Sierra-internal):
python -m tau2.voice.scripts.setup_voices --language all   # prints TAU2_VOICE_ID_... lines for .env
tau2 run --audio-native --audio-native-model gpt-realtime-2 \
  --reasoning-effort minimal --save-to voice-run --dry-run
--dry-run prints the plan without making calls. Remove it to run, then:
tau2 view --file data/simulations/voice-run      # scores and calls
tau2 judges suite data/simulations/voice-run     # judges (needed for a voice-v2 submission)
Add --domain retail --num-tasks 2 for a 12-call smoke test. Full details:
Running the benchmark and the
submission guide.
Comparing with v1.0.1
2.0 English runs are not input-identical to v1.0.1, so 2.0 scores are not comparable with the 1.x leaderboard. The differences:
- English retail and telecom each use 50 reviewed task replacements.
- The prompts add a language clause and an entity-order rule (keep multi-part values such as addresses in the task's order).
- The text user simulator gets a persona block.
- Communication checks use a semantic LLM judge instead of substring matching.
- The NL-assertion judge is
gpt-5.4-mini-2026-03-17(wasgpt-4.1). - Name, ID and phone lookups fold case, accents and formatting.
- Voice defaults: user simulator
gpt-5.5(wasgpt-4.1), a 2400-second call limit (was 1200) and agent voicemarin(wasalloy).
For scores comparable to the 1.x leaderboard, use the
v1.0.1 release.
1.x and 2.0 results are shown on separate leaderboard tabs, and 1.x submissions
are still accepted. The full list is in the
CHANGELOG.
Previous release: τ³-bench (v1.0)
τ³-bench added voice full-duplex evaluation, the banking_knowledge domain and
75+ task fixes:
τ-Voice paper ·
τ-Knowledge paper ·
task fixes paper ·
v1.0.0 release notes.
v1.0.1 fixed banking_knowledge grading; results from before 1.0.1 are not
comparable on that domain (see the CHANGELOG).
Upgrading from τ²-bench? Installation uses
uvinstead ofpip install -e ., and Python>=3.12, <3.14is required.
Overview
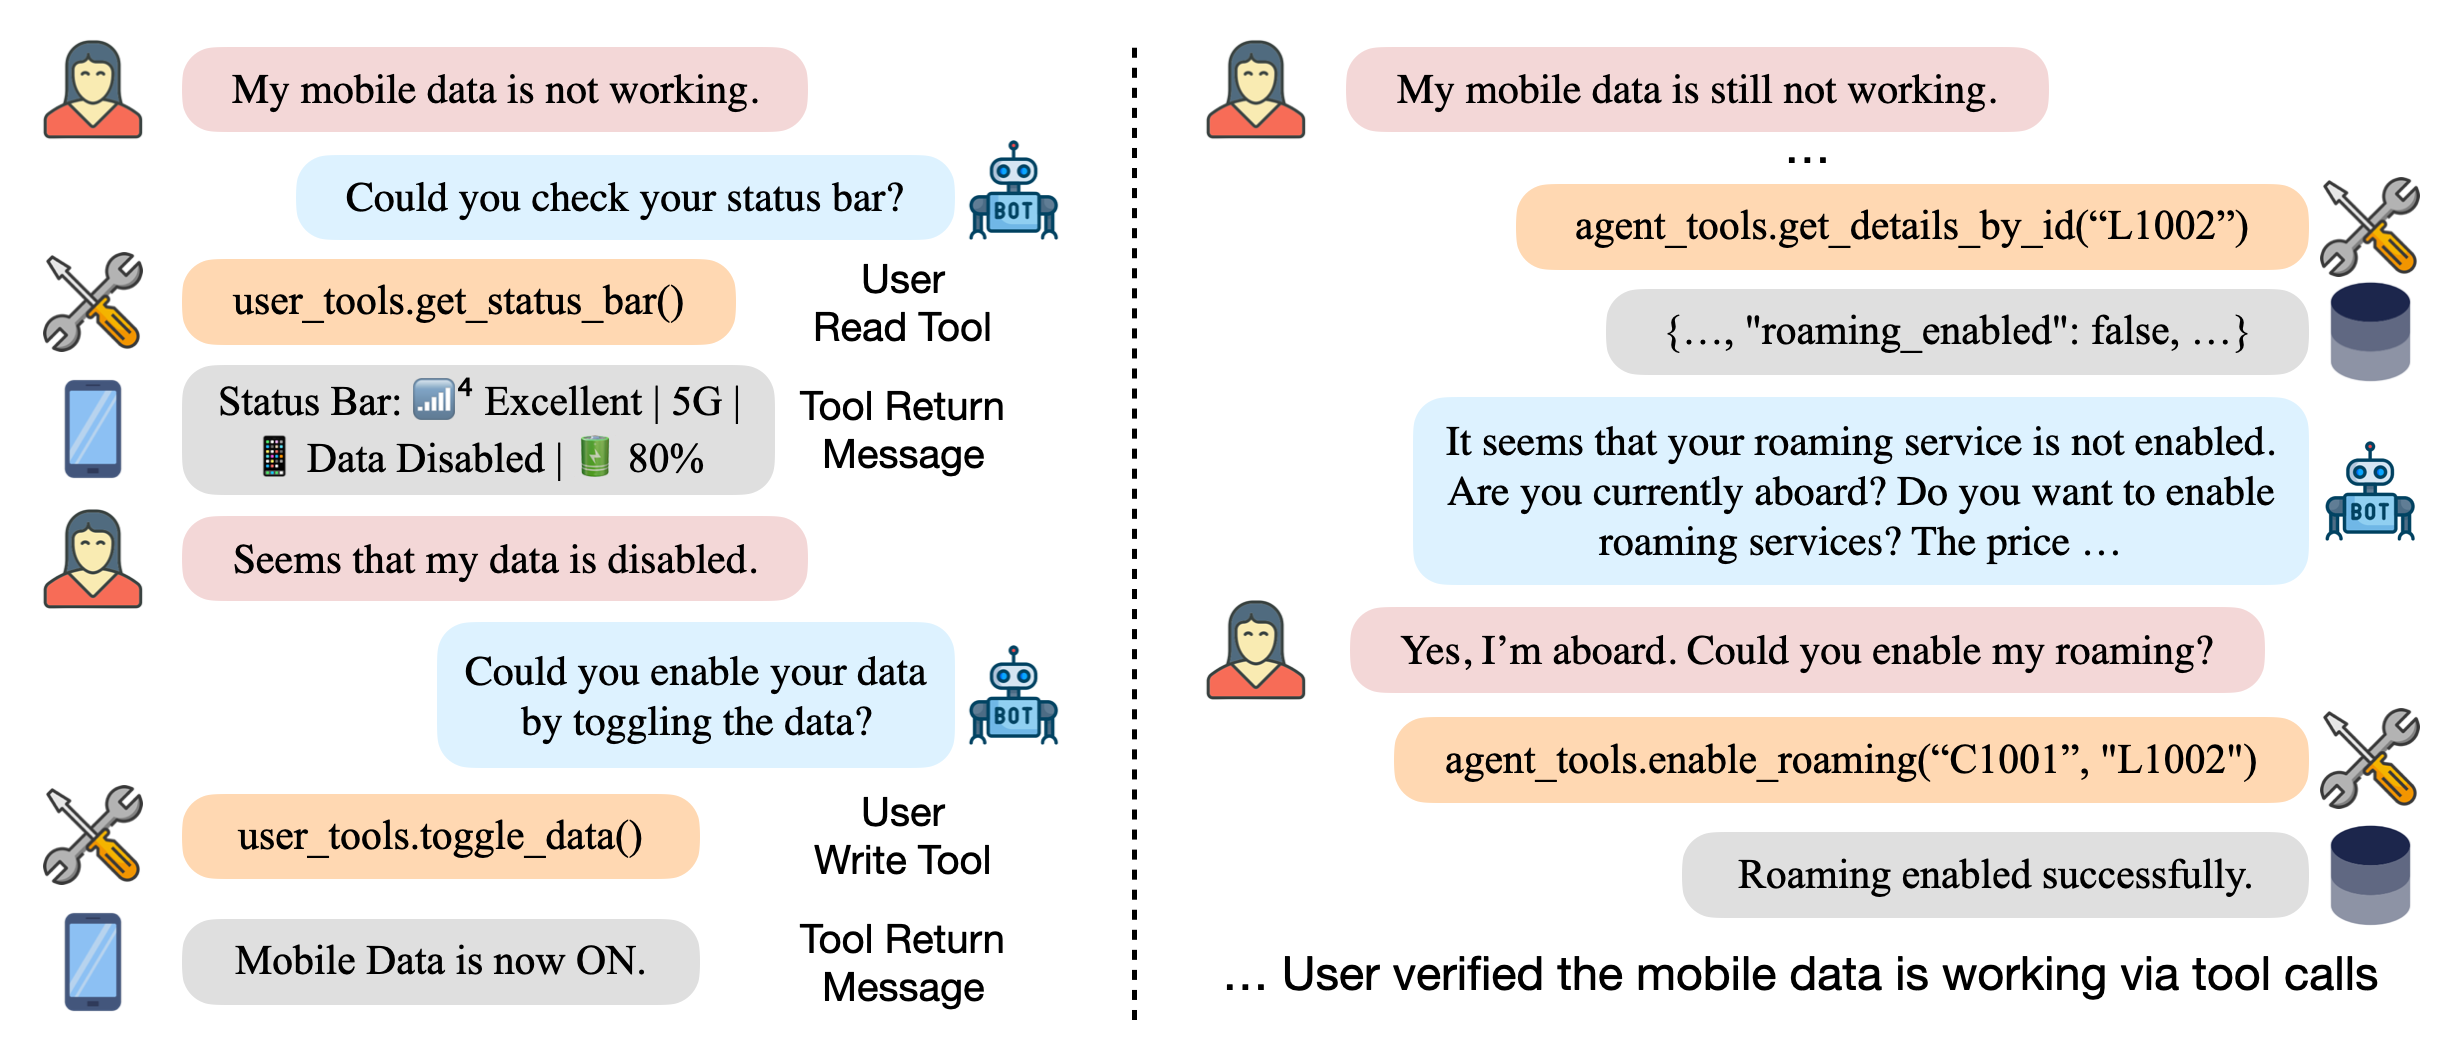
$\tau$-bench is a simulation framework for evaluating customer service agents across multiple domains. It supports text-based half-duplex (turn-based) evaluation and voice full-duplex (simultaneous) evaluation using real-time audio APIs.
Each domain specifies:
- A policy that the agent must follow
- A set of tools that the agent can use
- A set of tasks to evaluate the agent's performance
- Optionally: a set of user tools for the user simulator
Available domains: mock · airline · retail · telecom · banking_knowledge · intake
τ-Entity uses --domain intake to evaluate exact entity capture in outbound calls over 200 tasks. Agent-directed elicitation is the default; --elicitation-strategy scaffolded selects the scaffolded ablation.
| Mode | Description |
|---|---|
| Text (half-duplex) | Turn-based chat with tool use |
| Voice (full-duplex) | End-to-end audio via realtime providers (OpenAI, Gemini, xAI) |
[!NOTE] τ-i18n was previously called τ-Multilingual, and τ-Entity was previously called τ-Elicitation. Only the names changed: the old names remain in technical identifiers, provenance and paper titles, and the τ-Entity domain is still
intake.
Installation and a first custom run
1. Install
git clone https://github.com/sierra-research/tau2-bench
cd tau2-bench
uv sync                        # core, including scaffolded intake text runs
Optional extras (install what you need):
uv sync --extra voice          # + voice/audio-native features
uv sync --extra knowledge      # + banking_knowledge domain (retrieval pipeline)
uv sync --extra gym            # + gymnasium RL interface
uv sync --extra dev            # + pytest, ruff, pre-commit (required for contributing)
uv sync --all-extras           # everything
This requires uv. Voice features also need system dependencies (brew install portaudio ffmpeg on macOS). See the full installation guide for details.
2. Set up API keys
cp .env.example .env
# Edit .env with your API keys (uses LiteLLM — any supported provider works)
3. Run an evaluation
tau2 run --domain airline --agent-llm gpt-4.1 --user-llm gpt-4.1 \
  --num-trials 1 --num-tasks 5
Results are saved to data/simulations/. Use tau2 view to browse them.
Tip: Run
tau2 introfor an overview of available domains, commands, and examples.
Documentation
Getting Started
| Document | Description |
|---|---|
| Getting Started | Installation, API keys, first run, output structure, configuration |
| Running the benchmark | Text and voice benchmark commands, defaults, results layout, resume, scoring and judges |
| Submission guide | Submitting text-v1, voice-v2, voice-v1 and 1.x results |
| Glossary | Pack, cell, frame, binding revision, pin, trial, judge, manifest |
| CLI Reference | Every tau2 command's --help, generated from the CLI |
Core Concepts
| Document | Description |
|---|---|
| Agent Developer Guide | Build and evaluate your own agent |
| Domains | Domain structure, data format, and available domains |
| Orchestrator & Communication Modes | Half-duplex and full-duplex orchestration |
| Task Schema & Evaluation | What evaluation_criteria.actions means, how reward_basis gates the reward, and how to inspect action correctness |
Languages and judges
| Document | Description |
|---|---|
| Language packs | What a language pack contains and how runs resolve it |
| Adding a language | The tau2 factory authoring workflow |
| Judge validation | Production judges, and authoring and validating new ones |
| τ-Entity | The intake domain and its strategies |
Knowledge Retrieval
| Document | Description |
|---|---|
| Knowledge Retrieval | Retrieval pipeline configs, embeddings, RAG, and sandbox setup for the banking_knowledge domain |
Voice & Audio
| Document | Description |
|---|---|
| Voice (Full-Duplex) | Providers, speech complexity, CLI options, and output structure for voice evaluation |
| Audio Native Architecture | Internal architecture for adding or modifying realtime provider adapters |
RL & Training
| Document | Description |
|---|---|
| Gym Interface | Gymnasium-compatible environment, play mode, train/test splits |
Leaderboard & Experiments
| Document | Description |
|---|---|
| Submission guide | How to submit results to taubench.com |
| Experiments | Experimental features and research code |
Project
| Document | Description |
|---|---|
| Contributing | How to contribute to τ-bench |
| Changelog | Version history and release notes |
Contributing
We welcome contributions! Whether you're fixing bugs, adding features, creating domains, or contributing research code, see our Contributing Guide for guidelines.
Citation
If you use a specific component of $\tau^3$-bench, please cite the corresponding paper below.
Knowledge Domain (banking_knowledge)
@article{shi2026tau,
  title={$\tau$-Knowledge: Evaluating Conversational Agents over Unstructured Knowledge},
  author={Shi, Quan and Zytek, Alexandra and Razavi, Pedram and Narasimhan, Karthik and Barres, Victor},
  journal={arXiv preprint arXiv:2603.04370},
  year={2026}
}
Voice Full-Duplex Benchmark
@misc{ray2026tauvoicebenchmarkingfullduplexvoice,
      title={$\tau$-Voice: Benchmarking Full-Duplex Voice Agents on Real-World Domains},
      author={Soham Ray and Keshav Dhandhania and Victor Barres and Karthik Narasimhan},
      year={2026},
      eprint={2603.13686},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2603.13686},
}
Multilingual Voice Benchmark (τ-i18n)
@misc{ray2026taumultilingual,
      title={$\tau$-Multilingual: Benchmarking Voice Agents Across Languages},
      author={Soham Ray and Edgard dos Santos Paiva and Ruben Valenzuela and Karthik Narasimhan and Keshav Dhandhania and Victor Barres},
      year={2026},
      eprint={2609.35820},
      archivePrefix={arXiv},
      url={https://arxiv.org/abs/2609.35820},
}
Entity Capture Benchmark (τ-Entity, intake)
@misc{ray2026tauelicitation,
      title={$\tau$-Elicitation: Benchmarking Multi-Turn Entity Extraction in Voice Agents},
      author={Soham Ray and Victor Barres},
      year={2026},
      eprint={2609.13602},
      archivePrefix={arXiv},
      url={https://arxiv.org/abs/2609.13602},
}
Core $\tau$-Bench
@misc{barres2025tau2,
      title={$\tau^2$-Bench: Evaluating Conversational Agents in a Dual-Control Environment},
      author={Victor Barres and Honghua Dong and Soham Ray and Xujie Si and Karthik Narasimhan},
      year={2025},
      eprint={2506.07982},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.07982},
}

@misc{yao2024tau,
      title={$\tau$-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains},
      author={Shunyu Yao and Noah Shinn and Pedram Razavi and Karthik Narasimhan},
      year={2024},
      eprint={2406.12045},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2406.12045},
}
Task Fixes
@inproceedings{cuadron2026saber,
      title={{SABER}: Small Actions, Big Errors {\textemdash} Safeguarding Mutating Steps in {LLM} Agents},
      author={Alejandro Cuadron and Pengfei Yu and Yang Liu and Arpit Gupta},
      booktitle={ICLR 2026 Workshop on Memory for LLM-Based Agentic Systems},
      year={2026},
      url={https://openreview.net/forum?id=En2z9dckgP},
}