⚡ vLLM 2080 Ti Definitive Edition
Language: English | 简体中文
The definitive vLLM inference runtime for dual RTX 2080 Ti and other SM75 GPUs, including Tesla T10/T40/T4, TITAN RTX, and Quadro RTX 6000/8000.
This hardware-focused fork preserves the SM75-specific source changes, launcher
profiles, and validation evidence needed to reproduce these Turing inference
stacks. It is
based on upstream vLLM; retain both the upstream license and attribution to
github.com/weicj when redistributing a derivative.
For usage feedback, feature requests, and community discussion, join the Discord community.
Current 0.2.x baseline: v0.2.1
Upstream baseline: b23433088b (v0.29.1rc0-33)
Branch: vllm-2080ti-definitive-0.2.x
Release reference: v0.2.1
Release history: CHANGELOG.md
💡 Why RTX 2080 Ti For LLM Inference?
The project is built around a practical cost/performance premise: two 22 GB RTX 2080 Ti cards joined by NVLink provide 44 GB of VRAM, substantial memory bandwidth, and 136 Turing SMs. With an SM75-aware vLLM route, that is enough for serious local 27B and 35B-class serving rather than only small-model use.
| Metric | 2x RTX 2080 Ti 22 GB + NVLink | RTX 3090 Ti 24 GB baseline | Ratio |
|---|---|---|---|
| Dedicated FP32 datapaths | 8,704 | 5,376 | 1.62x |
| SM count | 136 | 84 | 1.62x |
| Tensor Cores | 1,088 | 336 | 3.24x |
| Dense FP16 matrix throughput | 228 TFLOPS | 160 TFLOPS | 1.43x |
| Total memory bandwidth | 1,232 GB/s | 1,008 GB/s | 1.22x |
| Total VRAM | 44 GB | 24 GB | 1.83x |
The fork turns those hardware properties into a usable serving stack through Marlin, FlashInfer/FlashQLA, TurboQuant/INT8 KV, MTP/DFlash2, and CUDA Graph support.
The second supported hardware family is four 16 GiB Tesla T10 GPUs over PCIe. Those profiles target TP=4 Qwen 27B serving. The 18-route library has been audited for startup and reference workloads; routes with a noted image-semantic failure remain explicitly marked as candidates.
🧩 Support Status
The current target environment is Ubuntu 26.04 or later, Linux kernel 7 or later, GCC/G++ 15, CUDA 13.0, and PyTorch 2.13. For CUDA 12.8, PyTorch 2.11, older kernels, or GCC 12/13/14, refer to the 0.1.x line, which is no longer actively maintained.
Supported model routes and their measurements are listed in the corresponding hardware profile guides.
The launcher supports TP, PP, and mixed TP/PP inference; the primary layouts are two RTX 2080 Ti GPUs with TP=2 and four Tesla T10 GPUs with TP=4.
🧪 Tested Model Checkpoints
Current tested model and weight routes:
| Model route | Weight route | Model card | Recommended use | Profile path |
|---|---|---|---|---|
| Qwen3.8 27B | FP8 | Qwen/Qwen3.8-27B-FP8 | High-precision single-request inference | qwen27b/w8a16 |
| Qwen3.8 27B | NVFP4 | unsloth/Qwen3.8-27B-NVFP4 | Long-context concurrent inference | qwen27b/w4a16 |
| Qwen3.x 35B | FP8 | Qwen/Qwen3.6-35B-A3B-FP8 | Fast personal inference | qwen35b/w8a16 |
⚡ Highlights
| Hardware | Weight | Context / KV | 4K Prompt decode | 32K Prompt decode |
|---|---|---|---|---|
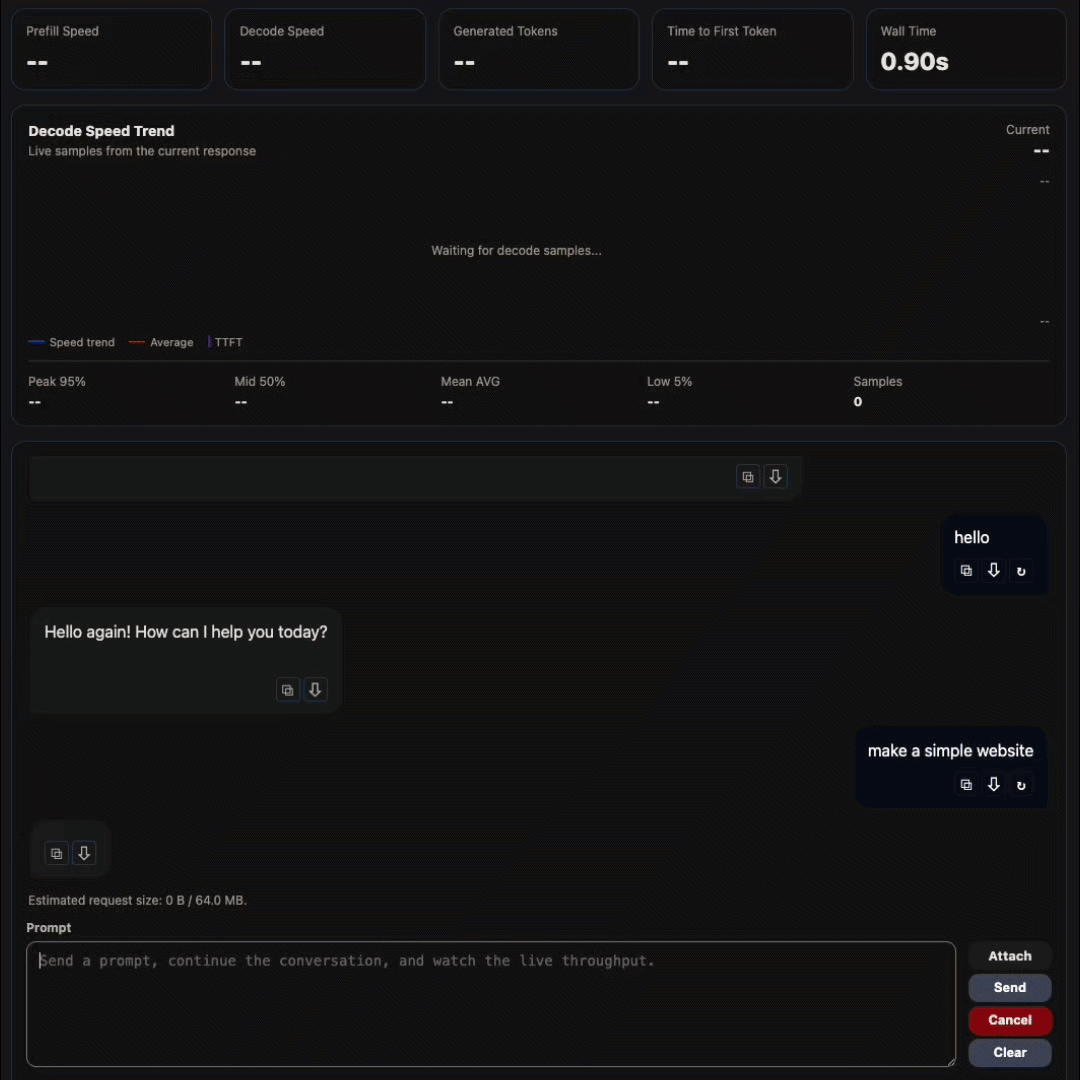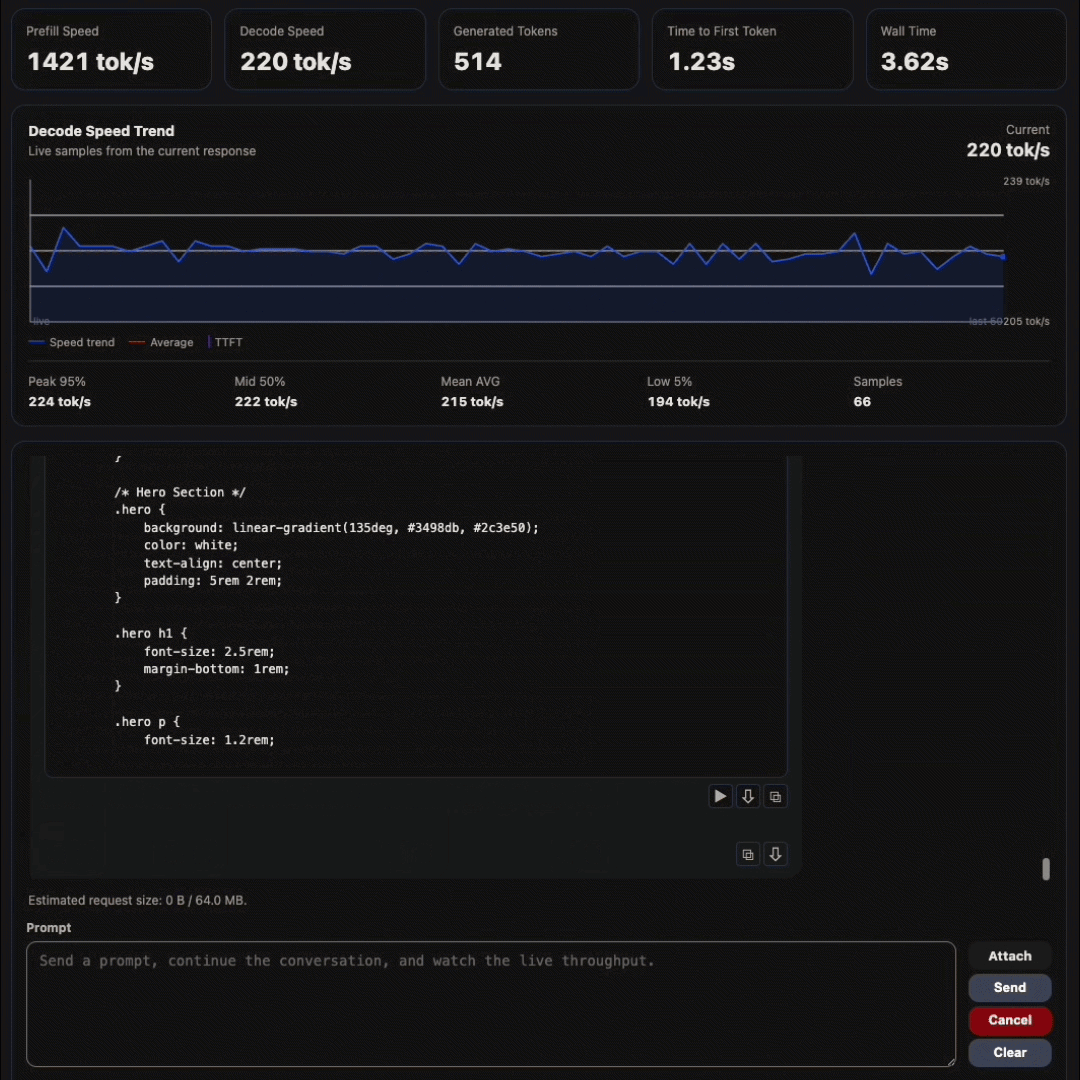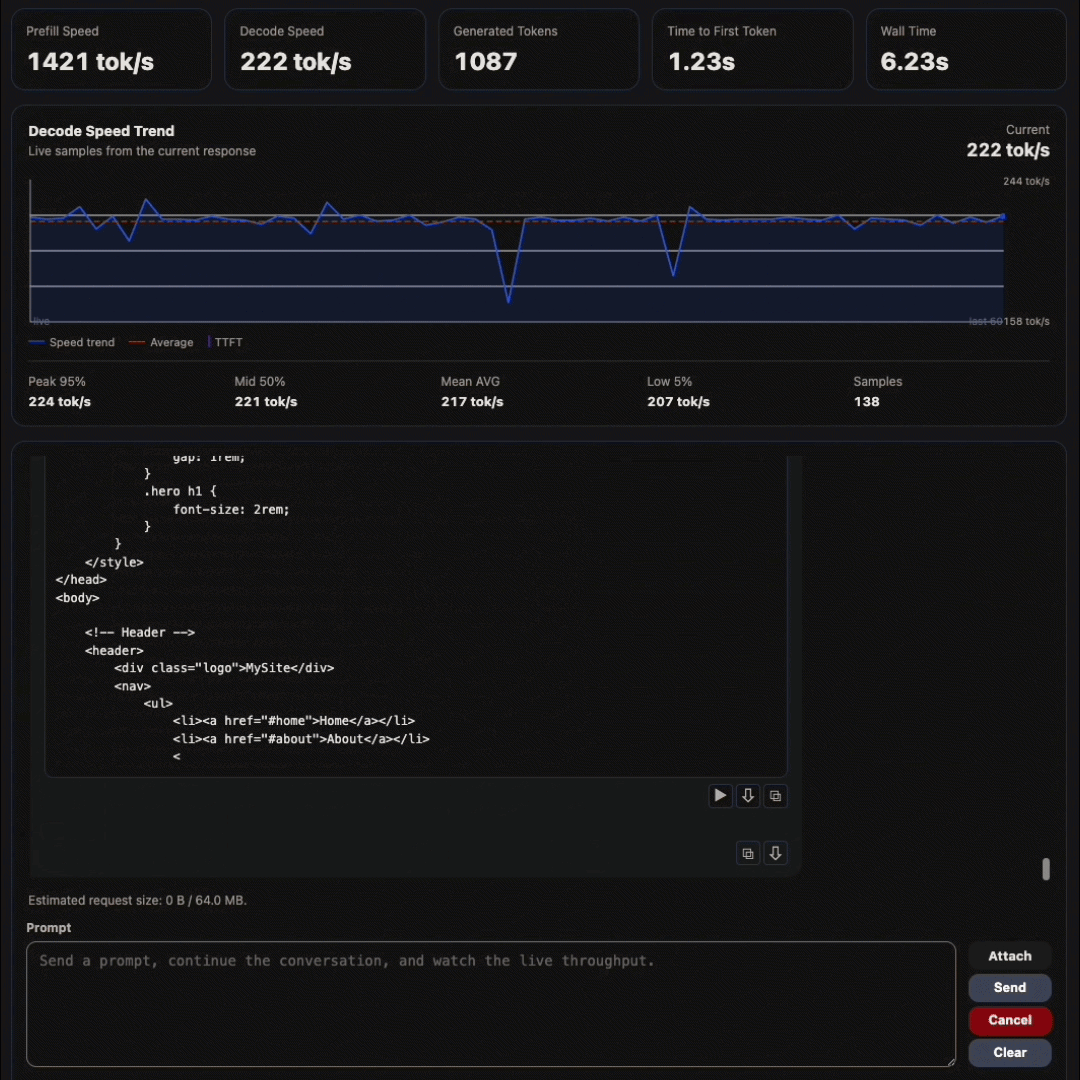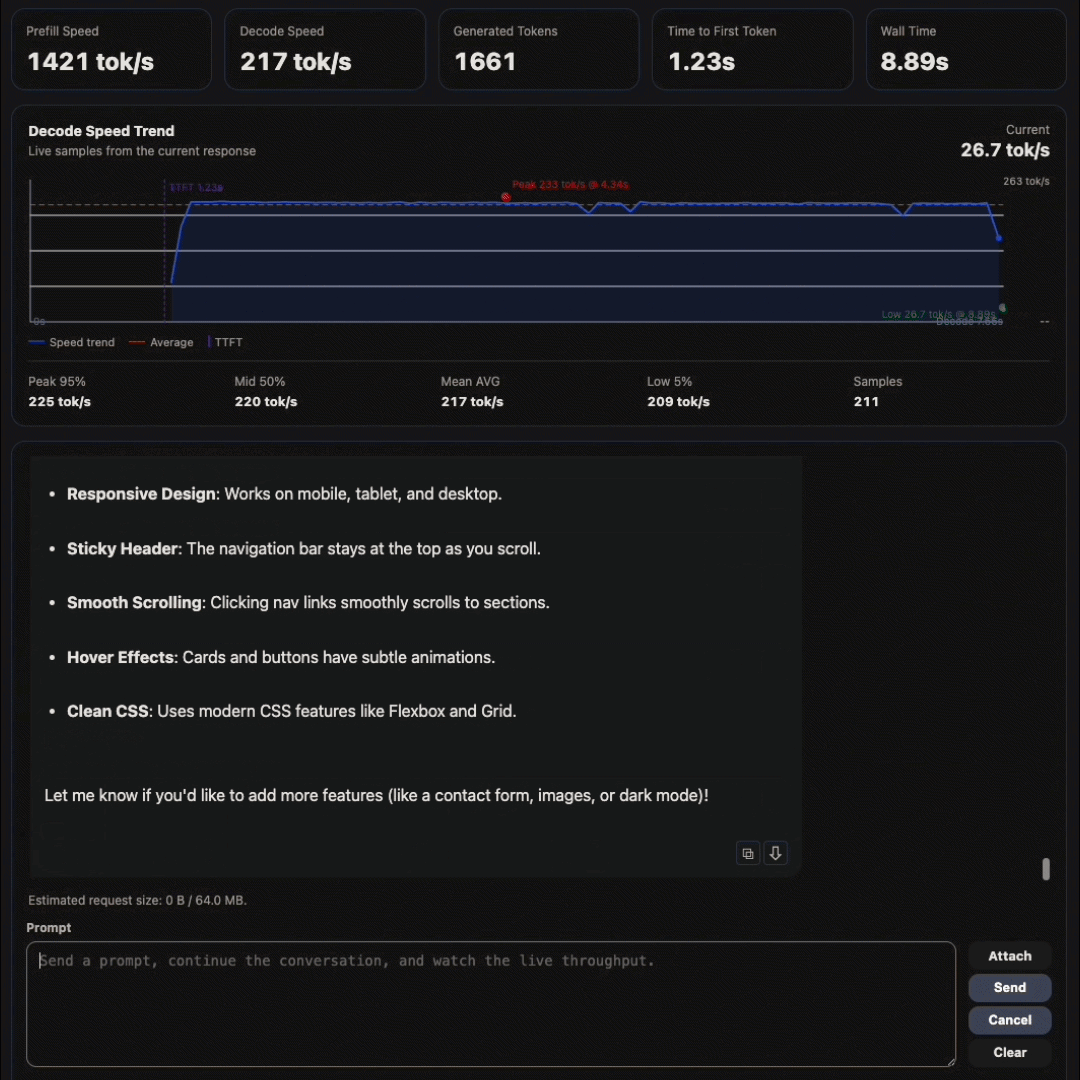
| 2x RTX 2080 Ti | Qwen3.8 27B NVFP4 | 256K / FP8 KV | 220.84 tok/s | 209.35 tok/s |
| 4x Tesla T10 | Qwen3.8 27B FP8 | 256K / FP16 KV | 191.89 tok/s | 189.38 tok/s |
Both rows are single-request tests using DFlash2 (default K=7) and synthetic text inputs with high speculative-hit rates. Real-task throughput depends on draft acceptance and may not reach these figures.
🚀 Build And Launch
- Build a new checkout:
git clone https://github.com/weicj/vLLM-2080Ti-Definitive.git
cd vLLM-2080Ti-Definitive
./build.sh- Update an existing checkout to the latest GitHub Release:
./update.shThe update helper preserves local environments, dependency caches, logs,
results, and profiles/local. It compares VERSION with the latest release,
downloads the matching source archive, and offers to run build.sh after the
refresh.
- Start and manage the service:
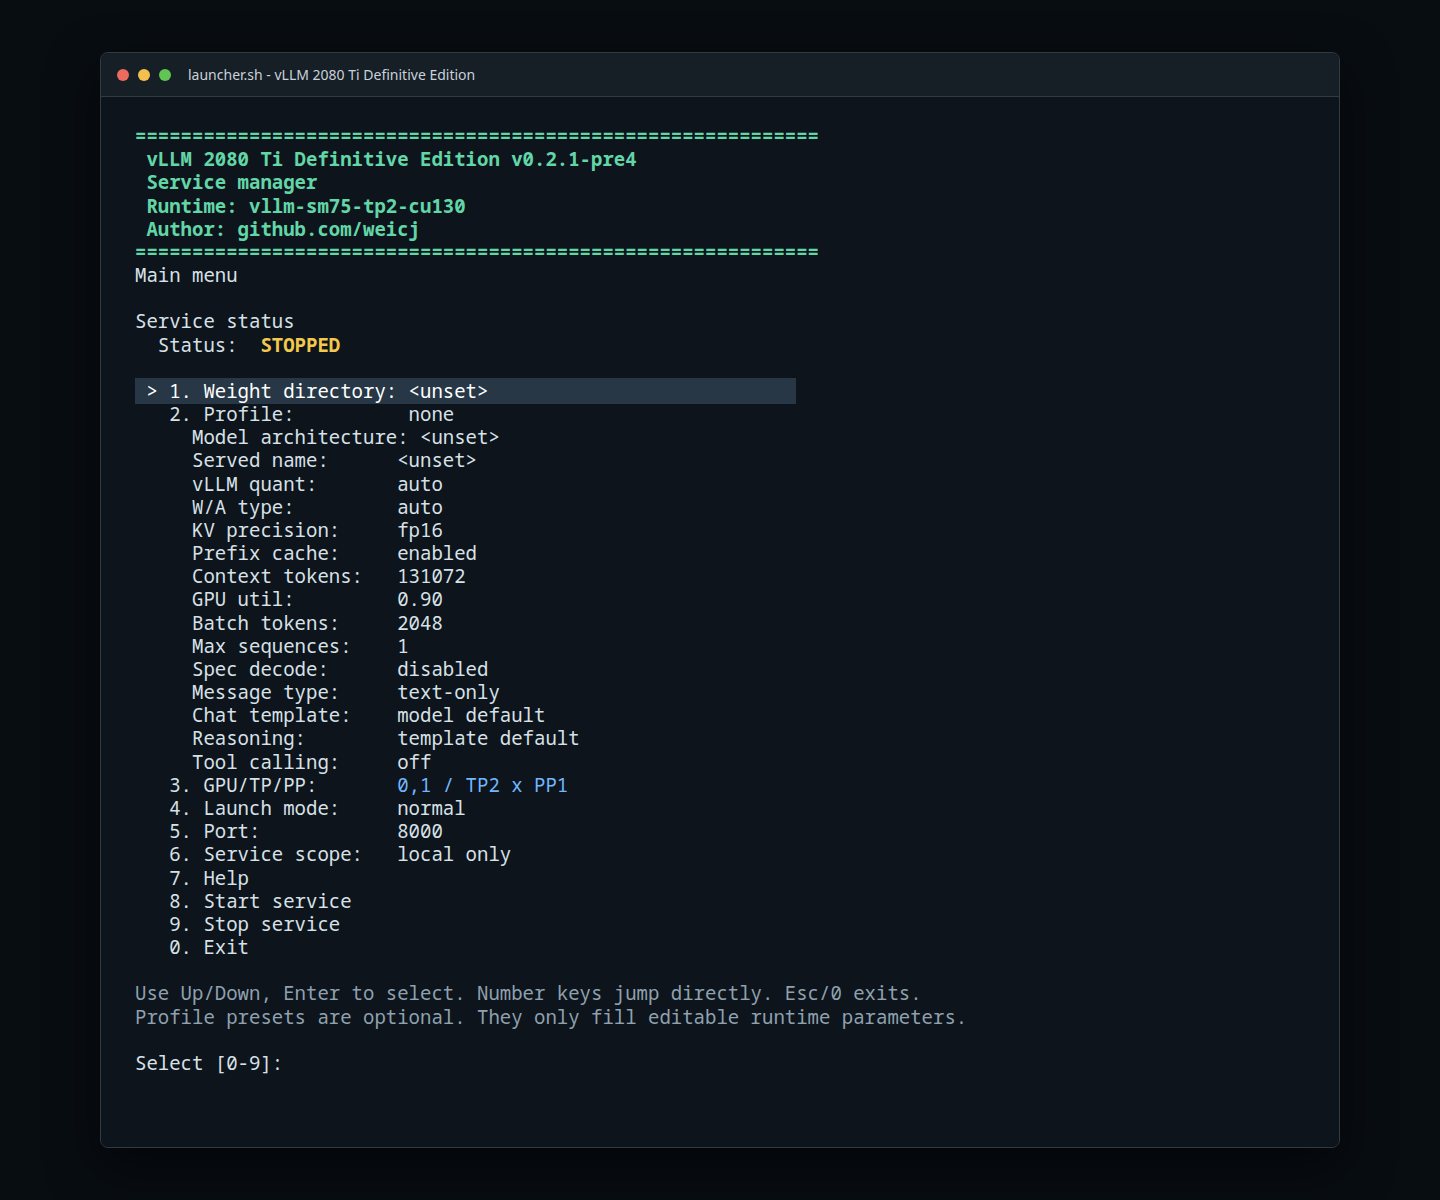
./launcher.shThe interactive launcher selects target and DFlash draft checkpoints, applies a profile, configures GPU and TP/PP topology, chooses the launch mode and network settings, starts the service with health and smoke checks, and stops a running service.
For automated deployment, pass the configuration non-interactively:
MODEL_DIR=/path/to/checkpoint \
PROFILE=2x2080Ti/qwen27b/w8a16/mtp4-fp8kv-1x256k-text-only.env \
MODE=fast GPU_DEVICES=1,5 TP_SIZE=2 \
NON_INTERACTIVE=1 ./launcher.sh
Use ./launcher.sh --print-config to preview a route. See the
non-interactive launch guide for automation.
🧭 Profiles
Read the Profile Guide for the layout and route fields. Detailed profiles and reference performance are listed for 2x2080Ti and 4xT10.
Profiles use the flat layout profiles/<hardware>/<model>/<weight>/<route>.env.
The launcher selects the startup mode and defaults to MODE=fast; the mode can
also be set explicitly by the launcher or profile.
Available modes:
normal: stable daily deployment mode.fast: higher-performance mode for validated routes; this is the default mode.aggressive: highest-performance mode with increased quality risk.safe: conservative fallback for troubleshooting and compatibility.
The profile selects only route parameters. The launcher owns GPU selection, port, target and draft model paths, chat template, and reasoning defaults.
🛠️ Hardware Target
- Two RTX 2080 Ti 22 GB GPUs connected by NVLink
- NVIDIA Turing / SM75, tensor parallel size 2
0.2.xtarget: CUDA 13.0, PyTorch 2.13, Python 3.12- Target host: Ubuntu 26.04 or later, Linux kernel 7 or later, GCC/G++ 15
Other Turing cards need independent validation for VRAM capacity, PCIe/NVLink topology, model head dimensions, KV-cache dtype, and CUDA Graph behavior.
❓ Hardware Q&A
What GPU interconnect is required?
NVLink is recommended. PCIe P2P is the baseline requirement, but narrow PCIe links without NVLink are not a proven substitute for the validated topology. Confirm P2P and benchmark the actual host topology before treating it as a deployment route.
Does the host need a strong CPU or a lot of RAM?
A high-end CPU is not required, but modern single-core performance and low platform latency matter. More RAM mainly helps builds, downloads, and compile cache. Very old CPU platforms can lower decode throughput even when the GPUs are unchanged.
Can 11 GB and 22 GB Turing cards be mixed?
Not for the documented 27B/35B TP=2 routes. Tensor parallelism is effectively limited by the smaller rank. Better alternatives are paired high-VRAM TU102 cards, such as TITAN RTX, Quadro RTX 6000, or Quadro RTX 8000, with NVLink or confirmed PCIe P2P and a separate profile validation.
Which CUDA and PyTorch versions apply?
The 0.2.x target is CUDA 13.0 with PyTorch 2.13. For the older CUDA 12.8 /
PyTorch 2.11 stack, refer to the unmaintained v0.1.x compatibility line. Keep
the PyTorch CUDA build, toolkit, FlashInfer/FlashQLA build, and selected profile
aligned; they are not interchangeable runtime combinations.
What other hardware risks matter?
Cooling, stable power delivery, and enough SSD capacity for weights and compile caches. Thermal throttling can look like a software performance regression, particularly during long prefill and repeated CUDA Graph/AOT compilation.
🔗 Related Project
- 2080Ti-LLM-Toolbox: companion toolbox for dual-2080-Ti model routes, benchmark summaries, model notes, and operational guidance. This repository focuses on the patched vLLM runtime.
🙏 Credits And Upstream Projects
This repository is a hardware-focused fork of vLLM, licensed under Apache-2.0. It keeps the upstream project structure and adds local SM75 runtime patches, launch profiles, and dual-2080-Ti validation notes.
Acceleration components used or integrated by this runtime include:
- vLLM: base inference engine and serving stack.
- FlashInfer: attention, sampling, and quantized kernel paths used by vLLM.
- QwenLM/FlashQLA: upstream Gated DeltaNet / Qwen hybrid linear-attention implementation.
- weicj/FlashQLA-SM70-SM75: SM70/SM75 adaptation used by the validated Qwen prefill route.
- TurboQuant, Marlin, CUTLASS, Triton, and related vLLM kernels.
Upstream updates are re-evaluated within the SM75-specific scope of this fork.